fix(core): time out stalled background agents - #11270
yiliang114 wants to merge 40 commits into
Conversation


|
Thanks — re-running the gate on the current head. This is a substantial change and I've read it closely rather than skimming. Template looks good ✓ — all nine headings present, including a real How to verify and a Risk & Scope section that names its own tradeoff. Problem: real, but be clear about where the evidence comes from. The PR body reports no testing at all — "Static diff review and formatting only. No local test, build, typecheck, or CI command was run" and all three OS rows marked not tested. On the PR body alone this would fail the reproduction bar. It doesn't fail, because @wenshao independently built both arms and drove a live daemon A/B at this exact head against merge-base Direction: aligned, and better-supported than most. #8586 is an open P2 tracking issue carrying Size: core paths are touched ( Approach: the mechanism is right; the packaging is what I'd question. This is two separable changes in one PR, and the body says so — "Included in this consolidated PR: runtime-generation draining and escalation for an Agent that ignores cooperative abort." The watchdog alone (a new module under Risk: Stage 1e matched — Moving on to code review. 🔍 中文说明感谢贡献 —— 本轮针对当前 head 重新跑门禁。这是一个体量不小的改动,我认真读了,没有略过。 模板完整 ✓ —— 九个标题齐全,包含真实的 How to verify 和主动说明取舍的 Risk & Scope。 问题: 真实存在,但要说清证据来源。PR 描述里完全没有测试 —— "只做了静态 diff 复核和格式化,未运行本地测试、build、typecheck 或 CI 命令",三个平台都标了未测试。单看 PR 描述,这一项过不了复现门槛。之所以没被判失败,是因为 @wenshao 独立构建了两个分支,并在完全相同的 head 上对 merge-base 方向: 对齐,而且支撑比多数 PR 更充分。#8586 是一个带 规模: 触及核心路径( 方案: 机制是对的,我想质疑的是打包方式。这是一个 PR 里装了两件可分离的事,描述自己也承认了 —— "已包含在当前合并后的 PR 中:runtime generation draining,以及 Agent 不响应协作式中止时的升级处理"。光是 watchdog 那一半( 风险: Stage 1e 命中 —— 进入代码审查 🔍 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
Code reviewI wrote my own proposal before opening the diff: a small watchdog module under Finding 1 —
|
| File | What changed |
|---|---|
docs/design/background-agent-progress-watchdog.md |
New design doc for the watchdog half; states the retry-extension rule that finding 2 shows the code does not implement |
docs/design/background-agent-progress-watchdog.zh-CN.md |
Chinese twin, cross-linked and structurally matched |
docs/design/background-agent-runtime-generations.md |
New design doc for the escalation and generation-draining half |
docs/design/background-agent-runtime-generations.zh-CN.md |
Chinese twin, cross-linked |
packages/acp-bridge/src/bridge.ts |
ChannelInfo gains a three-way state beside the derived isDying; adds the recycle request, the two-generation cap and the rollback-to-active recovery path |
packages/acp-bridge/src/bridge.test.ts |
Tests for generation state transitions and the recycle cap |
packages/acp-bridge/src/bridgeClient.ts |
Handles the new child-to-daemon recycle ext-method with owner-scoped validation |
packages/acp-bridge/src/bridgeErrors.ts |
Adds BridgeRuntimeRecyclingError with code runtime_recycling |
packages/acp-bridge/src/bridgeTypes.ts |
Adds the optional requestRuntimeRecycle method and rewrites the isChannelLive contract — see finding 3 |
packages/acp-bridge/src/status.ts |
Registers the sessionRuntimeRecycle control ext-method name |
packages/cli/src/acp-integration/session/Session.ts |
Record-only notification path that persists and recycles without a model turn; high-revert-correlation path |
packages/cli/src/nonInteractiveCli.ts |
Record-only items reach the SDK but are filtered out of the model batch |
packages/cli/src/serve/acp-http/dispatch.ts |
Maps the recycling error to a retryable 503 over JSON-RPC |
packages/cli/src/serve/acp-session-bridge.ts |
Re-exports the new error type |
packages/cli/src/serve/server/error-response.ts |
HTTP 503 retryable response shape for the recycling error |
packages/cli/src/ui/hooks/use-llm-stream.ts |
Interactive TUI drops record-only notifications entirely |
packages/cli/src/ui/utils/backgroundWorkUtils.ts |
Retained slots enumerate as blocking work with a still-stopping label |
packages/core/src/agents/background-agent-resume.ts |
Restored runs arm the same watchdog and map the abort reason to TIMEOUT |
packages/core/src/agents/background-tasks.ts |
Adds failUnresponsive, retainsPhysicalSlot, releaseRetainedPhysicalSlot and the recordOnly notification flag |
packages/core/src/agents/background-tasks.test.ts |
Registry tests for the escalation and slot-retention paths |
packages/core/src/agents/runtime/agent-core.ts |
Emits MODEL_RETRY and TOOL_PROGRESS, and maps a progress-timeout abort reason to TIMEOUT at four exit points |
packages/core/src/agents/runtime/agent-events.ts |
Two new event kinds plus retryDelayMs, waitingForExternalInput and the tool-progress payload |
packages/core/src/agents/runtime/agent-headless.ts |
Surfaces the timeout message as final text and swallows the abort error so TIMEOUT wins over ERROR |
packages/core/src/agents/runtime/agent-progress-watchdog.ts |
The watchdog itself — new module, 256 lines, two deadline classes plus the escalation grace |
packages/core/src/agents/runtime/agent-progress-watchdog.test.ts |
New 192-line spec covering arming, pauses, per-tool deadlines and drift rearm |
packages/core/src/core/llm-chat.ts |
Threads an onRetry callback through three call paths so backoff becomes observable |
packages/core/src/tools/agent/agent.ts |
Attaches and disposes the watchdog per turn, adds the escalation exit and the TIMEOUT outcome mapping |
packages/core/src/tools/tools.ts |
Two new display fields for the parked-on-approval and parked-on-input states |
Testing
This is an unattended CI run, so I did not build or execute any PR code — the review above is static, against the diff and the base tree in a read-only worktree. The evidence below is the PR's own CI, read through the API for head 93eef769a7986f936c426cd4caac53c3f6f20b16, plus one maintainer measurement I am attributing rather than adopting.
CI is settled and green. All four pull_request-event workflow runs completed successfully, and of 740 check-runs recorded on this head there are zero failures. The 14 cancelled checks are all named route and belong to the Qwen Autofix workflow on pull_request_review events — bot orchestration superseded by concurrency, not PR CI, so I am classing them as noise rather than a signal. macOS and Windows unit shards are skipped, as is the sandboxed CLI integration suite, so the green result is Linux-only.
| Check | Conclusion |
|---|---|
| Qwen Code CI (workflow) | success |
| Test (ubuntu-latest, Node 22.x) | success |
| Lint & Static (ubuntu-latest, Node 22.x) | success |
| Integration Tests (no-AK, No Sandbox) | success |
| Serve A/B (ubuntu-latest, Node 22.x) | success |
| Real daemon E2E / Java 11 | success |
| SDK Java (workflow, 5 matrix legs) | success |
| tui-parity — TUI parity snapshots (ink vs opentui) | success |
| OpenTUI no-flicker gate | success |
| web-shell E2E Smoke (ubuntu-latest, Node 22.x) | success |
| Desktop Shell (ubuntu-22.04, windows-2022) | success |
| Test (macos-latest, Node 22.x) | skipped |
| Test (windows-latest, Node 22.x) | skipped |
| Integration Tests (CLI, No Sandbox) | skipped |
| route (Qwen Autofix, pull_request_review) ×14 | cancelled — bot orchestration, not PR CI |
What the green suite does not establish. None of the PR's own tests pin the three findings above, and for finding 2 that is the point: the suite passes with restart-per-retry semantics because no test asserts a cumulative bound, so a green run cannot distinguish "extends the window" from "restarts it". Not verified by me, and the reasons: the retry-loop behaviour under default provider timeout (needs a live model that hangs and retries — not observable from a diff); the detach-reaps-a-live-tool behaviour (needs a real daemon and a real abort-ignoring process); and the cancel-inside-grace rewrite (needs a real timer race).
Attribution, not evidence: @wenshao's comment on this thread reports a full A/B against merge-base b5c7635ff9 on a live daemon and in the real TUI, and reports local runs of the PR's suites green (159 core, 941 acp-bridge). That is a maintainer's measurement, not something I re-ran, and I am citing it as the source for the behavioural claims in findings 1 and 2 rather than presenting it as my own testing. The author's PR body, separately, reports no testing at all.
Sandboxed verification would settle the two behavioural gaps: @qwen-code /verify — specifically that a retrying (not merely parked) provider stall is bounded by the watchdog under default generationConfig.timeout, and that a retained physical slot actually survives POST /session/:id/detach with the tool process still alive. Neither is observable from the diff and neither is pinned by the current suite, which passes with both behaviours as they stand. A run was already triggered on this head and was still in progress when I posted (run 34759206360); its report will land in this thread. @wenshao has measured both by hand, so the value here is turning a one-off manual measurement into a repeatable A/B rather than discovering anything new.
中文说明
代码审查
我在看 diff 之前先写了自己的方案:在 agents/runtime 下放一个小的 watchdog 模块,两个相互独立的期限(一个模型/控制,一个逐工具),挂到现有的 agent event emitter 上,通过该 turn 的 AbortController 协作式中止,映射到已有的 TIMEOUT 终止模式,一次性结算为 failed 并只通知父会话一次,且明确不进入重试 —— 而且我不会把"忽略中止后的升级处理"放进同一个 PR。watchdog 这一半几乎逐点对上了我的方案,包括复用 AgentTerminateMode.TIMEOUT 而不是新造一个状态。我和它的分歧在打包方式(Stage 1 已说)和下面某一个设计决定。
发现 1 —— retainsPhysicalSlot 被三个判定接受、被第四个漏掉(阻塞项,即 @wenshao 的 §7)。 新标志接进了 background-tasks.ts 的 getRunningBackgroundCount()、hasRunningTasks()、pruneTerminalEntries(),以及 backgroundWorkUtils.ts 的 describeBlockingBackgroundWork(),但没有接进 listUnfinalizedBackgroundAgentIds() —— 而后者的 base 注释明确承诺 daemon 的 active-work 快照取自"registry 自己会报告的同一个集合,不会有第二本账漂移",且 hasUnfinalizedTasks() 刻意与它共用判定。Session.collectActiveWorkHolds()(Session.ts:4084-4089)正是从它派生,而且它自己的注释把这个选择写成了刻意为之:"hasUnfinalizedTasks() 的判定 —— 而不是 hasRunningTasks() 的 —— 支撑 agent 这一类"。本 PR 加强的恰恰是 hasRunningTasks(),也就是这条路径明确不读的那个判定。
这个 registry 方法只有一个生产调用方,但该调用方会扇出:除 daemon 保留路径外,它还支撑 Session.isIdle()(:4061)和 hasStandaloneRelocationBlockers()(:4154-4156,把关 session/cd 迁移),以及 acpAgent.ts 里三处 onlyIfUnheld 条件关闭读取(:4512、:4529、:4576)。所以这个缺口比单纯的 detach 更宽。
具体来说:一个 failed + 已通知、但工具进程仍真实存活的条目,会在 retainsPhysicalSlot 仍为真时掉出 daemon 的 hold 集合。新增的 failUnresponsive 注释声称保留槽位能阻止 /clear、/resume、/branch 和会话切换越过存活工作 —— 它确实保住了 TUI 侧的拦截(@wenshao 实测有效),但保不住 daemon 的保留路径:§7 实测升级后立即 detach 会关闭 Session、draining generation 退出、忽略中止的工具进程在自然结束前就消失,而 base 会把 Session 撑到工具跑完。对"慢但仍存活"的工具来说,这是相对 base 的破坏性差异。
这正是 AGENTS.md 要求对每个新增字段做的读点排查。两条路都可以(把保留槽位计入 hold,或者在不变量注释和设计文档里写明保留槽位不撑过 detach、这就是预期补救),但不能默默选一条。这就是 R6-6b 待裁定的内容。
发现 2 —— 重试之间没有累计上界,因此默认 provider 配置下标题所述的卡死形态依然存在(阻塞项,即 @wenshao 的 §9)。 armModel(retryDelayMs) 会先 clearModel() 再排一个 15 分钟 + Math.min(retryDelayMs, 6 小时)。所以每次 MODEL_RETRY 都重开了基准的 15 分钟窗口,实际语义变成"距上次重试 15 分钟",而不是"15 分钟没有进展"。默认 generationConfig.timeout 是 120 秒,挂起的上游大约每两分钟被中止重发一次 —— 远在窗口之内 —— 于是模型期限永远不到期。@wenshao 实测 head 在 t=1106 秒(18.4 分钟)仍是 running,与 base 无从区分,共 12 次尝试且重试循环仍未放弃。两点要分开看:一是 PR 声称要解决的问题("普通后台 Agent 可能无限卡住并持续占用 Session、永远没有终态")在默认配置下对维护者所称最常见的卡死形态仍然可复现 —— 这不是回归(base 行为相同),所以我不叫它破坏,我叫它目标未达成;二是 MAX_RETRY_DEADLINE_EXTENSION_MS(6 小时)看起来像总预算,实际只夹住单次重试追加的延迟,而真实 retryDelayMs 是秒到分钟级,那个 Math.min 永远不可能生效,所以这个常量基本是装饰性的,代码里任何地方都没有累计上限。设计文档写的"qwen-code 暴露的重试延迟最多把模型期限延长六小时"暗示了一个实现里并不存在的上界。修法是决策而不是 diff:要么把当前窗口延长 retryDelayMs(这样 6 小时上限成为真实的累计预算,也和文档一致),要么保留重开语义并改正文档。与 R6-3 / R6-6a 重叠。
发现 3 —— isChannelLive() 被改写的契约与其未变的实现自相矛盾(本轮新发现,建议合并前修)。 bridgeTypes.ts 把接口注释从"当前是否有存活的 ACP channel(已 spawn 且未 dying)"改成"是否有active 且能接受新工作的 ACP channel……而 draining 代仍拥有既有 session 但不能接受新工作"。但实现仍然委托给 liveChannelInfo(),而 PR 只是把它从块体改写成表达式体 —— channelInfo && !channelInfo.isDying —— 且 isDying 现在是 state === 'dying' 的派生 getter。所以 isChannelLive() 对 draining 代返回 true,而新注释说 draining 代不能接受新工作。这段注释描述的其实是真正新增的 admissibleChannelInfo(),而被它记录的那个方法仍然在报告"存活"。行为没变,所以今天不会坏。问题在于这是大约八个生产调用点的公开契约 —— daemon-status.ts:679/716(聚合 child RSS 的分子和分母)、routes/health.ts:92(runtimeChannelAlive)、workspace-service/index.ts:406/474/489/553/560/581/854/975(acpChannelLive 信封字段与预热判定),外加 server.ts:1314 和 run-qwen-serve.ts 三处。这些消费方要的是存活;而注释现在告诉下一个作者这个方法表示可接纳,于是在 drain 期间照着 true 去接纳新工作,正好会产出调用方没预料到的 503。要么恢复"存活"的措辞,要么把 isChannelLive() 改接 admissibleChannelInfo() 并逐一复审上述所有调用点 —— 两者不可互换。这与仍未解决的 R1-36 相邻,但不是同一处。
不阻塞,但值得看: attachAgentProgressWatchdog 重新实现了 workflow-stall.ts 里 attachStallWatchdog 的 arm/clear/dispose/事件订阅骨架;PR 给的理由("它会重试,并对所有运行中的工具暂停计时")只对了一半 —— 重试在 runStallResilient 包装器里,attachStallWatchdog 本身只负责中止并报告 stalled()。逐工具期限的需求确实和那个原语的一刀切暂停(if (inFlightTools > 0) return;)分道扬镳,所以单独一个模块站得住,但两者现在已经有彼此都没提到的差异(新的有防漂移重排,旧的没有),建议在两边各加一句交叉引用。另外 armModel() 会在每个 STREAM_TEXT 分片上触发,每次做一遍 clearTimeout + setTimeout + O(tools) 扫描,忙流下是实打实的定时器抖动;存一个 deadline 配单个定时器、用 performance.now() 比较会更省,workflow-sandbox.ts 里的 WallClockWatchdog 就是这个写法。MODEL_RETRY 在 agent-core.ts 有两处发射点(新的 onRetry 选项和 streamEvent.type === 'retry' 分支),所以一次重试可能发两次 —— 按现在的写法无害(重排是幂等的,forwardProgress 有 1 秒节流),但为什么两处都需要并不显然。record-only 路径在交互式 TUI 里完全不可见(use-llm-stream.ts 对 meta?.recordOnly 直接 return),用户只能从 /tasks 或 /clear 拦截得知有 Agent 被强制结算 —— 已作为 R1-9 跟踪,之所以提是因为这是升级处理那一半唯一的用户可见信号。另外 BridgeRuntimeRecyclingError 不在 KNOWN_ERROR_TYPES(packages/core/src/telemetry/daemon-metrics.ts:25-47)里,所以 normalizeErrorType() 会把每次发生都归进 daemon.bridge.error.count 的 unknown 桶,而不是具名统计。这个很小,而且那份清单本来就不穷尽 —— WorkspaceDrainingError 和 DaemonDrainingError 也不在里面 —— 所以漏掉很可能是有意的;但 recycle 引发的 503 恰恰是运维最想与"真正未知的 bridge 错误"区分开的事件。
我查过并且认为没问题的部分(记下来,免得上面的发现被读成对整个改动都没信心):watchdog 只在 runBackgroundTurn 内挂载,而它只有两个调用点 —— 后台首次启动和驻留热继续;前台路径注册的是 isBackgrounded: false,根本到不了这里,workflow dispatch 走的是 workflow-orchestrator / workflow-stall,所以"workflow dispatch 保持不变"这个说法成立。isDying 变成新 state 字段上的 getter/setter 是对的做法 —— 单一真相源,且 setter 只写真值恰好匹配所有现存赋值点(代码里没有任何 isDying = false)。agent-headless.ts catch 块里新增的提前 return 处在 try/catch/finally 结构中,finally 仍会发出 FINISH、打点并调用 onStop,收尾没有被跳过;错误是被刻意吞掉的,好让 TIMEOUT 压过 ERROR,而 agent.ts 的成功路径也相应改了。nonInteractiveCli.ts 里 modelBatch.length === 0 的提前返回位于 splice 和 emitNotificationToSdk 之后,所以 record-only 项仍会到达 SDK 消费方,队列不会漏。bridgeClient.ts 对新的 recycle ext-method 做了 owner 作用域校验(ownsSession、resolveEntry,以及精确的 reason === 'unresponsive_agent')才派发 —— 对一个 live-session-owner 路由来说这是正确的作用域归类。防漂移的 schedule()(事件循环超过一秒才执行时重排而不是直接触发)是很用心的防御,参考 agent 的 CHANGELOG 说明这个失效模式是真实存在的("主机休眠或 macOS App Nap 后的 worker-stall 误报风暴")。还有一点:复用 AgentTerminateMode.TIMEOUT 比表面上看更好 —— 这个枚举成员本来就存在,但对 agent 工具启动的后台 Agent 实际上不可达,因为没有任何地方给它们设 max_time_minutes。本 PR 是让一个闲置的枚举值真正起作用,而不是新增一个,并且正确地没有去动 registry 的 TaskStatus 词汇 —— 那是一份线上契约,在 tasksSnapshot.ts:409 被硬校验,还镜像进了 acp-bridge/src/status.ts 和 TypeScript SDK,所以在那里加一个 timeout 状态会是跨包的破坏性变更。
测试
这是无人值守的 CI 运行,所以我没有构建或执行任何 PR 代码 —— 上面的审查是静态的,基于 diff 和只读 worktree 里的 base 树。下面的证据是 PR 自己的 CI,通过 API 读取 head 93eef769a7986f936c426cd4caac53c3f6f20b16 的结果,外加一项我明确标注来源、不据为己有的维护者实测。
CI 已跑完且全绿。四个 pull_request 事件的 workflow run 全部成功完成,该 head 上记录的 740 个 check-run 中零失败。14 个 cancelled 全部名为 route,属于 pull_request_review 事件上的 Qwen Autofix workflow —— 是被并发取代的 bot 编排任务,不是 PR CI,所以我把它归为噪音而非信号。macOS 和 Windows 单测分片是 skipped,沙箱化的 CLI 集成套件也是 skipped,所以这个绿色结果只覆盖 Linux。
绿色套件没有证明什么。 上面三个发现都没有被 PR 自己的测试钉住;对发现 2 来说这恰恰是关键 —— 套件在"每次重试重开窗口"的语义下能通过,因为没有任何测试断言累计上界,所以绿色的运行无法区分"延长窗口"和"重开窗口"。以下由我明确标注为未验证及原因:默认 provider 超时下的重试循环行为(需要一个会挂起并重试的真实模型,从 diff 看不出来);detach 回收存活工具的行为(需要真实 daemon 和真实的忽略中止进程);宽限窗内取消被改写(需要真实的定时器竞态)。
归属声明,不是证据: @wenshao 在本帖的评论报告了对 merge-base b5c7635ff9 的完整 A/B(真实 daemon + 真实 TUI),并报告本地跑 PR 自带套件为绿(core 159、acp-bridge 941)。那是维护者的实测,不是我重跑的结果;我引用它是作为发现 1 和发现 2 中行为性论断的来源,而不是当作我自己的测试。另外,作者的 PR 描述本身报告的是完全没有测试。
沙箱验证可以闭合这两个行为缺口: @qwen-code /verify —— 具体是验证在默认 generationConfig.timeout 下一个重试中(而非仅仅挂起)的 provider 停滞确实被 watchdog 兜住,以及一个保留的物理槽位确实在工具进程仍存活时能撑过 POST /session/:id/detach。这两点都从 diff 看不出来,也都没有被当前套件钉住 —— 套件在这两种行为保持现状的情况下照样通过。本 head 上已经触发了一次运行,我发帖时仍在进行中(run 34759206360),报告会落到本帖。@wenshao 已经手工测过这两项,所以这里的价值是把一次性的人工实测变成可重复的 A/B,而不是发现新东西。
— Qwen Code · qwen3.8-max-2026-09-02
Reviewed at 93eef769a7986f936c426cd4caac53c3f6f20b16 · re-run with @qwen-code /triage
|
Confidence: 3/5 — the mechanism is sound and a maintainer has already measured it working end to end, but two of the three findings are about the watchdog not covering the case it exists for, and Stage 0's core-size escalation caps this at 3/5 regardless. Stepping back. The watchdog half of this PR is good work. I proposed essentially the same design before reading the diff and the author arrived at the same place independently — same two-deadline shape, same cooperative abort, same reuse of the existing So why not approve. My honest read is that findings 1 and 2 are not hygiene. Finding 2 means that under default provider configuration — the configuration almost every user actually runs — a hung upstream gets retried every two minutes and resets the fifteen-minute window each time, so the watchdog never fires. The maintainer measured eighteen and a half minutes with head indistinguishable from base. The PR exists to stop background Agents wedging indefinitely, and for the most common wedge shape it still does. That is not a regression and I have not called it one, but "ships a watchdog that does not watch the common case" is a substantive gap, not a nit. The Finding 1 is subtler and, to me, more worrying, because it is the exact failure the base code warned about in a comment. Finding 3 is smaller but cheap to fix and worth fixing here rather than later: the PR rewrote a public interface doc to describe a different method than the one it documents, across roughly eight production call sites that want liveness rather than admissibility. Now the part that is not about the code. This PR is far past the point where AGENTS.md says to stop widening it — new findings were minted in R1, R6 and R9, six Critical threads are unresolved at this head, and the author has said plainly and reasonably that they will not pick a side on §6, §7 or §9 without a ruling, because picking one silently means guessing at intent on concurrency semantics. I agree with that stance. It is also why I am not submitting a fresh request-changes review: the bot's own ⏸️ Escalating to @wenshao — this needs a human call, and you are the right human. I am not approving, for two independent reasons. The policy reason: 1006 production lines across core paths trips Stage 0's maintainer-awareness threshold, which caps this run at 3/5 and forbids an automatic approval no matter how clean the review looked — noting that you are a maintainer, so this is the gate's own rule about large core changes rather than a judgement on authorship, and AGENTS.md's external-PR exemption means I am flagging for awareness rather than blocking. The substantive reason: three decisions are yours and cannot be derived from the diff.
Also unresolved and not covered by your validation: R1-36, Two mechanical notes. You have already APPROVED at this head (13:12:33Z); If the three rulings come back as "restart semantics are intended, detach reaping is intended, cancel rewrite is intended — fix the docs and comments to say so", then findings 1 and 3 collapse to documentation and I would re-run happily at 4/5. Finding 2's doc fix is cheap; the question is whether the uncovered stall shape is acceptable to ship against, and that is a product call, not a code call. 中文说明信心:3/5 —— 机制是可靠的,维护者已经端到端实测它能工作;但三个发现中有两个是关于 watchdog 没有覆盖它本该覆盖的场景,而且 Stage 0 的核心规模升级本身就把本轮封顶在 3/5。 退一步看整体。这个 PR 的 watchdog 那一半是好工作。我在读 diff 之前先写了自己的方案,作者独立走到了同一个地方 —— 同样的双期限结构、同样的协作式中止、同样复用已有的 那为什么不批准。 我的真实判断是:发现 1 和发现 2 不是代码卫生问题。发现 2 意味着在默认 provider 配置下 —— 也就是几乎所有用户实际在跑的配置 —— 挂起的上游每两分钟被重试一次,每次都重开十五分钟窗口,于是 watchdog 永远不触发。维护者实测十八分半,head 与 base 无从区分。这个 PR 存在的意义就是阻止后台 Agent 无限卡住,而对最常见的卡死形态它依然没有做到。这不是回归,我也没有把它叫作回归,但"发布了一个不看常见场景的 watchdog"是实质性缺口,不是小毛病。 发现 1 更微妙,在我看来也更值得担心,因为它正是 base 代码在注释里明确警告过的失效方式。 发现 3 小一些,但修起来便宜,值得现在就修而不是以后:PR 把一个公开接口的注释改写成在描述另一个方法,而受影响的是大约八个生产调用点,它们要的是"存活"而不是"可接纳"。 接下来说与代码无关的部分。这个 PR 已经远远越过 AGENTS.md 所说的"该停止扩大范围"的临界点 —— R1、R6、R9 三轮都新铸了发现,本 head 上有 6 条 Critical 线程未解决,而作者已经明确且合理地表态:在没有裁定之前不会在 §6、§7、§9 上挑一边,因为默默选一边就等于在并发语义上猜意图。我认同这个立场。这也是我不提交新的 request-changes review 的原因:bot 自己的 ⏸️ 升级给 @wenshao —— 这需要人来裁定,而你是合适的人。 我不批准,有两个各自独立的理由。规则层面:1006 行核心路径生产代码触发了 Stage 0 的"需维护者知悉"阈值,这会把本轮封顶在 3/5 并禁止自动批准,无论审查看起来多干净 —— 需要说明你是维护者,所以这是门禁针对大规模核心改动自身的规则,不是对作者身份的评价,而 AGENTS.md 的外部 PR 免除条款意味着我这里是提示知悉而非拦截。实质层面:有三个决定属于你,且无法从 diff 推导出来。
另外仍未解决、且你的验证没有覆盖的:R1-36,drain 期间作用于替换代的 两点流程说明。你在本 head 上已经 APPROVED(13:12:33Z); 如果三个裁定回来是"重开语义是预期的、detach 回收是预期的、改写 cancel 也是预期的 —— 把文档和注释改成这么说",那么发现 1 和发现 3 就降级为文档问题,我很乐意在 4/5 重跑一轮。发现 2 的文档修正很便宜;真正的问题是那个未被覆盖的卡死形态是否可以带着发布,而那是产品判断,不是代码判断。 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |

 qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Needs some rethinking before this goes further — see my notes above. 🙏
Two paths abort a healthy Agent: the 15-minute model deadline fires during transport rate-limit backoff (invisible to the watchdog, and llm-chat's delay() honours the abort, so it interrupts a retry that was working as designed), and a tool that executes without streaming output stays queued and gets charged to that same model deadline. Since the contract is settle-once with no retry, a false positive doesn't degrade a background Agent, it destroys it and reports a misleading reason.
Nothing has executed this code either: no tests were added for the new 202-line timing module, and because ci.yml gates pull_request on base main or release/**, no CI ran on a feature-branch base. #11273 is already stacked on this head branch, so both findings propagate upward.
The design is right — I'd rather see it land with those closed than see it rewritten.
— Qwen Code · qwen3.8-max-2026-09-02

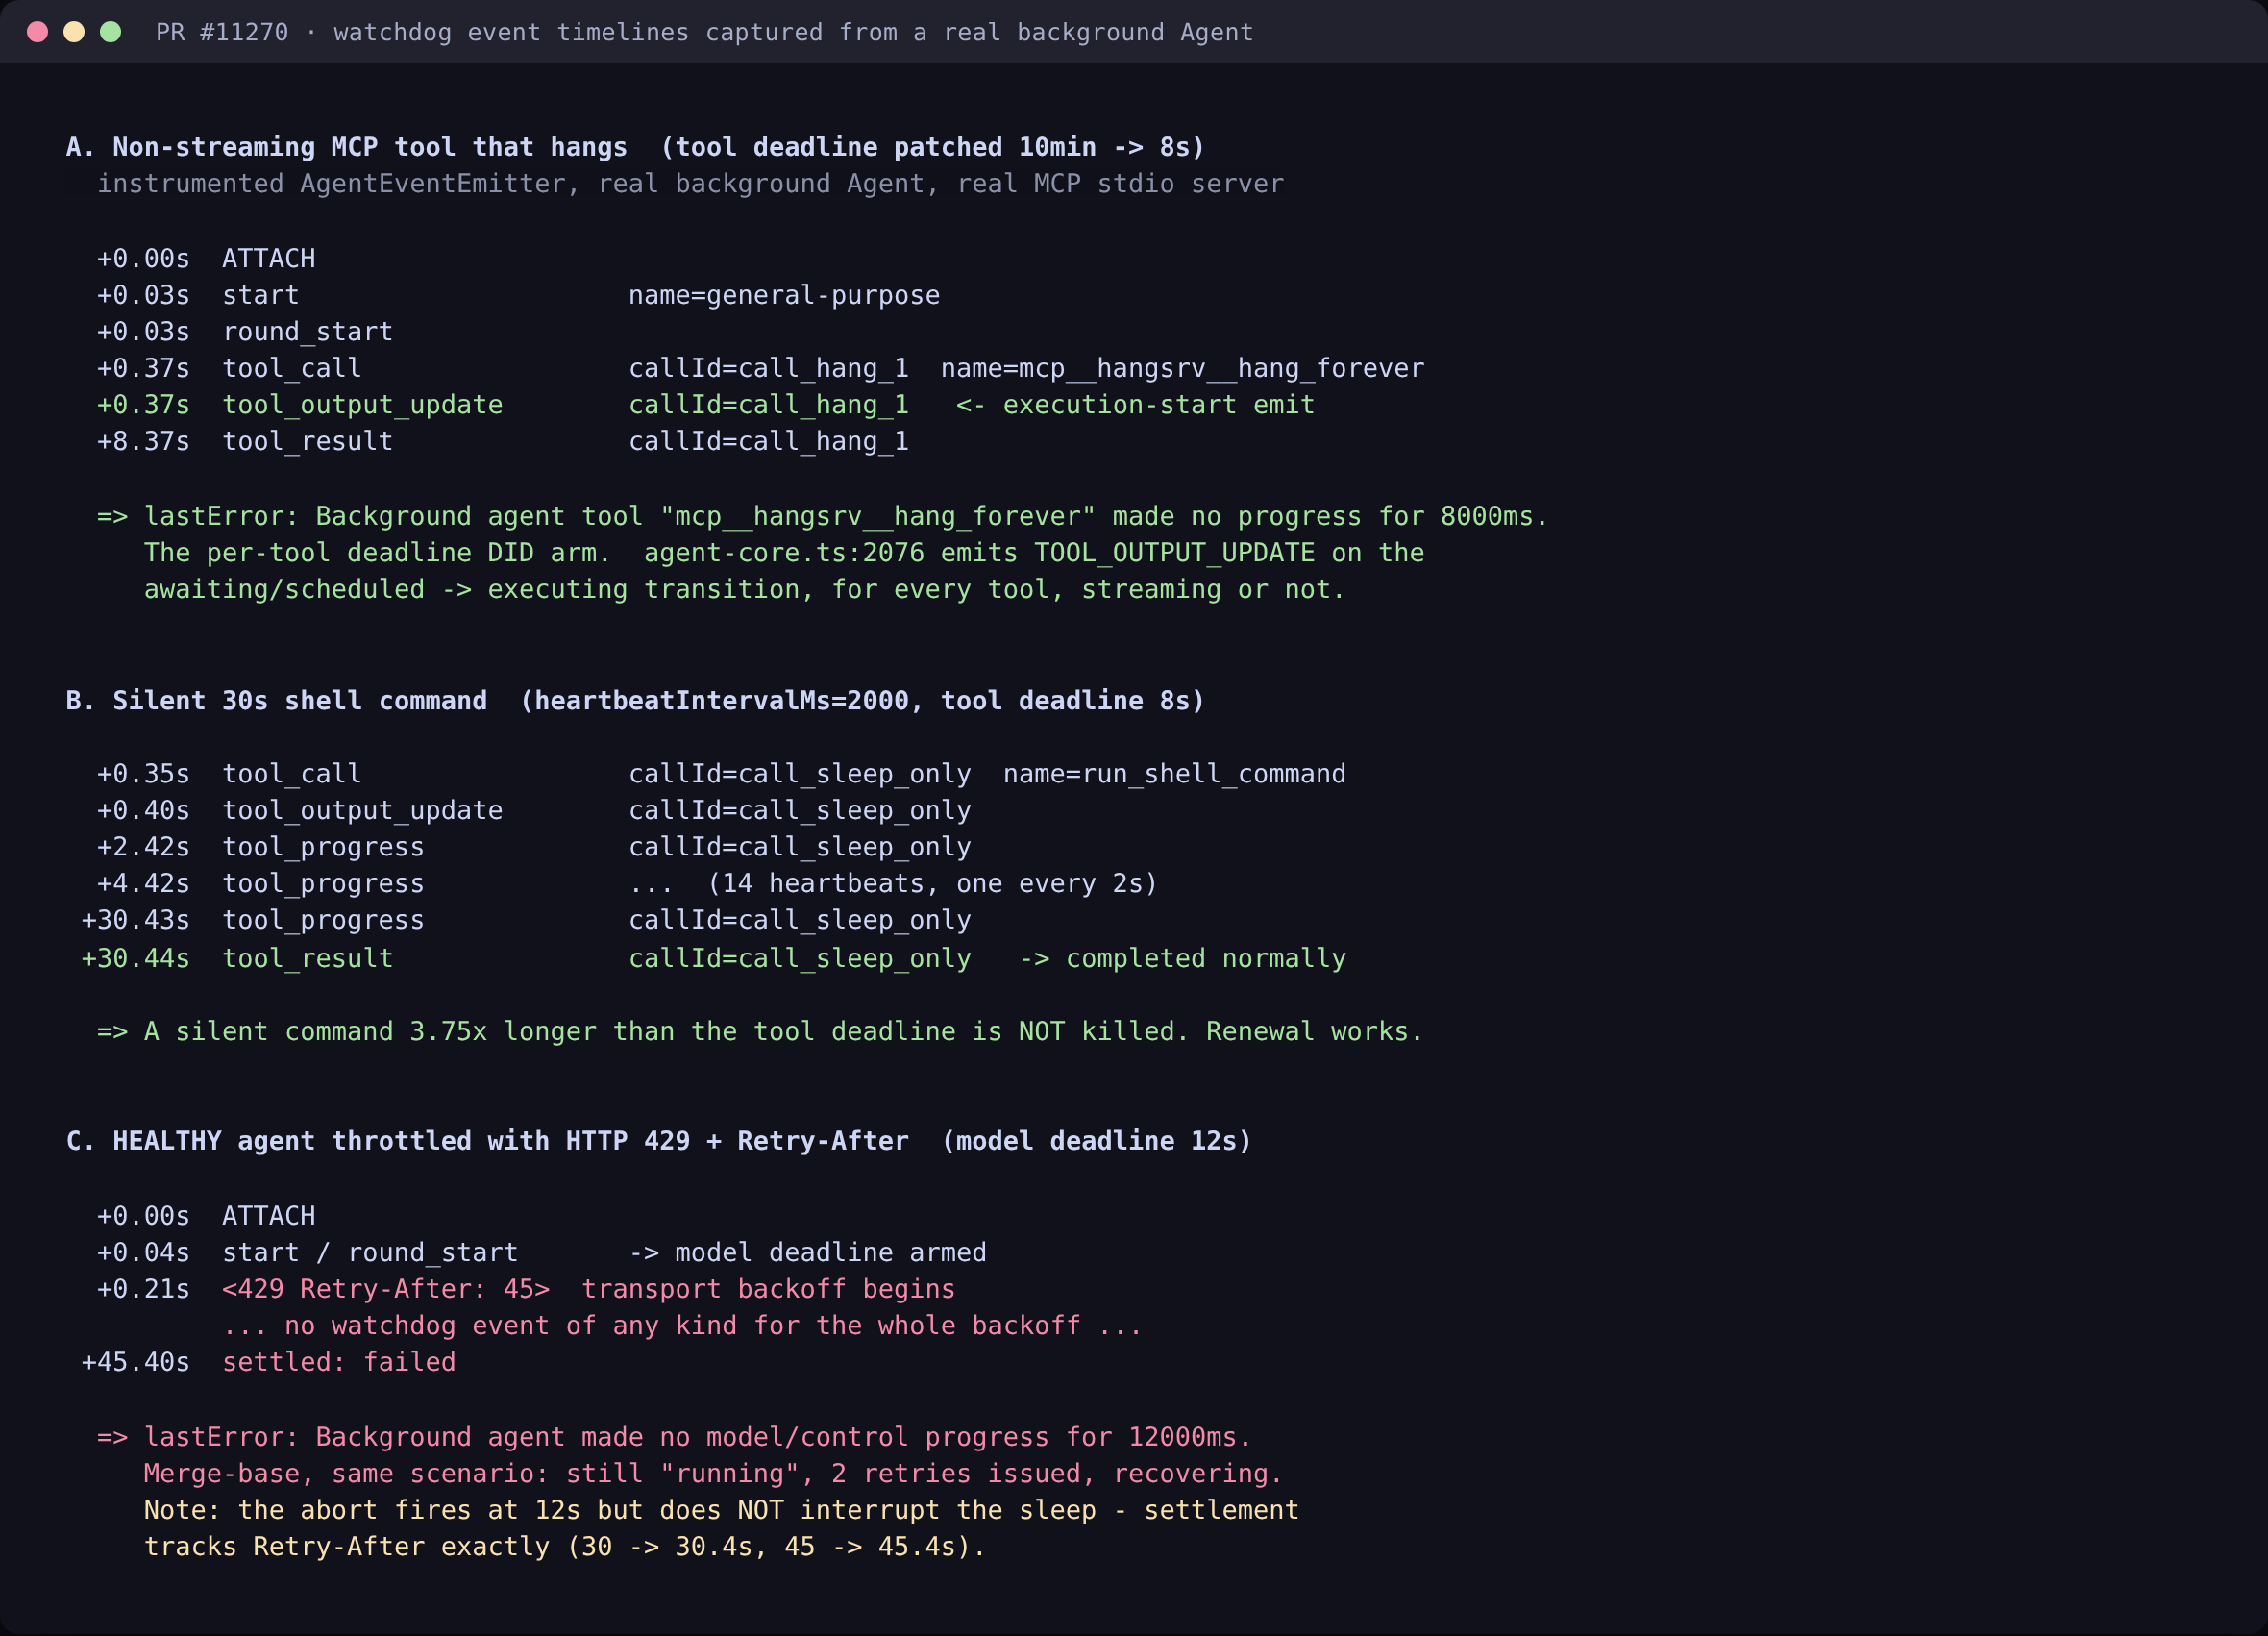
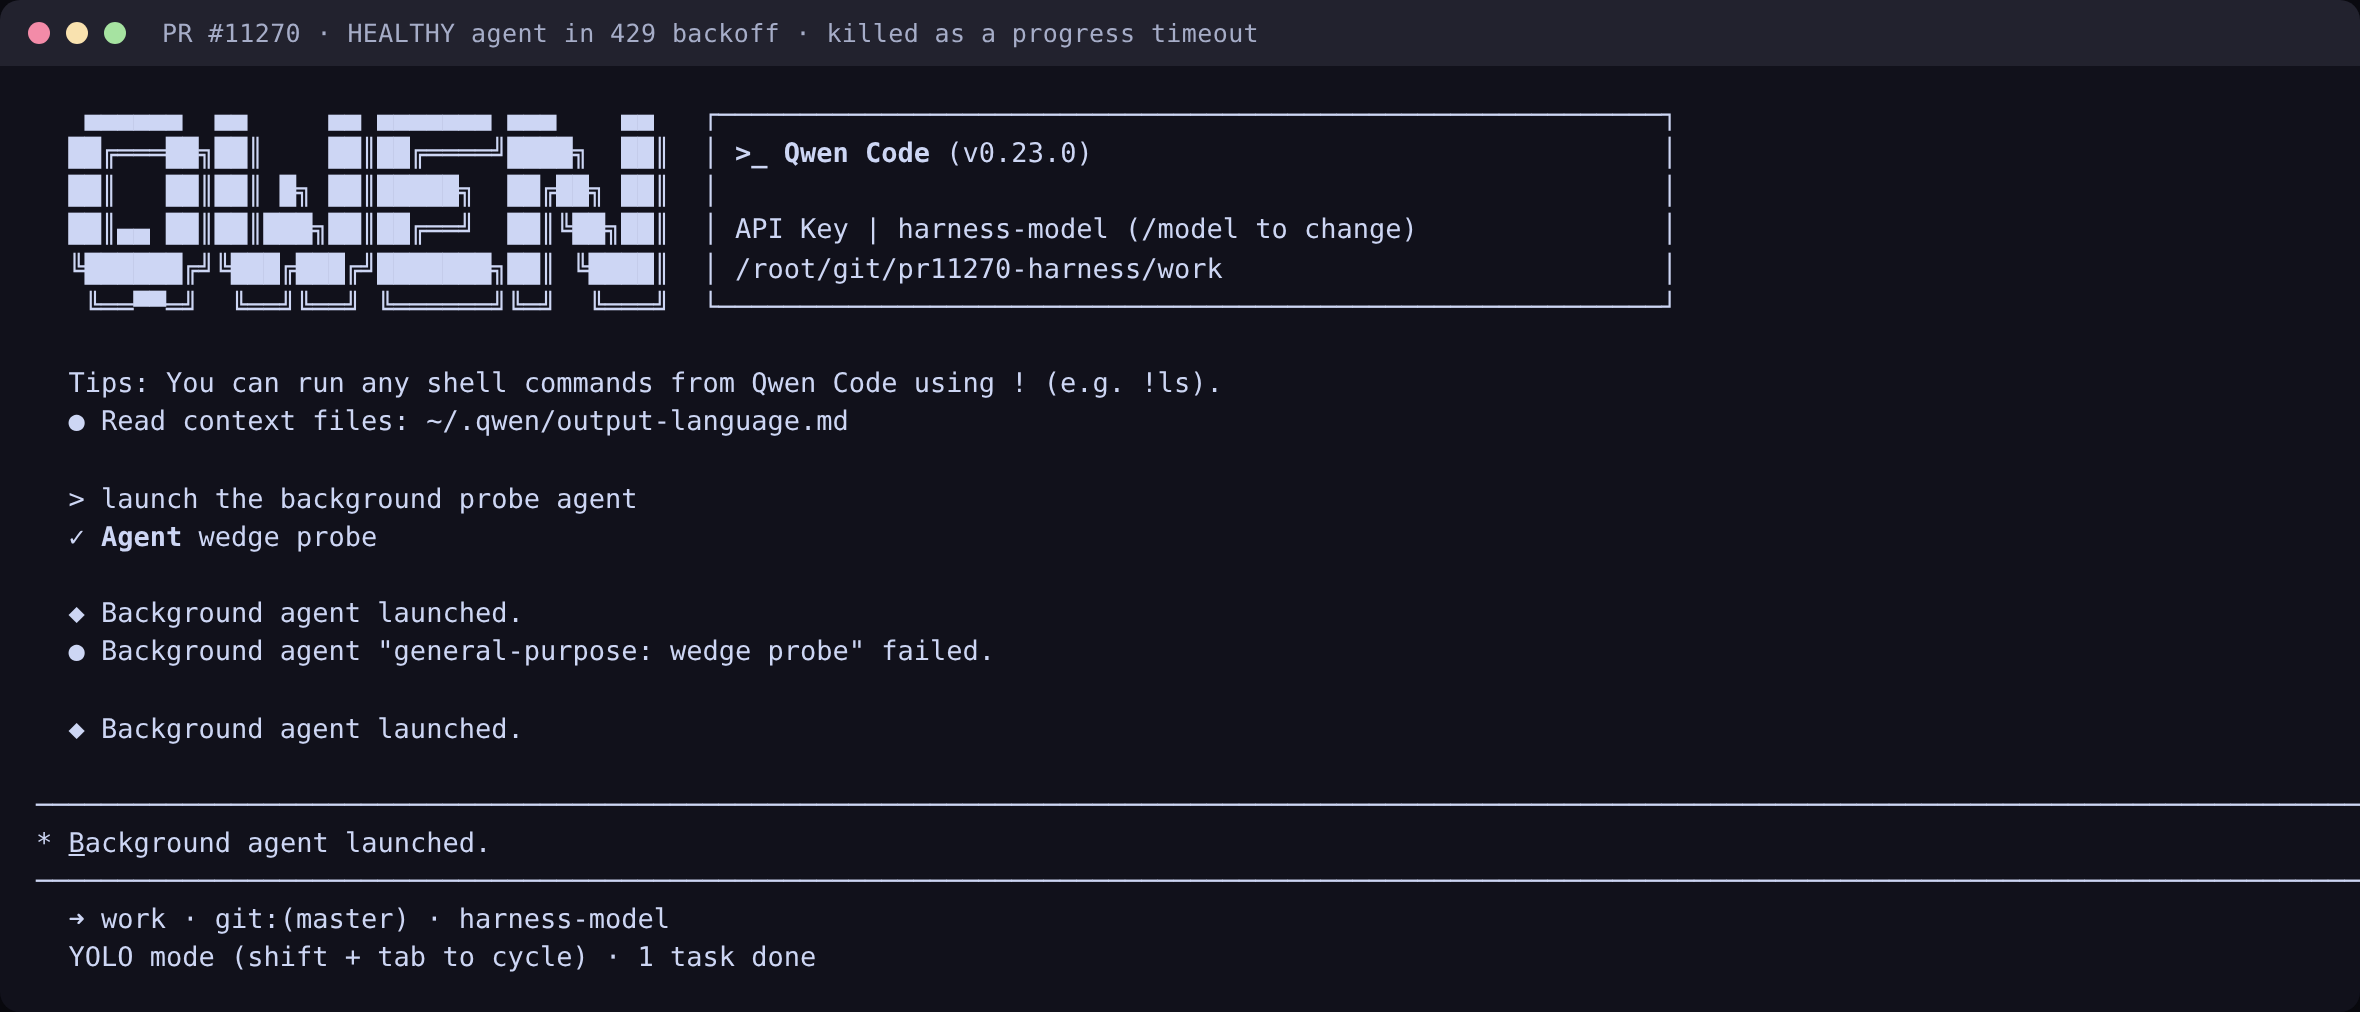
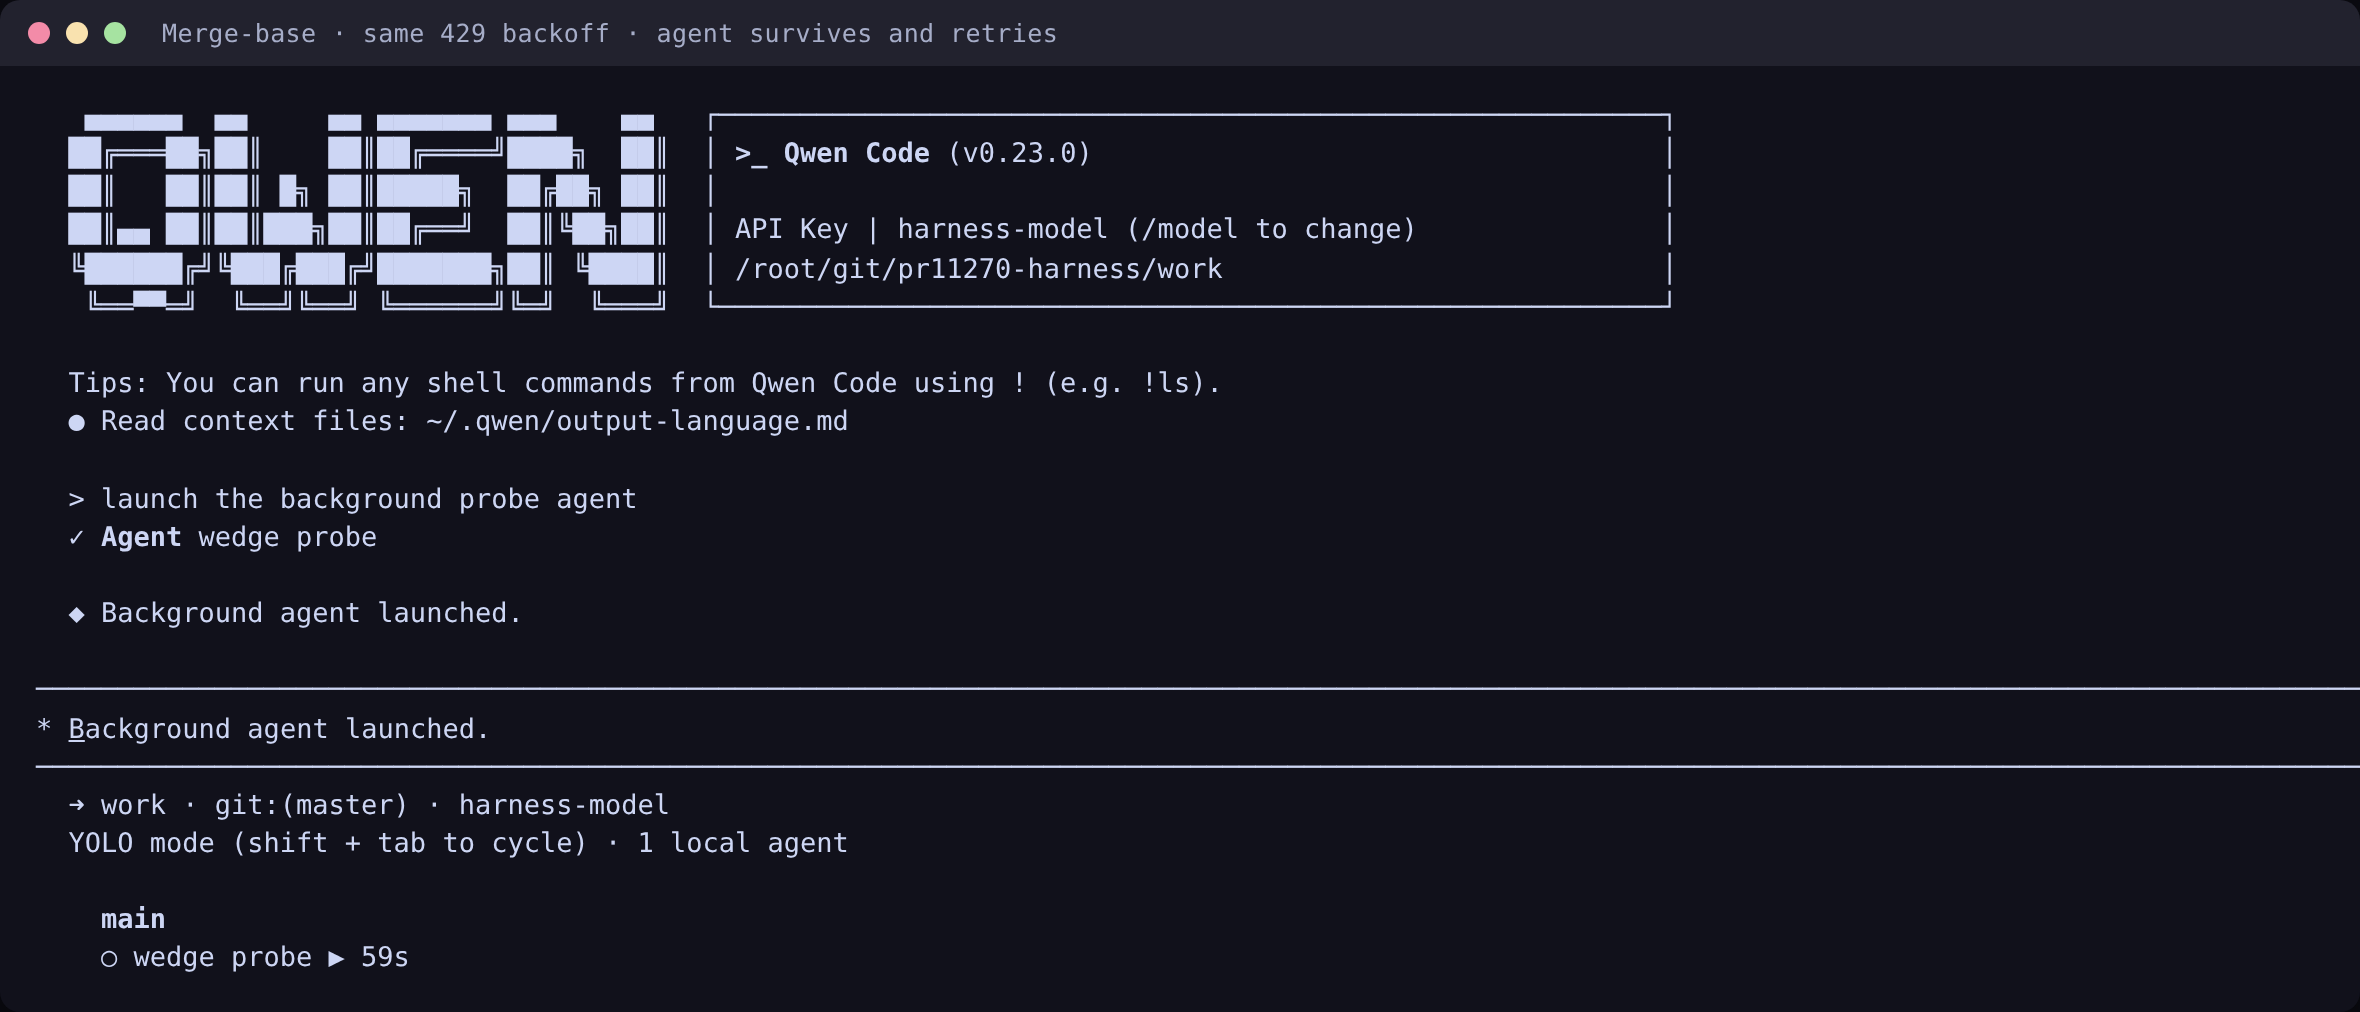
Runtime verification of PR #11270 (maintainer review)I built a real local environment and ran this PR end-to-end against a real background Agent, rather than reviewing the diff. Reviewed at Verdict: the mechanism works and is wired correctly, but one scenario is a regression that I think blocks merge — a healthy background Agent sitting in ordinary HTTP 429 transport backoff is killed and settled as
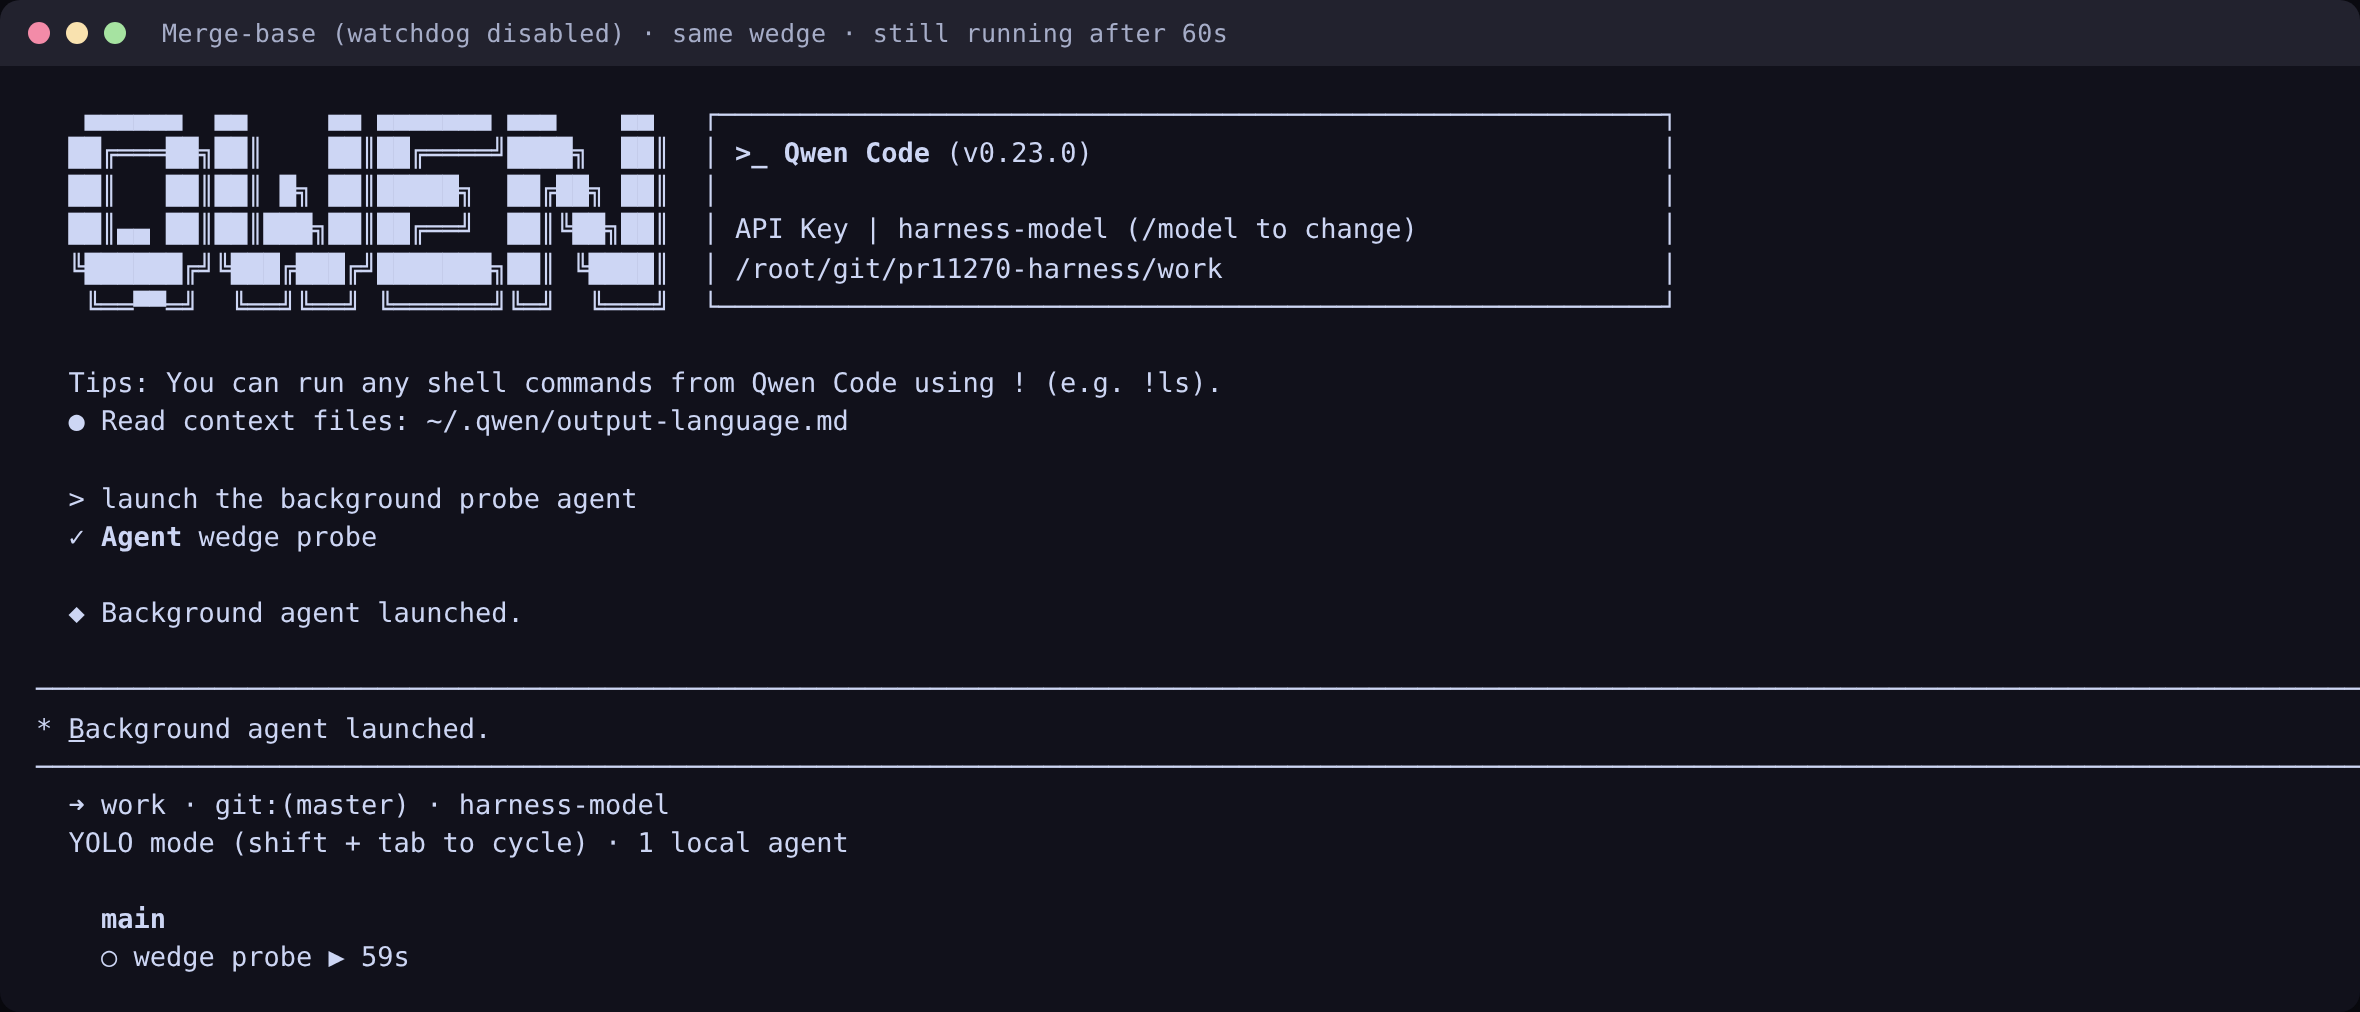
HarnessReal The merge-base arm is the same bundle with A separate instrumented arm subscribes a logger to all eleven events the watchdog listens for, so the state machine's inputs are captured directly rather than inferred. What I verified works
The whole chain holds: watchdog →
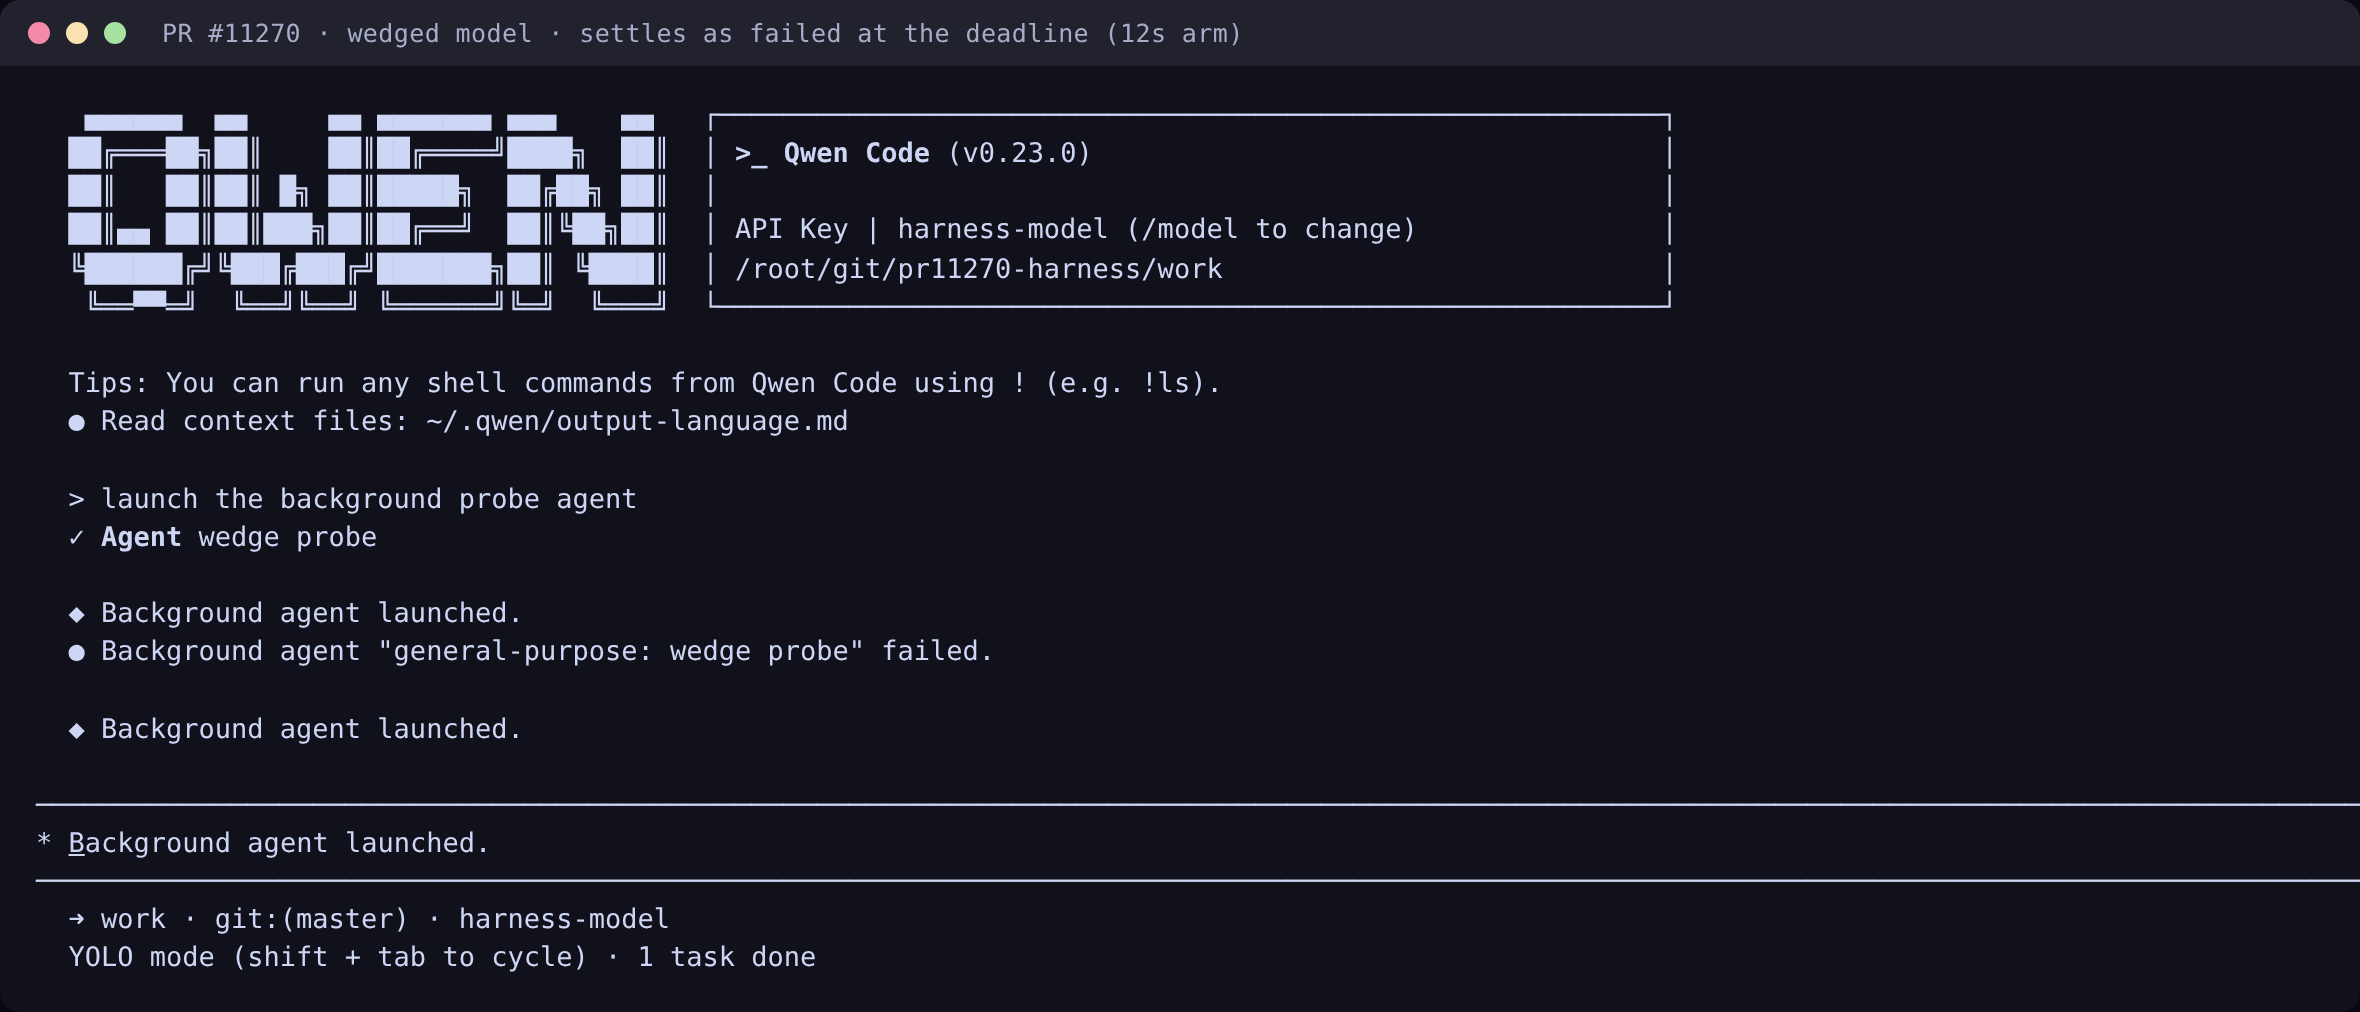
The Blocking: a healthy Agent in transport backoff is killedScripted the subagent's provider to answer
One correction to the static review's mechanism. It states that Either emit an event from the Refuted: Finding 2 (silently-executing tools charged to the model deadline)The static review argues that only tools streaming live output ever reach
Worth noting as a fragility rather than a bug: the tool deadline is armed by an event whose stated purpose is UI, and neither the code nor Other measured resultsThe rearm heuristic roughly doubles the deadline per event-loop stall, unbounded. Driving the compiled module with the constants replaced by 9s (drift guard untouched):
Prettier. Confirmed: 4 files fail Typecheck / tests. Confirmed as designed, but undocumented. Both pauses are unbounded — I drove a parked approval for a simulated 60 minutes with no timer running at all. That is probably right (an outer wall-clock limit covers it), but the design doc should say so rather than leave it looking like the original symptom relocated. RecommendationThe problem is real, the architecture is sound, and the plumbing is genuinely careful — the typed abort reason, the
Harness details & limitations
中文版PR #11270 真机验证报告(维护者复核)我没有只读 diff,而是在本地搭了真实环境,用真实后台 Agent 端到端跑了这个 PR。验证提交: 结论:机制本身可用、接线正确,但有一个场景是回归,我认为阻塞合并 —— 一个健康的后台 Agent 只要处在普通的 HTTP 429 传输退避中,就会被杀掉并永久结算为 验证环境用 PR head 构建的真实 merge-base 对照臂是同一个 bundle,把 另有一个插桩臂,把日志订阅到 watchdog 监听的全部 11 个事件上,直接捕获状态机的输入,而不是靠推断。 验证通过的部分
整条链路成立:watchdog → 在 turn controller 上抛
阻塞项:健康的 Agent 在传输退避中被杀让子 agent 的 provider 返回
对静态审查机制描述的一处订正。 该审查称 修法二选一:在 已推翻:Finding 2(静默执行中的工具被算到模型期限)静态审查认为只有会流式输出的工具才会进入
值得作为脆弱点(而非 bug)记录:工具期限是被一个用途为 UI 的事件启动的,代码和 其他实测结果rearm 启发式每遇一次事件循环卡顿就大致翻倍期限,且无上界。 用常量替换为 9s 的编译模块驱动(drift 判据保持原样):
Prettier。 已确认:PR head 上有 4 个文件 Typecheck / 测试。 确认为设计如此,但缺文档。 两个暂停都是无界的——我让一个停在审批上的工具跑了模拟 60 分钟,期间没有任何定时器在运行。这大概率是对的(外层墙钟限制兜底),但设计文档应当写明,否则读起来像是原来的症状换了个地方继续存在。 建议问题真实,架构合理,管线处理确实细致——带类型的 abort reason、fork 与非 fork 两条分支上的
验证环境的边界: 期限在构建产物里缩短为 12s/8s(仅常量);rearm 阶梯用的是常量替换为 9s、drift 判据未动的编译模块副本;merge-base 臂是把 |

|
Addressed the two current-head correctness findings in |
… into codex/issue-8586-runtime-generations
…ions' into codex/issue-8586-unresponsive-agent
… into codex/issue-8586-runtime-generations
…ions' into codex/issue-8586-unresponsive-agent
🩺 serve daemon A/BBuilt the PR base vs this PR head ✅ No response changes against the PR base across 12 scenario(s). — Qwen Code · serve A/B |

An approval-pending background agent was still charged the 15-minute
model deadline, so a user who parked an approval for longer than that
got a false watchdog failure. Issue #8586's acceptance criteria forbid
approval waits from causing watchdog failures, so exempt the approval
state from the model deadline just like external-input waits.

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>
Patrol-Run: qwen-pr-closeout/jmtwznj86xz
|
Qwen Code review timed out. Qwen review timed out after 21600 seconds (of the 360-minute budget). This run already used the maximum 360 minute timeout. See workflow logs. |
Only clear retireWhenSessionsDrain when this recycle itself set it; a
rollback must not erase a reap-after-drain condemnation a different
condemnor (timeout, MCP discovery/auth) had already flagged on the channel.

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>
Patrol-Run: qwen-pr-closeout/jmtxl34z1yy
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed.
22 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- recordOnly terminal notification dropped in the interactive TUI (packages/cli/src/ui/hooks/use-llm-stream.ts:6314) — already reported as R1-9 (comment 3950282815)
- isChannelLive() doc describes admission while the implementation reports liveness (packages/acp-bridge/src/bridgeTypes.ts:2532) — already reported (round-3 deferral record)
- the recycle's replacement generation is never handed to the channel idle-reap policy (packages/acp-bridge/src/bridge.ts:3816) — already reported as R3-10 (round-3 review 5142185428)
- the public AcpSessionBridge.requestRuntimeRecycle member has no caller and the shipped child-to-daemon route is untested (packages/acp-bridge/src/bridgeTypes.ts:2549) — already reported as R1-11 (comment 3950282825)
- the daemon's record-only path has no test (packages/cli/src/acp-integration/session/Session.ts:10298) — already reported in the missing-test aggregate (round-3 review 5142185428)
- neither new runtime_recycling 503 mapping is tested (packages/cli/src/serve/acp-http/dispatch.ts:918) — already reported in the missing-test aggregate (round-3 review 5142185428)
- BridgeRuntimeRecyclingError missing from the daemon metrics known-error allowlist (packages/cli/src/serve/server/error-response.ts:383) — already reported as R1-10 (comment 3950282821), author confirmed still standing at head
- the escalation callback onUnresponsive is asserted nowhere (packages/core/src/agents/runtime/agent-progress-watchdog.test.ts:65) — already reported in the missing-test aggregate (round-3 review 5142185428)
- the new settled flag is never emitted by any test (packages/core/src/agents/runtime/agent-progress-watchdog.test.ts:48) — already reported in the missing-test aggregate (round-3 review 5142185428)
- the agent-headless progress-timeout mapping has no test (packages/core/src/agents/runtime/agent-headless.ts:402) — already reported in the missing-test aggregate over the abort-reason TIMEOUT mappings (round-3 review 5142185428)
- agent-core's producer-side watchdog emissions are untested (packages/core/src/agents/runtime/agent-core.ts:1399) — already reported in the missing-test aggregate (round-3 review 5142185428)
- releaseRetainedPhysicalSlot and the retained-slot accounting have no test (packages/core/src/agents/background-tasks.ts:943) — already reported in the missing-test aggregate (round-3 review 5142185428)
- the headless recordOnly consumer is untested (packages/cli/src/nonInteractiveCli.ts:2800) — already reported in the missing-test aggregate over recordOnly routing (round-3 review 5142185428)
- the admissibleChannelInfo() swap and per-generation identity fixes are untested for two coexisting generations (packages/acp-bridge/src/bridge.ts:14673) — already reported in the missing-test aggregate over the two-generation admission cap …
- describeBlockingBackgroundWork's widened predicate and 'still stopping' label have no test (packages/cli/src/ui/utils/backgroundWorkUtils.ts:108) — already reported in the missing-test aggregate over retainsPhysicalSlot accounting (round-3 …
- no case runs an executing tool past MODEL_CONTROL_PROGRESS_TIMEOUT_MS (packages/core/src/agents/runtime/agent-progress-watchdog.test.ts:74) — already reported in the missing-test aggregate over the watchdog module (round-3 review 5142185428…
- the retainsPhysicalSlot early exits in agent.ts and background-agent-resume.ts have no test (packages/core/src/tools/agent/agent.ts:3725) — already reported in the missing-test aggregate (round-3 review 5142185428)
- the suite never emits START/STREAM_TEXT/USAGE_METADATA so onActivity is unexercised (packages/core/src/agents/runtime/agent-progress-watchdog.test.ts:30) — already reported in the missing-test aggregate over the watchdog module (round-3 rev…
- armTool's drift re-arm closure is unpinned (packages/core/src/agents/runtime/agent-progress-watchdog.ts:141) — already reported in the missing-test aggregate over the watchdog module (round-3 review 5142185428)
- the new retryable 503 carries no Retry-After / retryAfterSeconds backoff hint (packages/cli/src/serve/server/error-response.ts:354) — already reported (round-3 deferral record)
- …and 2 more (see the run report)
Not reviewed: reverse audit — reached the 5-round cap for a large diff without two consecutive dry rounds; round 5 still reported findings, so what it surfaced is verified but the loop never converged.
Not reviewed: build-and-test — Integration Tests (CLI, No Sandbox) was skipped in CI and its suite did not run locally; Test (macos-latest, Node 22.x) and Test (windows-latest, Node 22.x) were also skipped and the same unit suites ran on Linux, so only the Linux unit ground is covered.
Not explored to full depth (tool budget reached): "agent reverse-audit (round 2)": whether registerOwnedMonitorNotifications 's wake fires when a Monitor task reaches a terminal status without delivering a message — the orphaned-waiter prem…; "agent reverse-audit (round 3)": whether the modified fake's exited resolving with undefined (instead of a real {exitCode, signalCode} ) drives the channel.exited handler down a differen….
Deferred under the convergence posture (round 8, not a blocker) — recorded, not requested in this round; 2 Critical(s) among them are deferred by their axes — fails-closed on new surface, where no wrong result is certified and the merge base had neither the surface nor the defect — and remain follow-up work recorded in the findings artifact:
packages/core/src/agents/runtime/agent-progress-watchdog.ts:154 — [review] Critical [fails-closed] [new-surface] The external-input latch is cleared only by ROUND_START …packages/core/src/agents/runtime/agent-core.ts:2104 — [review] Critical [fails-closed] [new-surface] The new TOOL_PROGRESS emit is placed *above* the…packages/acp-bridge/src/bridge.ts:3805 — [review] A draining generation is an OS-live ACP child that still…packages/acp-bridge/src/bridge.ts:3805 — [review] A recycle that lands while a spawn is inside…packages/acp-bridge/src/bridge.ts:3827 — [review] The rollback's clearing of retireWhenSessionsDrain is…packages/acp-bridge/src/bridge.ts:1098 — [review] Inserting state between the load-bearing JSDoc block and…packages/core/src/agents/runtime/agent-progress-watchdog.ts:106 — [review] ToolDeadline.parkedOnInput is a dead switch — its only…docs/design/background-agent-runtime-generations.md:13 — [review] Both language versions state the only recovery from the…packages/acp-bridge/src/bridge.ts:14673 — [review] generateWorkspaceAgent now reports a *draining* runtime…packages/core/src/agents/runtime/agent-headless.ts:402 — [review] The new catch arm classifies *any* exception as a progress…packages/core/src/agents/runtime/agent-progress-watchdog.ts:112 — [review] The model deadline armModel actually enforces is…packages/acp-bridge/src/bridge.test.ts:32729 — [review] The new test pins the drain-race refusal to…packages/cli/src/ui/utils/backgroundWorkUtils.ts:108 — [review] The — still stopping qualifier is appended to the label…packages/core/src/agents/runtime/agent-progress-watchdog.test.ts:181 — [review] The clock-drift branch in agent-progress-watchdog.ts:86 …packages/acp-bridge/src/bridge.ts:4661 — [review] The two-generation cap counts the still-draining…packages/core/src/agents/background-tasks.ts:930 — [review] The watchdog-escalation terminal transition persists a…packages/core/src/agents/runtime/agent-core.ts:2188 — [review] The settled transition is emitted unconditionally for…packages/core/src/tools/agent/agent.ts:1589 — [review] waitingForApproval() is derived from currentToolCalls …packages/acp-bridge/src/bridge.test.ts:29181 — [review] This new comment states an admission invariant the code…packages/core/src/agents/background-tasks.ts:1497 — [review] The widened hasRunningTasks() predicate has a second…
Convergence: round 8 posted 6 inline comment(s), 2 of them reported for the first time; the previous round posted 6 (1 new). Findings keep coming back to the same files: packages/acp-bridge/src/bridge.ts (findings in rounds 1, 7; 1 more now). The rate of new findings is not falling. A cluster that keeps producing siblings usually means the fixes are treating instances of a shared root cause — triaging that cause before the next round, or splitting an independent cluster into its own pull request, tends to end the loop faster than fixing them one at a time. Batching the remaining fixes and verifying them before the next push keeps the loop from re-deriving the same set; this PR's reviews already resolve to a critical posting floor. (Observation only — nothing was withheld from this review because of this observation.)
Mechanism health: this round did not close cleanly, so it withholds the incremental anchor — and the round it recovered had no anchor this round could use either — none at all, one with no certifier, one certified by an identity other than the one this round runs under, or one this round's fetch refused or resolved to the head — so the next review re-reads the whole diff unless recovery grafts an earlier own anchor that the round running it can use onto the complete work list this round leaves behind, and keeps doing so until a round's marker carries an anchor again or a graft lands that the round running it can use. (Stated, not acted on — this changes nothing about what the round posts.)
Residual risk: this loop is persistently critical — Criticals stood in the previous round's work-list and stand again this round (6 Critical(s)), the rate of first-time findings is not falling (this round 2, previous 1), and the standing Critical backlog is not shrinking. The severity floor will not converge it. Recommendation: land-with-residual-risk — the exit is a maintainer risk-acceptance decision (merge, carrying the residual risk), not another review round. Residual-risk inventory for that decision (maintainer to complete):
| standing Critical | attack surface | attacker-dependency | blast radius |
|---|---|---|---|
| (each standing Critical) | … | … | … |
Advisory only — it does not block this review.
中文说明
仅完成部分审查,审查缺口已披露。
本轮确认的 22 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未审查(原文为英文):reverse audit — reached the 5-round cap for a large diff without two consecutive dry rounds; round 5 still reported findings, so what it surfaced is verified but the loop never converged.
未审查(原文为英文):build-and-test — Integration Tests (CLI, No Sandbox) was skipped in CI and its suite did not run locally; Test (macos-latest, Node 22.x) and Test (windows-latest, Node 22.x) were also skipped and the same unit suites ran on Linux, so only the Linux unit ground is covered.
未探索到全部深度(达到工具调用预算):"agent reverse-audit (round 2)":whether registerOwnedMonitorNotifications 's wake fires when a Monitor task reaches a terminal status without delivering a message — the orphaned-waiter prem…;"agent reverse-audit (round 3)":whether the modified fake's exited resolving with undefined (instead of a real {exitCode, signalCode} ) drives the channel.exited handler down a differen…。
收敛姿态下延后(第 8 轮,非阻断)——已记录,本轮不要求修改;其中 2 条 Critical 按其失败方向与对照基线延后——fails-closed 且 new-surface:未认证任何错误结果,且 merge base 既无该功能面也无该缺陷——作为后续工作记录在 findings 工件中:共 20 条(原文未翻译,列表见上方英文部分)。
收敛情况:第 8 轮发布了 6 条行内评论,其中 2 条是首次提出;上一轮发布了 6 条(其中 1 条首次提出)。发现反复回到同一批文件:packages/acp-bridge/src/bridge.ts(第 1、7 轮已出过发现,本轮又有 1 条)。新发现的产出速度没有下降。一个不断再生兄弟发现的簇,通常意味着逐条修复只在处理同一根因的实例——先定位并处理该根因,或把独立的簇拆成单独的 PR,通常比逐条修复更快结束循环。把剩余修复攒成一批、验证后再推送,可以避免循环反复推导同一组发现;本 PR 的评审已解析为 critical 发布下限。(仅为观察——本轮评审未因此扣留任何内容。)
机制健康:本轮未能干净收尾,因而扣留了增量锚点,而它恢复到的那一轮也没有留下本轮可用的锚点——要么完全没有、要么没有认证者、要么由本轮运行身份之外的身份认证、要么被本轮的获取拒绝或解析为头提交——因此下一次评审将重读整个 diff,除非恢复流程把本轮能使用的更早自有锚点嫁接到本轮留下的完整工作清单上;并会一直如此,直到某一轮的标记重新带上锚点,或落地的嫁接能被运行该轮的评审使用。(仅陈述,不据此行动——这不改变本轮发布的任何内容。)
残余风险:本循环处于 persistently-critical 形态——上一轮工作清单中的 Critical 本轮依然存在(本轮 6 条 Critical),首次发现的速率没有下降(本轮 2,上一轮 1),且未决 Critical 积压没有减少。severity floor 无法使其收敛。建议:land-with-residual-risk——出口是 maintainer 的风险接受决定(合入并承担残余风险),而非再开一轮评审。供该决定使用的残余风险清单(maintainer 填写):按每条未决 Critical 列出「攻击面 · 攻击者依赖性 · 影响范围」三栏。仅为建议——不阻断本次评审。
— qwen3.8-max via Qwen Code /review (v0.23.3)
…tores on drained generations

Two round-8 review findings:

- acp-bridge: `loadSession`/`unstable_resumeSession` only re-tested `ci.isDying`
  after the restore round-trip, so a runtime recycle landing mid-restore
  installed a brand-new session on the condemned generation. The recycle leaves
  the channel `draining` with `isDying === false`, because retirement is
  deferred while that very restore is in flight (`hasNoSessionWork` counts
  `pendingRestoreCount`), so the guard passed and `createSessionEntry` pinned
  the drained generation open until the new session closed. Mirror the
  post-`newSession` twin's three-state test: `ci.state !== 'active'`.

- core: `failUnresponsive` bailed out on `entry.notified`, so when the
  cancel-grace timer (`CANCEL_GRACE_MS`) finalized the cancellation — emitting
  the terminal notification and setting `notified` — before the drift-guarded
  watchdog escalation landed, the escalation was dropped entirely and
  `retainsPhysicalSlot` was never set, even though `onUnresponsive` can only
  fire while the execution is provably still alive. Reaching the escalation is
  itself proof that the execution still holds a physical slot, so settle the
  entry and retain the slot regardless of the already-delivered notification.
  `emitNotification` stays idempotent, so the terminal notification is not
  re-fired.

Regression tests sit beside the existing twins and both fail when their guard
is reverted: packages/core/src/agents/background-tasks.test.ts and
packages/acp-bridge/src/bridge.test.ts.

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>
Patrol-Run: qwen-pr-closeout/jmtyno0zh0n
Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>

Patrol-Run: qwen-pr-closeout/jmtypt6si0q
|
Integrity audit of the resolved Verified this round, highest-severity first — all four judge the cited hazard obsolete at this head, so all stay resolved:
Nothing was re-opened. Two notes for the reviewer: the per-call Remaining 32 silent-resolved Criticals: "resolve justified, not audited this round". No code was changed. |
|
Qwen Code review did not complete successfully. The review pipeline failed before a review could be posted. A transient error is retried automatically; if you are seeing this, retry with |
Closeout round
|
| Finding | Anchor verified at 93eef769a7 |
Gate hit |
|---|---|---|
| R6-2 escalation grace vs. cooperative unwind | agent-progress-watchdog.ts:19, abort() :67-78, only clear at :239 inside the detach closure that runs at agent.ts:3915 — same .finally as both releaseRetainedPhysicalSlot call sites (agent.ts:3916, background-agent-resume.ts:1437) |
concurrency / settle semantics |
| R6-3 retry extension cannot cross nesting | agent.ts:1477-1485 (forwardProgress is zero-arity, so the delay is dropped by signature before the 1/s throttle), agent-events.ts:181-194, agent-progress-watchdog.ts:128 + drift re-arm :142 |
new cross-layer event field |
| R6-6a compression retry invisible | llm-chat.ts:564 vs TryCompressOptions :588; call sites :3102/:3965; chatCompressionService.ts:844/:884; baseLlmClient.ts:78/:307/:462 |
new callback on exported GenerateTextOptions |
R6-6b retainsPhysicalSlot unbounded |
background-tasks.ts:943, :1512, :1890, cancel() bail :984; PR's own invariant at :920-934 |
semantics + data-loss edge |
| R1-36 workspace MCP routes during drain | bridge.ts:6318-6322, :14699/:14821/:14877 vs session twins :14927/:14936 |
routing contract + public API |
Two of these produced new evidence this round that changes the shape of the decision:
- R6-6b: the suggested remediation (an unref'd fallback timer in
failUnresponsivecallingreleaseRetainedPhysicalSlot) contradicts this PR's own documented invariant atbackground-tasks.ts:920-934— "the physical slot must still be retained … otherwisegetRunningBackgroundCountandhasRunningTasks()free a concurrency slot that is still occupied, and/clear,/resume,/branchand session switches all proceed over live work." A delayed auto-release does exactly that once it fires, andreset()clears the map without abortingentry.abortController, so a still-running orphan loses its only owner. The stuck gate is real (cancel()bails at:984on thefailedstatusfailUnresponsiveset at:940;pruneTerminalEntries()exempts retained entries at:1890) — but both exits cost something, so the choice is not mechanical. - R1-36: the cheaper "refuse when
liveChannelInfo() !== admissibleChannelInfo()" remediation is provably unreachable in the reported scenario, not merely ineffective. Both predicates read the same singlechannelInfobinding (:6318-6319and:6321-6322), so they can only disagree whenchannelInfois non-dying and notactive— draining with no replacement spawned. After a recycle repointschannelInfoat the replacement both return the reference-identical object. A fan-out is feasible (aliveChannelsis iterated at:2821, membership-tested at:4035); what blocks it is the partial-success contract on the workspace HTTP result and the conditionalmcp_server_addedbroadcast.
Decisions requested
- R6-2 — bounded total grace covering the cooperative unwind (keeping the hard force-fail), or let a late cooperative settle re-publish its real payload (incl. the worktree suffix) and skip the recycle? The second crosses
agent.ts+background-tasks.ts+Session.tsand inverts terminal-outcome precedence. - R6-3 — should a nested run's provider-directed backoff extend the parent's tool deadline at all? If yes,
retryDelayMsgoes onAgentToolProgressEventwith a latch/clear rule and theMAX_RETRY_DEADLINE_EXTENSION_MSclamp re-passed through the drift re-arm closure. - R6-6a — may a compression side query's backoff extend a background agent's model deadline, or must compression stay
maxAttempts: 1and fail to NOOP fast?chatCompressionService.ts:749-751argues the latter; this PR's design doc argues the former. - R6-6b — bounded automatic release (contradicts
:920-934, can free a slot a live orphan still occupies), or user-initiated force-release incancel()plus dropping the matching refusal intask-stop.ts? - R1-36 — fan out to every non-dying generation and define partial success, or reject workspace-scoped runtime-MCP mutations whenever a work-owning generation is not the active one?
Resolution-integrity audit — 32 flagged, 0 re-opened
32 resolved threads whose first comment is [Critical] end with the bot's own finding and carry no author reply. Grouped by finding id that is 20 ids, and every one of them was minted on or before 2026-09-09T11:37:45Z. The bot's two later full-diff scans (2026-09-11T09:32, 2026-09-12T04:52) re-minted only R1-36, R6-2, R6-3 and R6-6, each with explicit "Still stands at <sha>" wording — i.e. the reviewer demonstrably re-mints anything that survives a scan. Non-re-mint across two later scans is therefore the retirement evidence, and none of the 20 is a silent resolve of a still-live Critical. The resolved threads that do come from those two later rounds all carry author replies with fix SHAs (1487c0d5b6 on background-tasks.ts and bridge.ts:3808; 90e2d6f7ae on retireWhenSessionsDrain).
CI — clean, nothing PR-caused to fix
gh pr checks 11270 at this head: 22 pass / 26 skipping / 1 pending. All required suites pass — Test (ubuntu-latest, Node 22.x) 22m23s, Lint & Static 12m38s, Integration Tests (no-AK, No Sandbox) 8m49s, Serve A/B 21m30s, web-shell E2E Smoke 10m13s, Real daemon E2E, TUI parity snapshots, OpenTUI no-flicker gate, Desktop Shell (ubuntu + windows). The single pending job is review-pr, an informational review bot that does not gate. No DFSAMPLE load failures and no checkout-verification race in any log, so no infra-vs-PR attribution was needed. The skipping rows are conditional jobs (fork-PR signalling, windows/macos test shards, takeover/retry command handlers) that this run did not select.
Why /triage was not re-triggered
The standing CHANGES_REQUESTED is qwen-code-ci-bot's (2026-09-12T04:52:05Z), which is normally the cue for a standalone @qwen-code /triage. It was deliberately skipped: the head is unchanged since that scan, so a re-run would re-mint the same four findings rather than re-judge anything, and the CR is not stale — the four Criticals are live and unresolved. It clears on a code change answering one of the five decisions above, or on a maintainer override.
No push this round; head remains 93eef769a7.
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed.
22 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- isChannelLive() doc describes admission while the implementation reports liveness (packages/acp-bridge/src/bridgeTypes.ts:2531) — already reported (round-3 deferral record)
- recordOnly terminal notification dropped in the interactive TUI (packages/cli/src/ui/hooks/use-llm-stream.ts:6314) — already reported as R1-9 (comment 3950282815)
- BridgeRuntimeRecyclingError missing from the daemon metrics known-error allowlist (packages/acp-bridge/src/bridgeErrors.ts:676) — already reported as R1-10 (comment 3950282821)
- the public AcpSessionBridge.requestRuntimeRecycle member has no production caller (packages/acp-bridge/src/bridge.ts:9783) — already reported as R1-11 (comment 3950282825)
- the shipped child-to-daemon sessionRuntimeRecycle ext-method validation is untested (packages/acp-bridge/src/bridgeClient.ts:1340) — already reported as R1-11 (comment 3950282825)
- wasReapPending is captured before two awaits so the rollback can erase an independent condemnation (packages/acp-bridge/src/bridge.ts:3813) — already reported (round-8 deferral, bridge.ts:3827)
- isDying is declared a plain boolean but implemented as a write-only-true alias over state (packages/acp-bridge/src/bridge.ts:1098) — already reported (round-8 deferral, bridge.ts:1098)
- the recycle's replacement generation is never handed to the channel idle-reap policy (packages/acp-bridge/src/bridge.ts:3816) — already reported as R3-10 (round-3 review 5142185428)
- settled:true TOOL_PROGRESS is re-emitted for every terminal call on every scheduler notify (packages/core/src/agents/runtime/agent-core.ts:2188) — already reported (round-8 deferral, agent-core.ts:2188)
- ToolDeadline.parkedOnInput is a dead switch (packages/core/src/agents/runtime/agent-progress-watchdog.ts:106) — already reported (round-8 deferral)
- the escalation callback onUnresponsive is asserted nowhere (packages/core/src/agents/runtime/agent-progress-watchdog.test.ts:66) — already reported in the missing-test aggregate (round-3 review 5142185428)
- the suite never emits START/STREAM_TEXT/USAGE_METADATA so onActivity is unexercised (packages/core/src/agents/runtime/agent-progress-watchdog.test.ts:25) — already reported in the missing-test aggregate (round-3 review 5142185428)
- agent-core's producer-side watchdog emissions are untested (packages/core/src/agents/runtime/agent-core.ts:2104) — already reported in the missing-test aggregate (round-3 review 5142185428)
- the daemon's record-only drain branch has no test (packages/cli/src/acp-integration/session/Session.ts:10337) — already reported in the missing-test aggregate (round-3 review 5142185428)
- releaseRetainedPhysicalSlot and the retained-slot accounting have no test (packages/core/src/agents/background-tasks.ts:1348) — already reported in the missing-test aggregate (round-3 review 5142185428)
- the resume-path retainsPhysicalSlot early exits have no test (packages/core/src/agents/background-agent-resume.ts:1300) — already reported in the missing-test aggregate (round-3 review 5142185428)
- neither new runtime_recycling 503 mapping is tested (packages/cli/src/serve/acp-http/dispatch.ts:918) — already reported in the missing-test aggregate (round-3 review 5142185428)
- describeBlockingBackgroundWork's widened predicate and 'still stopping' label have no test (packages/cli/src/ui/utils/backgroundWorkUtils.ts:101) — already reported in the missing-test aggregate (round-3 review 5142185428)
- all agent.ts watchdog wiring is untested (packages/core/src/tools/agent/agent.ts:3881) — already reported in the missing-test aggregate (round-3 review 5142185428)
- the new retryable 503 carries no Retry-After backoff hint and is absent from the error-taxonomy docs (packages/cli/src/serve/server/error-response.ts:383) — already reported (round-3 deferral record)
- …and 2 more (see the run report)
Unresolved, please confirm:
- [Critical] R6-1 (agent-progress-watchdog approval timeout) — @doudouOUC's review 5177234081 records it as still implemented and not fixed, while round 8's machine ledger does not carry it; this round did not re-read that mechanism, so it cannot be rul…
- [Critical] R1-29 (cancel-versus-watchdog terminal semantics) — @doudouOUC's review 5177234081 states it must not be called resolved merely because a later test chooses the opposite policy, and round 8's ledger does not carry it; not re-read this round…
Not reviewed: build-and-test — Integration Tests (CLI, No Sandbox) was skipped in CI and its suite did not run locally; Test (macos-latest, Node 22.x) and Test (windows-latest, Node 22.x) were also skipped and the same unit suites ran on Linux, so only the Linux unit ground is covered.
Not reviewed: reverse audit — stopped after round 4 of the plan's 5-round cap; rounds 3 and 4 both reported findings, so two consecutive dry rounds were unreachable and the final round was not run.
Not reviewed: test-efficacy probe — Agent 7's mutation probe came back inconclusive because its scratch tree could not resolve the workspace packages' dist/, so no coverage gap was measured in either direction.
Not reviewed: reverse-audit rounds 3 and 4 Suggestion-level candidates — the loop was stopped before they could be put through a verifier, so they are disclosed as unverified rather than confirmed.
Not reviewed: reverse-audit round 4 Critical at packages/acp-bridge/src/bridge.ts:8836 — reported but never put through a verifier; carried in the findings artifact at low confidence.
Not explored to full depth (tool budget reached): chunk 1: did not verify whether any SDK/client-side layer retries an errorKind: 'internal' frame (finding 1's impact hinges on it), and did not read the restore re-che…; "agent reverse-audit (round 3)": the filed finding was traced by reading only — I did not execute a probe of the two-generation recycle sequence, which is why it carries Confidence: low .; "agent reverse-audit (round 1)": did not verify the child-side cost of the orphaned restored session in finding 1 — whether the agent-owned writer lease it holds ( packages/cli/src/acp-integrat….
Deferred under the convergence posture (round 9, not a blocker) — recorded, not requested in this round; 3 Critical(s) among them are deferred by their axes — fails-closed on new surface, where no wrong result is certified and the merge base had neither the surface nor the defect — and remain follow-up work recorded in the findings artifact:
packages/core/src/tools/agent/agent.ts:3915 — [probe] Critical [fails-closed] [new-surface] R6-6: a retained physical slot has no terminal remedy once the watchdog has failed the entrypackages/acp-bridge/src/bridge.ts:5711 — [probe] Critical [fails-closed] [new-surface] a recycle-condemned spawn rejection is classified as a non-retryable internal error while this PR adds a retryable 503 siblingpackages/acp-bridge/src/bridge.ts:4648 — [probe] Critical [fails-closed] [new-surface] the recycle cancels the current primary's idle reaper and never re-arms itpackages/acp-bridge/src/bridge.ts:5711 — [probe] a spawn rejected by the draining re-check leaves the child-side session unsettledpackages/core/src/agents/runtime/agent-progress-watchdog.ts:114 — [probe] the six-hour retry-extension cap is untested and an above-cap delay is reachable by defaultpackages/core/src/agents/runtime/agent-progress-watchdog.ts:204 — [probe] nothing pins that a heartbeating executing tool is exempt from the model deadline
Convergence: round 9 posted 4 inline comment(s), 1 of them reported for the first time; the previous round posted 6 (2 new). Findings keep coming back to the same files: packages/core/src/agents/background-tasks.ts (findings in round 8; 1 more now). A cluster that keeps producing siblings usually means the fixes are treating instances of a shared root cause — triaging that cause before the next round, or splitting an independent cluster into its own pull request, tends to end the loop faster than fixing them one at a time. (Observation only — nothing was withheld from this review because of this observation.)
Mechanism health: this round did not close cleanly, so it withholds the incremental anchor — and the round it recovered had no anchor this round could use either — none at all, one with no certifier, one certified by an identity other than the one this round runs under, or one this round's fetch refused or resolved to the head — so the next review re-reads the whole diff unless recovery grafts an earlier own anchor that the round running it can use onto the complete work list this round leaves behind, and keeps doing so until a round's marker carries an anchor again or a graft lands that the round running it can use. (Stated, not acted on — this changes nothing about what the round posts.)
中文说明
仅完成部分审查,审查缺口已披露。
本轮确认的 22 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未决,请确认:共 2 条(原文未翻译,列表见上方英文部分)。
未审查(原文为英文):build-and-test — Integration Tests (CLI, No Sandbox) was skipped in CI and its suite did not run locally; Test (macos-latest, Node 22.x) and Test (windows-latest, Node 22.x) were also skipped and the same unit suites ran on Linux, so only the Linux unit ground is covered.
未审查(原文为英文):reverse audit — stopped after round 4 of the plan's 5-round cap; rounds 3 and 4 both reported findings, so two consecutive dry rounds were unreachable and the final round was not run.
未审查(原文为英文):test-efficacy probe — Agent 7's mutation probe came back inconclusive because its scratch tree could not resolve the workspace packages' dist/, so no coverage gap was measured in either direction.
未审查(原文为英文):reverse-audit rounds 3 and 4 Suggestion-level candidates — the loop was stopped before they could be put through a verifier, so they are disclosed as unverified rather than confirmed.
未审查(原文为英文):reverse-audit round 4 Critical at packages/acp-bridge/src/bridge.ts:8836 — reported but never put through a verifier; carried in the findings artifact at low confidence.
未探索到全部深度(达到工具调用预算):chunk 1:did not verify whether any SDK/client-side layer retries an errorKind: 'internal' frame (finding 1's impact hinges on it), and did not read the restore re-che…;"agent reverse-audit (round 3)":the filed finding was traced by reading only — I did not execute a probe of the two-generation recycle sequence, which is why it carries Confidence: low .;"agent reverse-audit (round 1)":did not verify the child-side cost of the orphaned restored session in finding 1 — whether the agent-owned writer lease it holds ( packages/cli/src/acp-integrat…。
收敛姿态下延后(第 9 轮,非阻断)——已记录,本轮不要求修改;其中 3 条 Critical 按其失败方向与对照基线延后——fails-closed 且 new-surface:未认证任何错误结果,且 merge base 既无该功能面也无该缺陷——作为后续工作记录在 findings 工件中:共 6 条(原文未翻译,列表见上方英文部分)。
收敛情况:第 9 轮发布了 4 条行内评论,其中 1 条是首次提出;上一轮发布了 6 条(其中 2 条首次提出)。发现反复回到同一批文件:packages/core/src/agents/background-tasks.ts(第 8 轮已出过发现,本轮又有 1 条)。一个不断再生兄弟发现的簇,通常意味着逐条修复只在处理同一根因的实例——先定位并处理该根因,或把独立的簇拆成单独的 PR,通常比逐条修复更快结束循环。(仅为观察——本轮评审未因此扣留任何内容。)
机制健康:本轮未能干净收尾,因而扣留了增量锚点,而它恢复到的那一轮也没有留下本轮可用的锚点——要么完全没有、要么没有认证者、要么由本轮运行身份之外的身份认证、要么被本轮的获取拒绝或解析为头提交——因此下一次评审将重读整个 diff,除非恢复流程把本轮能使用的更早自有锚点嫁接到本轮留下的完整工作清单上;并会一直如此,直到某一轮的标记重新带上锚点,或落地的嫁接能被运行该轮的评审使用。(仅陈述,不据此行动——这不改变本轮发布的任何内容。)
— qwen3.8-max via Qwen Code /review (v0.23.3)
| } | ||
| this.releaseFinishingWaiters(agentId, true); | ||
| this.rejectPendingApprovals(entry); | ||
| this.emitNotification(entry, true); |
There was a problem hiding this comment.
[Critical] R9-1: [certifies-falsely] [new-surface] The runtime recycle is hung off the record-only notification, so whenever the cancel-grace timer wins the race the owner generation is never condemned — while the cost half of the escalation still lands.
failUnresponsive is deliberately not gated on entry.notified, and it latches retainsPhysicalSlot = true before calling emitNotification(entry, true). But emitNotification still returns at if (entry.notified) return;, and the recycle has exactly one trigger in the whole repository: Session.ts's if (meta.recordOnly) branch calling #recordUnresponsiveAgentNotification, whose finally sends qwen/control/session/runtime/recycle. Suppress the notification and the recycle goes with it.
Both timers are 5 s, and the escalation is drift-guarded and re-arms while the cancel grace is a bare setTimeout, so one event-loop stall is enough for the cancel side to win — the comment above this method says exactly that. Any cancel({ notify: false }) inside the window does the same (/clear, a session switch, ACP session teardown). When it happens the owner generation stays state: 'active', so admissibleChannelInfo() keeps handing fresh sessions to the child the design doc calls unsafe for fresh work, and no replacement spawns; meanwhile retainsPhysicalSlot keeps hasRunningTasks() true, so /clear, /resume, /branch and session switches refuse permanently — the only release is the run body's .finally, which by hypothesis never runs. The design doc promises the opposite order ("recorded and displayed … then the trusted child-to-daemon route requests recycle"), and issue #8586's Layer 5 requires both halves.
The in-diff rationale argues "Only the notification is suppressed". That is true of the user-visible line and does not account for the recycle bolted to the same call.
Witness:
probe against the real registry at HEAD:
ARM B (cancel grace finalized first)  {"newCallsFromEscalation":0,"recordOnlyCalls":0,"status":"failed","retainsPhysicalSlot":true,"hasRunningTasks":true}
ARM C (notified cleared, re-entered)  the recordOnly call appears — so `if (entry.notified) return;` is the sole suppressor
grep sessionRuntimeRecycle packages/: 3 hits — the constant, the child-side handler, and the single call site in #recordUnresponsiveAgentNotification's finally
Do not hang the recycle off the notification: request it from failUnresponsive directly, or from a path that does not consult entry.notified, so the generation is condemned whenever the escalation lands. If it must stay behind the notification, let the record-only path still invoke the recycle callback when entry.notified is already set.
Any fix must keep the user-visible notification idempotent — the comment at background-tasks.ts:921-935 states that emitNotification is itself idempotent (if (entry.notified) return), "so the already-delivered terminal notification is never re-fired", and a fix must not re-deliver a duplicate terminal line while adding the recycle.
Please extend background-tasks.test.ts's "retains the physical slot when the cancel grace timer finalizes before the escalation" case to assert the recycle is still requested in that ordering; it must go red while emitNotification short-circuits on entry.notified.
中文说明
[Critical] R9-1:运行时回收(recycle)挂在 record-only 通知上,因此只要 cancel-grace 定时器赢得竞争,owner generation 就永远不会被判定回收——而升级处理的代价那一半却照常发生。
failUnresponsive 有意不以 entry.notified 为门槛,并在调用 emitNotification(entry, true) 之前置上 retainsPhysicalSlot = true。但 emitNotification 仍然会在 if (entry.notified) return; 处返回,而整个仓库中回收只有一个触发点:Session.ts 的 if (meta.recordOnly) 分支调用 #recordUnresponsiveAgentNotification,由其 finally 发出 qwen/control/session/runtime/recycle。通知被抑制,回收就一并被抑制。
两个定时器都是 5 秒,而升级定时器带漂移保护、会重新计时,cancel grace 却是裸 setTimeout,因此一次事件循环阻塞就足以让 cancel 一侧获胜——本方法上方的注释正是这么写的。窗口内任何 cancel({ notify: false }) 效果相同(/clear、切换会话、ACP 会话销毁)。一旦发生,owner generation 仍保持 state: 'active',于是 admissibleChannelInfo() 会继续把新会话交给设计文档称为"不适合承接新工作"的那个子进程,且不会派生替代 generation;同时 retainsPhysicalSlot 让 hasRunningTasks() 恒为真,/clear、/resume、/branch 与会话切换将被永久拒绝——唯一的释放点是 run body 的 .finally,而按前提它永远不会执行。设计文档承诺的是相反的顺序("先记录并展示……然后由可信的 child-to-daemon 路由请求回收"),issue #8586 的 Layer 5 也要求两半都成立。
diff 内的理由写的是"只有通知被抑制"。这对用户可见的那一行成立,但没有考虑到挂在同一次调用上的回收。
修复方向:不要把回收挂在通知上——直接从 failUnresponsive 请求回收,或从一个不读取 entry.notified 的路径请求,使升级一旦落地 generation 就被判定回收。若必须留在通知之后,则让 record-only 路径在 entry.notified 已置位时仍然调用回收回调。
修复约束:必须保持用户可见通知的幂等性——background-tasks.ts:921-935 的注释写明 emitNotification 自身是幂等的(if (entry.notified) return),"因此已送达的终态通知不会被再次触发";补上回收的同时不得重复投递终态通知。
请补充测试:扩展 background-tasks.test.ts 中 "retains the physical slot when the cancel grace timer finalizes before the escalation" 用例,断言在该顺序下回收请求仍然发出;当 emitNotification 仍在 entry.notified 处短路时,该断言必须为红。
(证据见上方 Witness 代码块;witness 为程序输出,未翻译。)
— qwen3.8-max via Qwen Code /review (v0.23.3)
There was a problem hiding this comment.
Round jmtzb8sj51m — independent verification at head 93eef769a7. REAL. No fix exists inside this round's ceiling (≤3 files, no new cross-layer field/transport, no concurrency-semantics or product-behavior change); escalating.
Chain, every link read at this head:
agent-progress-watchdog.ts:66-76—abort()callscontroller.abort(error)then arms the escalation;schedule()at:77-90is drift-guarded (if (performance.now() - expectedAt > 1_000) { rearm(); return; }) andarmEscalationre-arms itself after every fire. Its only clear is:239, inside the detach closure, which runs atagent.ts:3915in the turn promise's.finally.background-tasks.ts:157—CANCEL_GRACE_MS = 5000, armed at:1025-1027as a baresetTimeout. Same 5 s budget, no drift guard, so any stall hands it the win.- It is the same controller:
agent.ts:3212createsbgAbortController, registers it as the entry'sabortControllerat:3273, and passes it asturnAbortControllerat:4004→ watchdog at:3883. Socancel()'s abort (background-tasks.ts:991) cannot disarm an already-armed escalation, and the watchdog's ownabort()bails on an already-aborted signal — the escalation survives a user cancel. finalizeCancellationIfPending(:1083-1094) →emitNotificationsetsentry.notified = true(:1754).failUnresponsive(:935-956) guards only onstatus ∈ {running, cancelled}(:937-938), not onnotified. It latchesretainsPhysicalSlot = true(:943), then callsemitNotification(entry, true)(:953), which returns atif (entry.notified) return;(:1753). The callback never runs.meta.recordOnlytherefore never reachesSession.ts:9932, so#recordUnresponsiveAgentNotification(Session.ts:10142) never runs — and itsfinally(:10164-10176) is the only sender ofsessionRuntimeRecycle. Repo-wide non-dist grep gives exactly 3 src hits: the constant (acp-bridge/src/status.ts:195), the child-side handler (bridgeClient.ts:1340-1355), and that call site. No recycle.- Without it,
requestRuntimeRecycleForSession(bridge.ts:3798-3834) never runs, soowner.statestays'active'andadmissibleChannelInfo()(bridge.ts:6321-6322) keeps routing fresh sessions to the unresponsive generation. - The cost half is permanent, not transient.
hasRunningTasks()counts the retained slot (background-tasks.ts:1509-1513) →hasBlockingBackgroundWork()(cli/src/ui/utils/backgroundWorkUtils.ts:16-33) →/clear(clearCommand.ts:47),/resume(useResumeCommand.ts:107),/branch(useBranchCommand.ts:112) and session switch (session-switch.ts:101,:267) all refuse, soreset()is never reached.releaseRetainedPhysicalSlot(:958-964) has exactly two call sites, both inside the run body's.finally(agent.ts:3916,background-agent-resume.ts:1437), which by premise never runs.pruneTerminalEntriesexempts retained-slot entries (:1889-1890), andcancel()re-entry bails onstatus !== 'running'(:988). There is no user-reachable escape. - This ordering is not hypothetical — the PR's own test drives it.
background-tasks.test.ts:335("retains the physical slot when the cancel grace timer finalizes before the escalation") runscancel→finalizeCancellationIfPending(assertingnotified === true) →failUnresponsive, and assertsretainsPhysicalSlot === true,hasRunningTasks() === true,callbackcalled once. It asserts nothing about the recycle, which is the gap this finding names. Second route:abortAll({ notify: false })(:1722-1734) setsnotified = trueand keeps the entry in the map (continue); it is used bySession.ts:4340(ACP teardown) andclearCommand.ts:74.
Why no ≤3-file mechanical fix exists — I worked both suggested directions:
- "Request it from
failUnresponsivedirectly." Core has no transport to the daemon; the registry's only channel out isnotificationCallback(displayText, modelText, meta). A dedicated recycle signal means a new callback field + setter onAgentTaskRegistryand a new installer inSession.ts— a new cross-layer contract plus a public API change. Excluded class. - "Let the record-only path still invoke the recycle callback when
entry.notifiedis already set." That means bypassing thenotifiedlatch inemitNotification, and the record-only carrier is not display-free:#recordUnresponsiveAgentNotificationcalls#persistDaemonBackgroundNotification(item, false)(Session.ts:10148), which does not consultpersistedBackgroundNotificationTaskIds— that dedup lives inenqueueBackgroundNotificationat:10187— then enqueues withrecordOnly: true(:10152-10159), and the drain at:10337-10350runs#emitBackgroundNotificationDisplay(item)+#emitBackgroundNotificationEndTurn. So the re-fire writes a second chat-recording notification and emits a second ACP display line for the same task: exactly the duplicate terminal line thatbackground-tasks.ts:920-934and this finding both forbid. - Making that re-fire display-free needs either a new
metaflag (new cross-package field) or taskId dedup inside#recordUnresponsiveAgentNotification(second package, and it redefines whatrecordOnlymeans). It also breaks the registry's documented one-notification-per-agent contract (:1078-1082,:1861-1885), whose other two consumers —nonInteractiveCli.ts:1535anduse-llm-stream.ts:6314— would each need their own duplicate audit. ≥4 files across 2 packages. - The mirror-image fix (don't latch
retainsPhysicalSlotwhen the notification was suppressed) contradicts the invariant at:920-934that the previous round already ruled on, and contradicts the existing test at:335, which asserts the latch in precisely this ordering. The physical process really is still alive, so freeing the slot lets/clearand session switches proceed over live work. - Fix-introduced-regression guard, for the record: the
notify: falseroutes setnotified = truespecifically so a torn-down session's terminal line cannot leak into the next conversation (:1017-1019,:1731-1733). Any variant that re-fires past the latch resurrects that leak on the non-ACP surfaces, and in ACP it would newly couple/clear-during-a-stuck-agent to a full runtime recycle (drain + replacement spawn). That is a product-behavior change, not a guard — and it is the resource-ownership trap on this path: the actor that would own the teardown is the session being cleared, not the escalation.
Decision for the maintainer: where should the recycle trigger live? Either (a) a dedicated registry→session recycle channel that does not consult entry.notified, or (b) a daemon-side condemnor keyed on the retained-slot state itself — emitStatusChange at :954 already fires unconditionally, so the signal reaches Session.ts; what is missing is a contract for acting on it, plus dedup. Both are cross-layer design decisions on the mechanism this PR introduces, and (b) additionally has to decide whether a /clear-suppressed escalation may condemn a generation.
No code change this round. Leaving unresolved rather than silently resolving a Critical I declined to fix.
There was a problem hiding this comment.
Round jmu07e78o2w. Re-verified REAL at head 93eef769a798 (this is the round-9 fresh finding R9-1); still unresolved — no fix exists inside the ceiling.
New fact this round: @wenshao APPROVED at this head with an empty review body (5190785254), and this finding post-dates his runtime validation (bot review 5189445584, 2026-09-13T03:46:16Z), so it was never measured on the live daemon.
The load-bearing links, re-checked by grep at head rather than inherited:
emitNotificationshort-circuits onif (entry.notified) return;(background-tasks.ts:1753) — re-read verbatim this round, with the comment "Mark notified before invoking the callback so that a re-entrant terminal call inside the callback chain (cancel → complete race) sees the flag and short-circuits".failUnresponsiveguards only onstatus ∈ {running, cancelled}(:937-938), not onnotified, then latchesretainsPhysicalSlot = true(:943) and callsemitNotification(entry, true)(:953). The invariant comment at:920-934states this suppression is intentional: "Only the notification is suppressed, andemitNotificationis itself idempotent".- So when a cancel won the race and already set
notified, therecordOnlypayload never reachesSession.ts:9932,#recordUnresponsiveAgentNotification(Session.ts:10142) never runs, and itsfinally(:10164-10176) is the only sender of the recycle. Repo-wide non-dist grep forsessionRuntimeRecyclegives exactly 3 src hits, re-run this round: the constant (acp-bridge/src/status.ts:195), the child-side handler (acp-bridge/src/bridgeClient.ts:1340), and that one call site (packages/cli/src/acp-integration/session/Session.ts:10168). No recycle. - Without it,
requestRuntimeRecycleForSession(bridge.ts:3798-3834) never runs,owner.statestays'active', andadmissibleChannelInfo()(bridge.ts:6321-6322) keeps routing fresh sessions to the unresponsive generation. - The cost half is permanent, not transient, and I re-verified each line at head:
hasRunningTasks()counts the retained slot (:1512) →hasBlockingBackgroundWork()→/clear,/resume,/branchand session switch all refuse, soreset()is never reached;releaseRetainedPhysicalSlothas exactly two call sites, both in the run body's.finally(agent.ts:3916,background-agent-resume.ts:1437), which by premise never runs;pruneTerminalEntriesexempts retained-slot entries (:1890); andcancel()re-entry bails onstatus !== 'running'(:984) afterfailUnresponsiveflipped it to'failed'.
Both available remedies hit a gate:
- A separate recycle request path that does not ride the notification callback = a new cross-layer transport core → cli
Session.ts, excluded by this round's ceiling and an architecture-responsibility change. - Un-suppressing the notification when the prior one was a cancel = re-firing a terminal notification over an already-delivered one, i.e. the parent model is told "failed (watchdog)" after being told "cancelled". That is the same terminal-outcome-precedence inversion escalated on the R6-2 thread, and it is the exact question @wenshao's §6 asks a ruling to cover ("whether the parent model is told").
Leaving unresolved rather than resolving a disputed Critical with no fix behind it.
There was a problem hiding this comment.
[Critical] R9-1: [certifies-falsely] [new-surface] The runtime recycle is hung off the record-only notification, so whenever the cancel-grace timer wins the race the owner generation is never condemned.
failUnresponsive latches retainsPhysicalSlot, patches the sidecar to failed, and then reaches the daemon's only recycle route through emitNotification(entry, true). But emitNotification opens with if (entry.notified) return; (line 1763), under a comment saying the flag is set before the callback precisely so a re-entrant terminal call short-circuits. So when the user's task_stop armed the bare CANCEL_GRACE_MS timer and that timer finalized first, notified is already true, the record-only meta never reaches the callback, Session.ts:10279's if (meta.recordOnly) never fires, and #recordUnresponsiveAgentNotification's finally — the only sender of sessionRuntimeRecycle (Session.ts:10536) — is never reached. A repo-wide grep finds exactly three hits for that key, and owner.state = 'draining' is written at exactly one place in the whole bridge (bridge.ts:3853), inside the function that sender calls.
The consequence is the containment this PR exists to provide, silently skipped: the abort-ignoring run keeps executing inside a generation the daemon judged unsafe, that generation stays active and keeps admitting fresh sessions through admissibleChannelInfo(), and hasRunningTasks() stays true — so /clear, /resume, /branch and session switches are refused indefinitely while the tasks dialog lists the row as — still stopping, whose stop action is itself a no-op because cancel() returns early once the status is no longer running.
The fix is to decouple the recycle from the visible notification: give the registry a dedicated one-shot unresponsive-settlement hook, invoked unconditionally from failUnresponsive, and wire the sessionRuntimeRecycle ext-method to that hook instead of to #recordUnresponsiveAgentNotification. The record-only notification then stays idempotent while the recycle always follows an escalation.
Witness:
ARM1 escalation-wins: callbacks=1 recordOnly=[true] retainsPhysicalSlot=true hasRunningTasks=true
ARM2 pre-escalation:  notified=true callbacks=1
ARM2 grace-wins:      callbacks=1 recordOnly=[null] status=failed retainsPhysicalSlot=true hasRunningTasks=true
ARM2 => runtime-recycle trigger delivered? false
Two arms of the unmodified registry with one input varied (whether the cancel-grace timer finalized first): the recycle trigger is delivered in one and absent in the other. Your own test corroborates the suppression half and passes — background-tasks.test.ts -t 'cancel grace timer finalizes before the escalation' asserts expect(callback).toHaveBeenCalledOnce(), i.e. only the cancellation notification.
Constraint the fix must not violate: background-tasks.ts:1760-1763 marks notified before invoking the callback so a re-entrant terminal call inside the callback chain short-circuits rather than firing twice — the recycle must not be obtained by re-firing an already-delivered terminal notification.
Acceptance criterion: extend background-tasks.test.ts's 'retains the physical slot when the cancel grace timer finalizes before the escalation' to assert the new unresponsive/recycle hook fired once even though the notification callback fired only for the cancellation, and prove it by removing the hook and watching that test go red.
中文说明
failUnresponsive 会锁存 retainsPhysicalSlot、把 sidecar 改写为 failed,然后经由 emitNotification(entry, true) 去触发守护进程唯一的 recycle 路径。但 emitNotification 开头就是 if (entry.notified) return;(第 1763 行),注释明确说明之所以在回调前置位,是为了让重入的终态调用短路。因此当用户的 task_stop 先启动了裸的 CANCEL_GRACE_MS 定时器并且该定时器先完成时,notified 已为 true,record-only 元信息永远到不了回调,Session.ts:10279 的 if (meta.recordOnly) 不会触发,#recordUnresponsiveAgentNotification 的 finally(sessionRuntimeRecycle 的唯一发送方,Session.ts:10536)也就永远不会执行。全仓搜索该 key 只有三处命中,而 owner.state = 'draining' 在整个 bridge 中只有一处写入(bridge.ts:3853),就在该发送方调用的函数内部。
结果是本 PR 本应提供的隔离能力被静默跳过:无视 abort 的运行仍在被守护进程判定为不安全的那一代里继续执行,该代仍为 active 并继续通过 admissibleChannelInfo() 接纳新会话,hasRunningTasks() 也持续为 true——于是 /clear、/resume、/branch 和会话切换被无限期拒绝,任务面板把该行显示为 — still stopping,而它的停止按钮同样是空操作(状态不再是 running 时 cancel() 会提前返回)。
修复方向是把 recycle 与可见通知解耦:给 registry 增加一个专用的一次性 unresponsive 结算钩子,由 failUnresponsive 无条件调用,并把 sessionRuntimeRecycle ext-method 接到该钩子上,而不是接到 #recordUnresponsiveAgentNotification。这样 record-only 通知仍保持幂等,而 recycle 一定跟随升级发生。
约束:background-tasks.ts:1760-1763 在调用回调前置位 notified,以便回调链中的重入终态调用短路而不是重复触发——不能靠重复发送已投递的终态通知来换取 recycle。
验收标准:扩展 background-tasks.test.ts 中的 'retains the physical slot when the cancel grace timer finalizes before the escalation',断言即便通知回调只为取消触发过一次,新的 unresponsive/recycle 钩子也触发了一次;并移除该钩子验证测试变红。
— qwen3.8-max via Qwen Code /review (v0.23.3)
|
Closeout round Answering the two "Unresolved, please confirm" items in review 5189445584's body:
Maintainer decision needed (this is the merge-blocking question, and I am deliberately not settling it myself):
The question is which terminal record should win on the watchdog-aborts-first, The other five unresolved threads remain escalated as human-gated and were already re-verified against this exact head, so I have not repeated those replies: R6-2, R6-3, R1-36 and R9-1 in round |
Local runtime validation — real
|
head 93eef769 |
base b5c7635 |
|
|---|---|---|
| subagent model request parked | 07:58:48 | 07:58:48 |
| outcome | request aborted at 08:13:48 (15:00 later); entry failed · Background agent made no model/control progress for 900000ms. at t=901.2 s; exactly one parent notification turn; no retry |
still running, request still parked at t=942 s |
(With the default provider timeout the picture is different — see §9.)
2. Model/control and per-tool deadlines (compressed head)
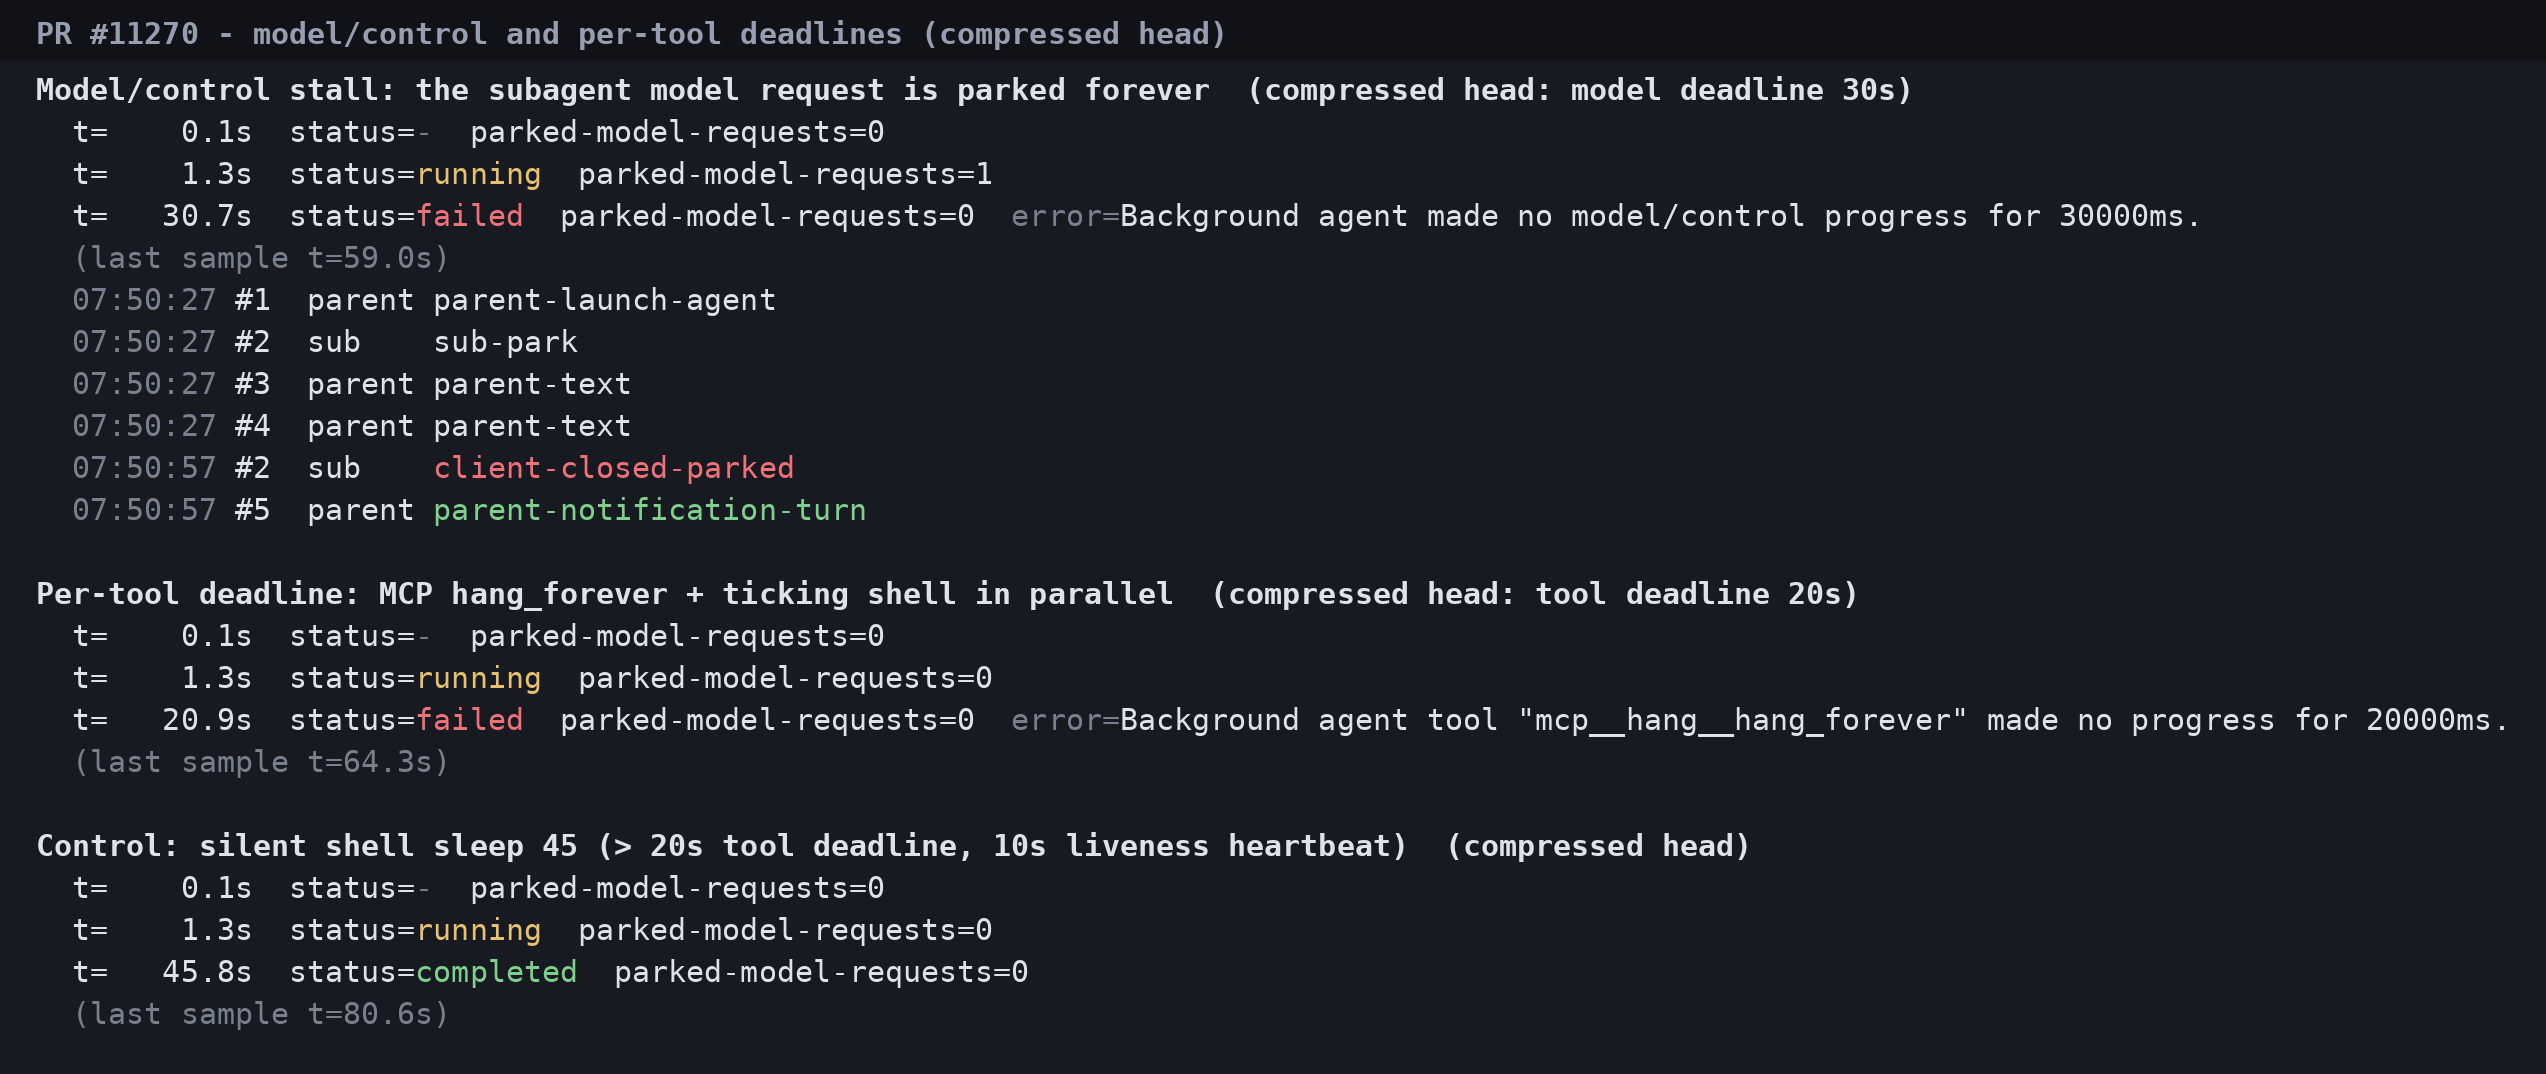
- Model/control stall: the subagent's model request is parked. At t=30.7 s the entry turns
failedwithBackground agent made no model/control progress for 30000ms.; the parked request is aborted by the client; the subagent made one request (no retry); the parent receives exactly one notification turn. - Per-tool, independent:
mcp__hang__hang_foreverand a ticking shell run in parallel. At t=20.9 s the Agent fails withBackground agent tool "mcp__hang__hang_forever" made no progress for 20000ms.while the shell was still producing output — only the silent tool's deadline expired. - Heartbeat control: a silent
sleep 45shell (longer than the 20 s tool deadline) completes at t=45.8 s — the 10 s shell liveness heartbeat renews its deadline, as documented.
3. Approval park — real TUI, bubbled background approval
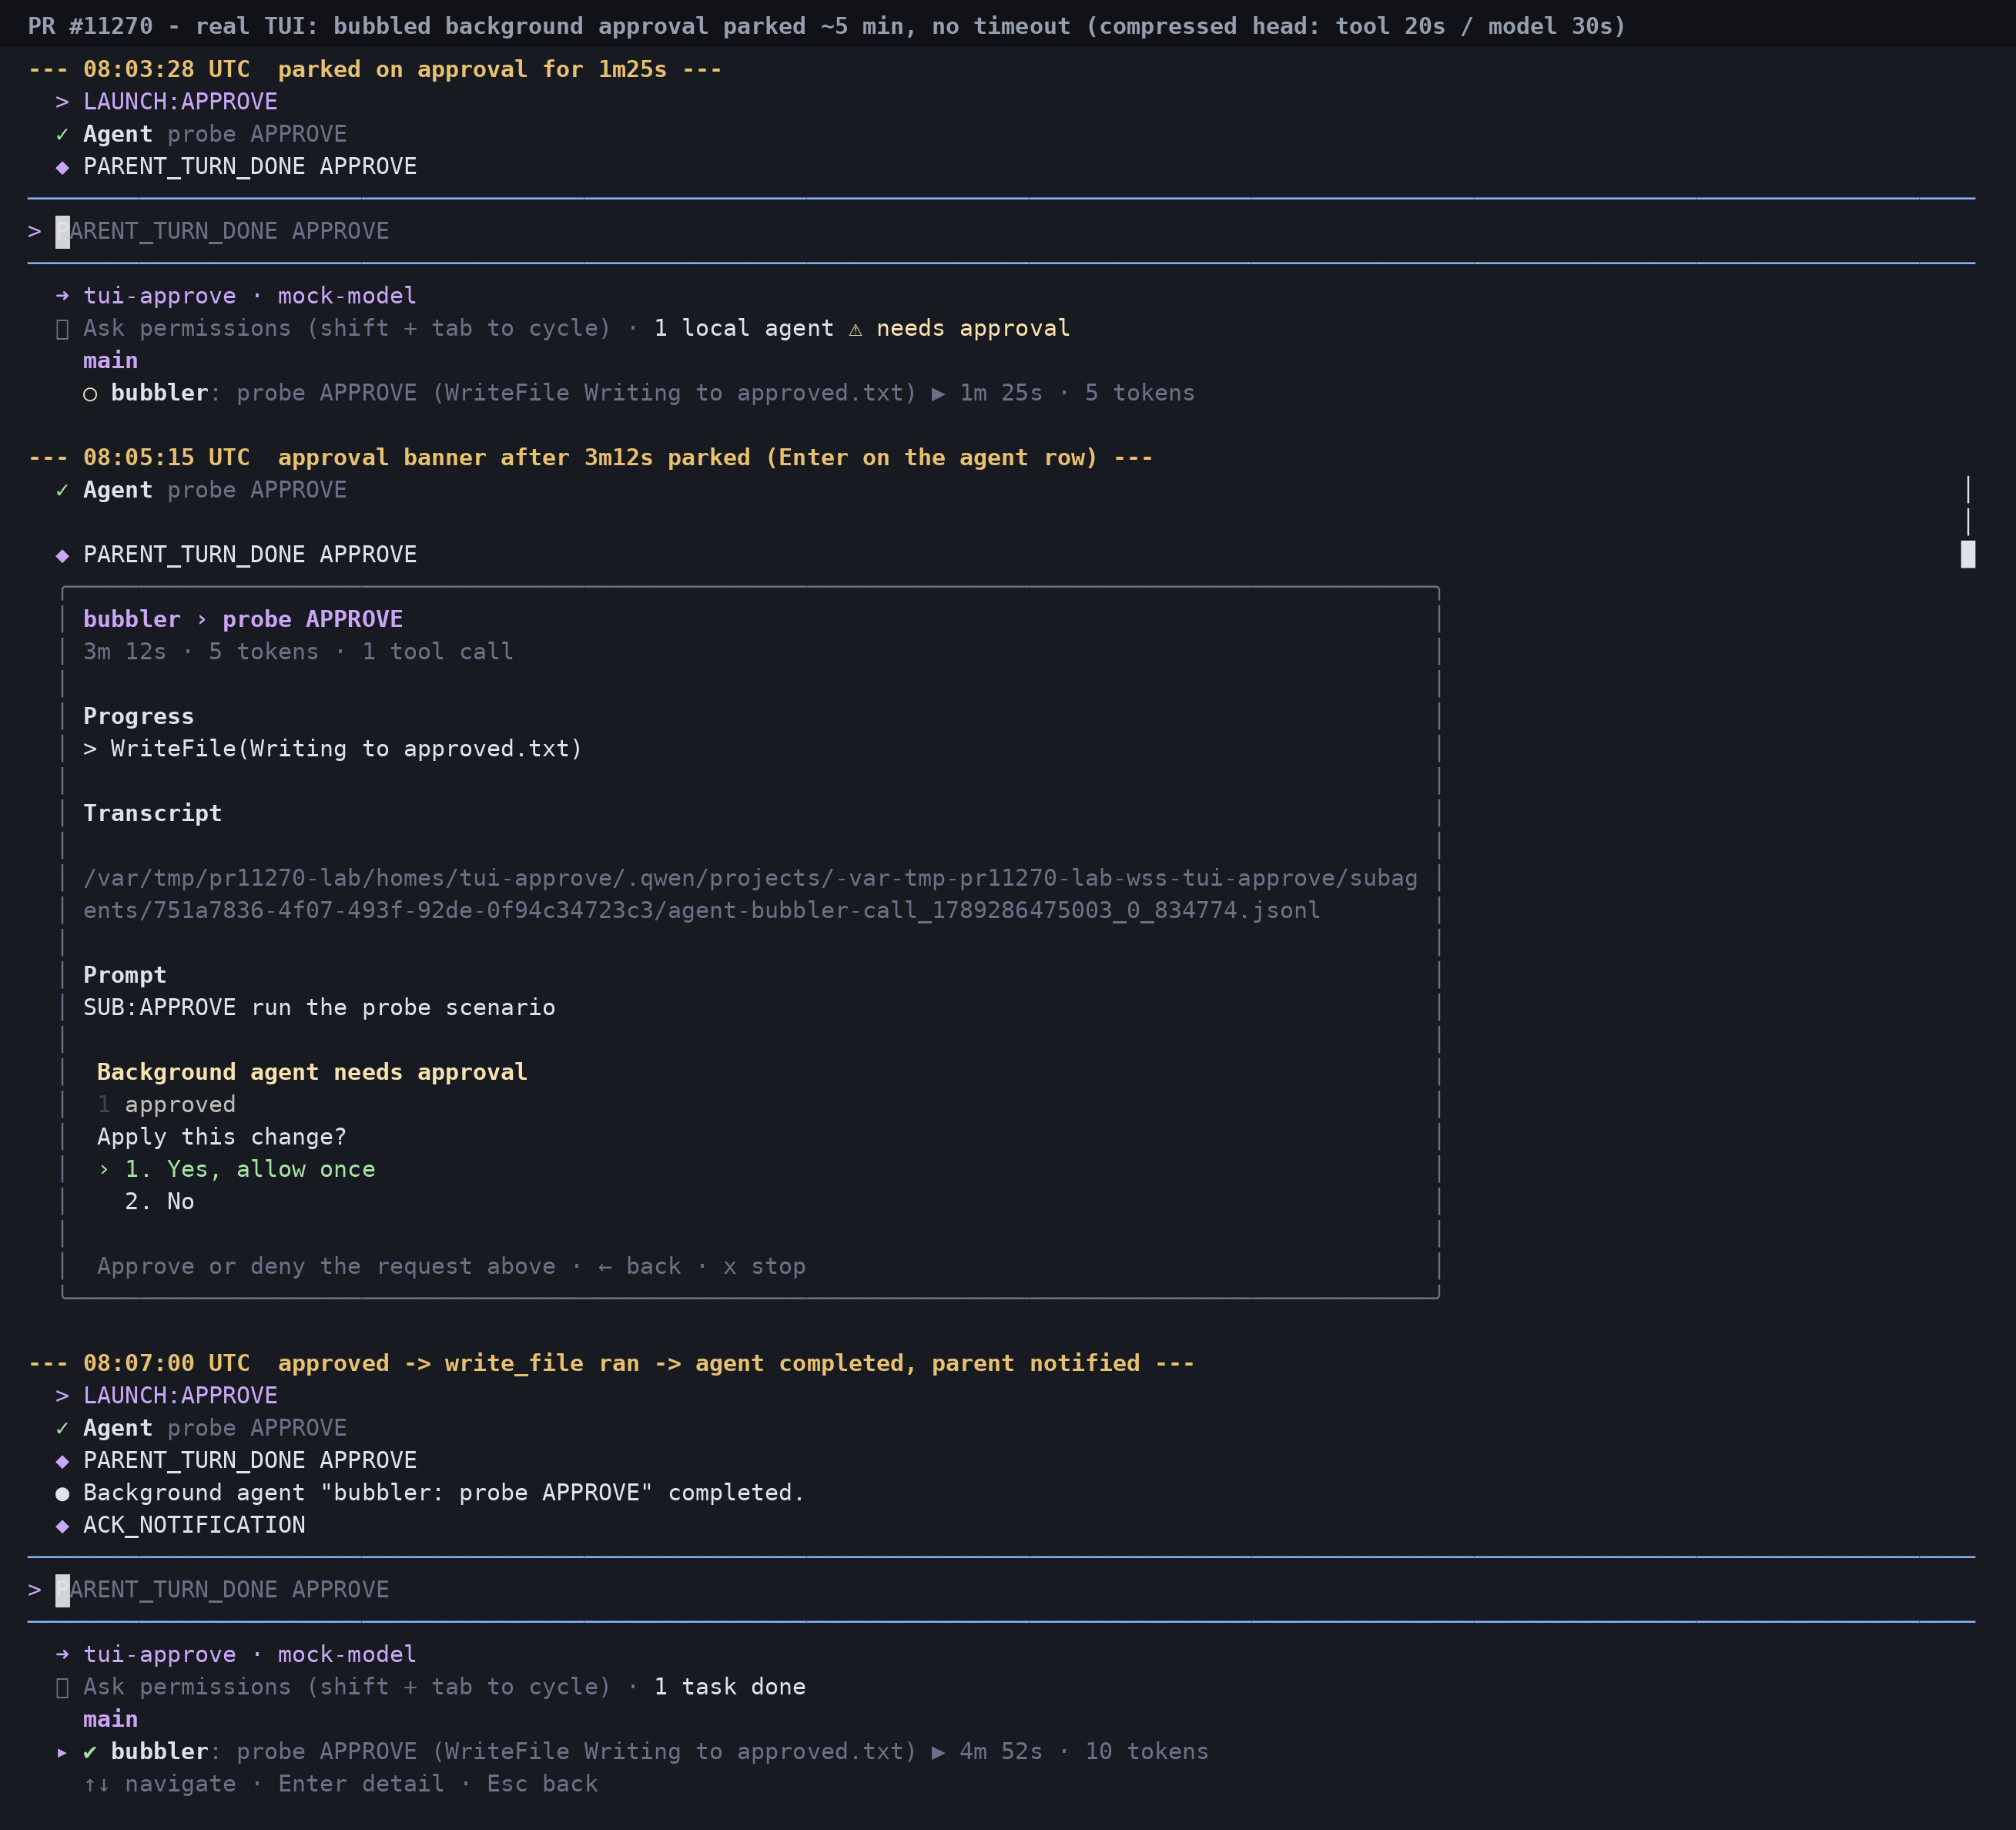
Custom agent with approvalMode: bubble, parent in Ask permissions. The background write_file approval was parked from 08:02:02.9 until I approved it at 08:06:55.6 (4 m 53 s, on the 20 s / 30 s compressed arm) with the Agent still running and the footer showing ⚠ needs approval. After Yes, allow once the tool ran (approved.txt written), the subagent's final request went out, and the TUI printed Background agent "bubbler: probe APPROVE" completed. followed by one parent notification turn. (Note: bubbling only exists in the interactive TUI — shouldBubble requires config.isInteractive(), so daemon background Agents auto-deny instead of parking.)
4. Restored run, resident continuation, Monitor-owned wait
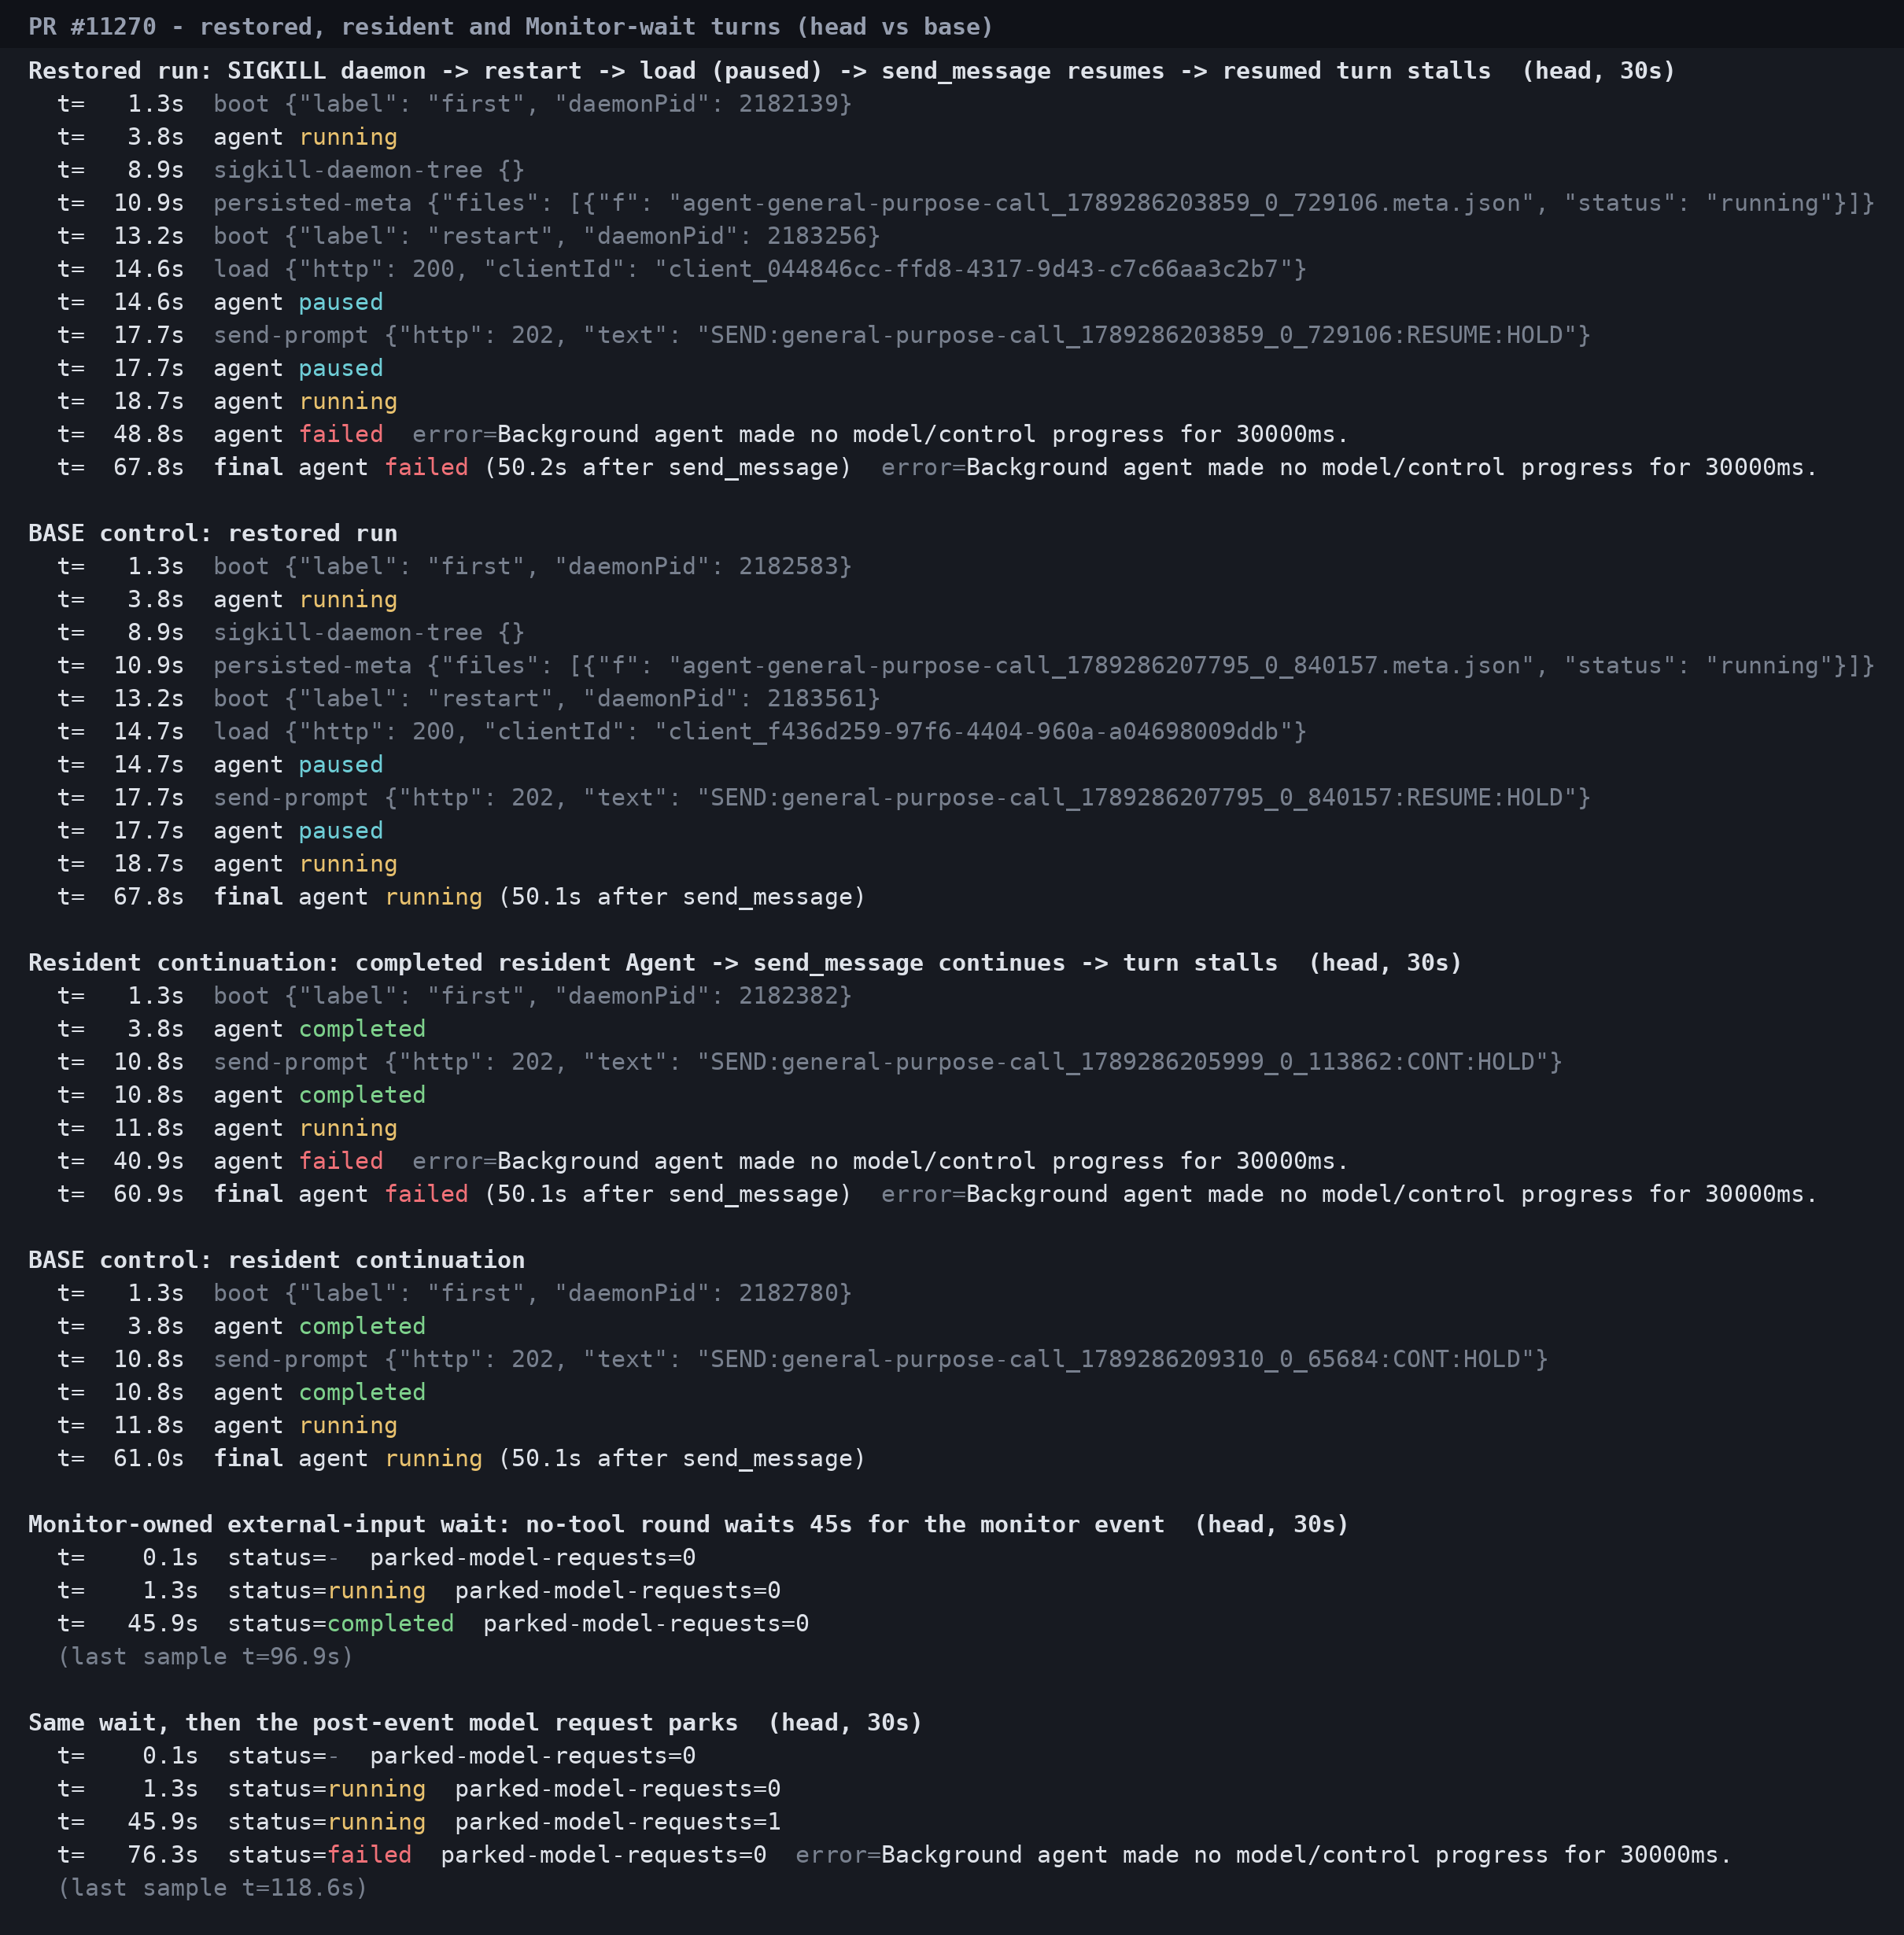
| scenario | head (30 s) | base |
|---|---|---|
Restored run — SIGKILL the daemon tree mid-run (sidecar still running), reboot, POST /session/:id/load → paused, parent send_message → resumed with your message… → resumed turn stalls |
failed · no model/control progress for 30000ms at +30 s, parent notified |
still running at +50 s |
Resident continuation — completed resident Agent, send_message → continued on its existing runtime… → turn stalls |
failed at +30 s, parent notified |
still running at +50 s |
Monitor wait — subagent starts monitor (event after 45 s), ends a no-tool round |
no timeout during the 45 s wait; completes after the event | — |
| Monitor wait, then stall — same, but the post-event model request parks | no timeout during the wait; fails 30 s after the event (deadline resumes on delivery) | — |
5. Escalation → owner-generation recycle (the consolidated half)
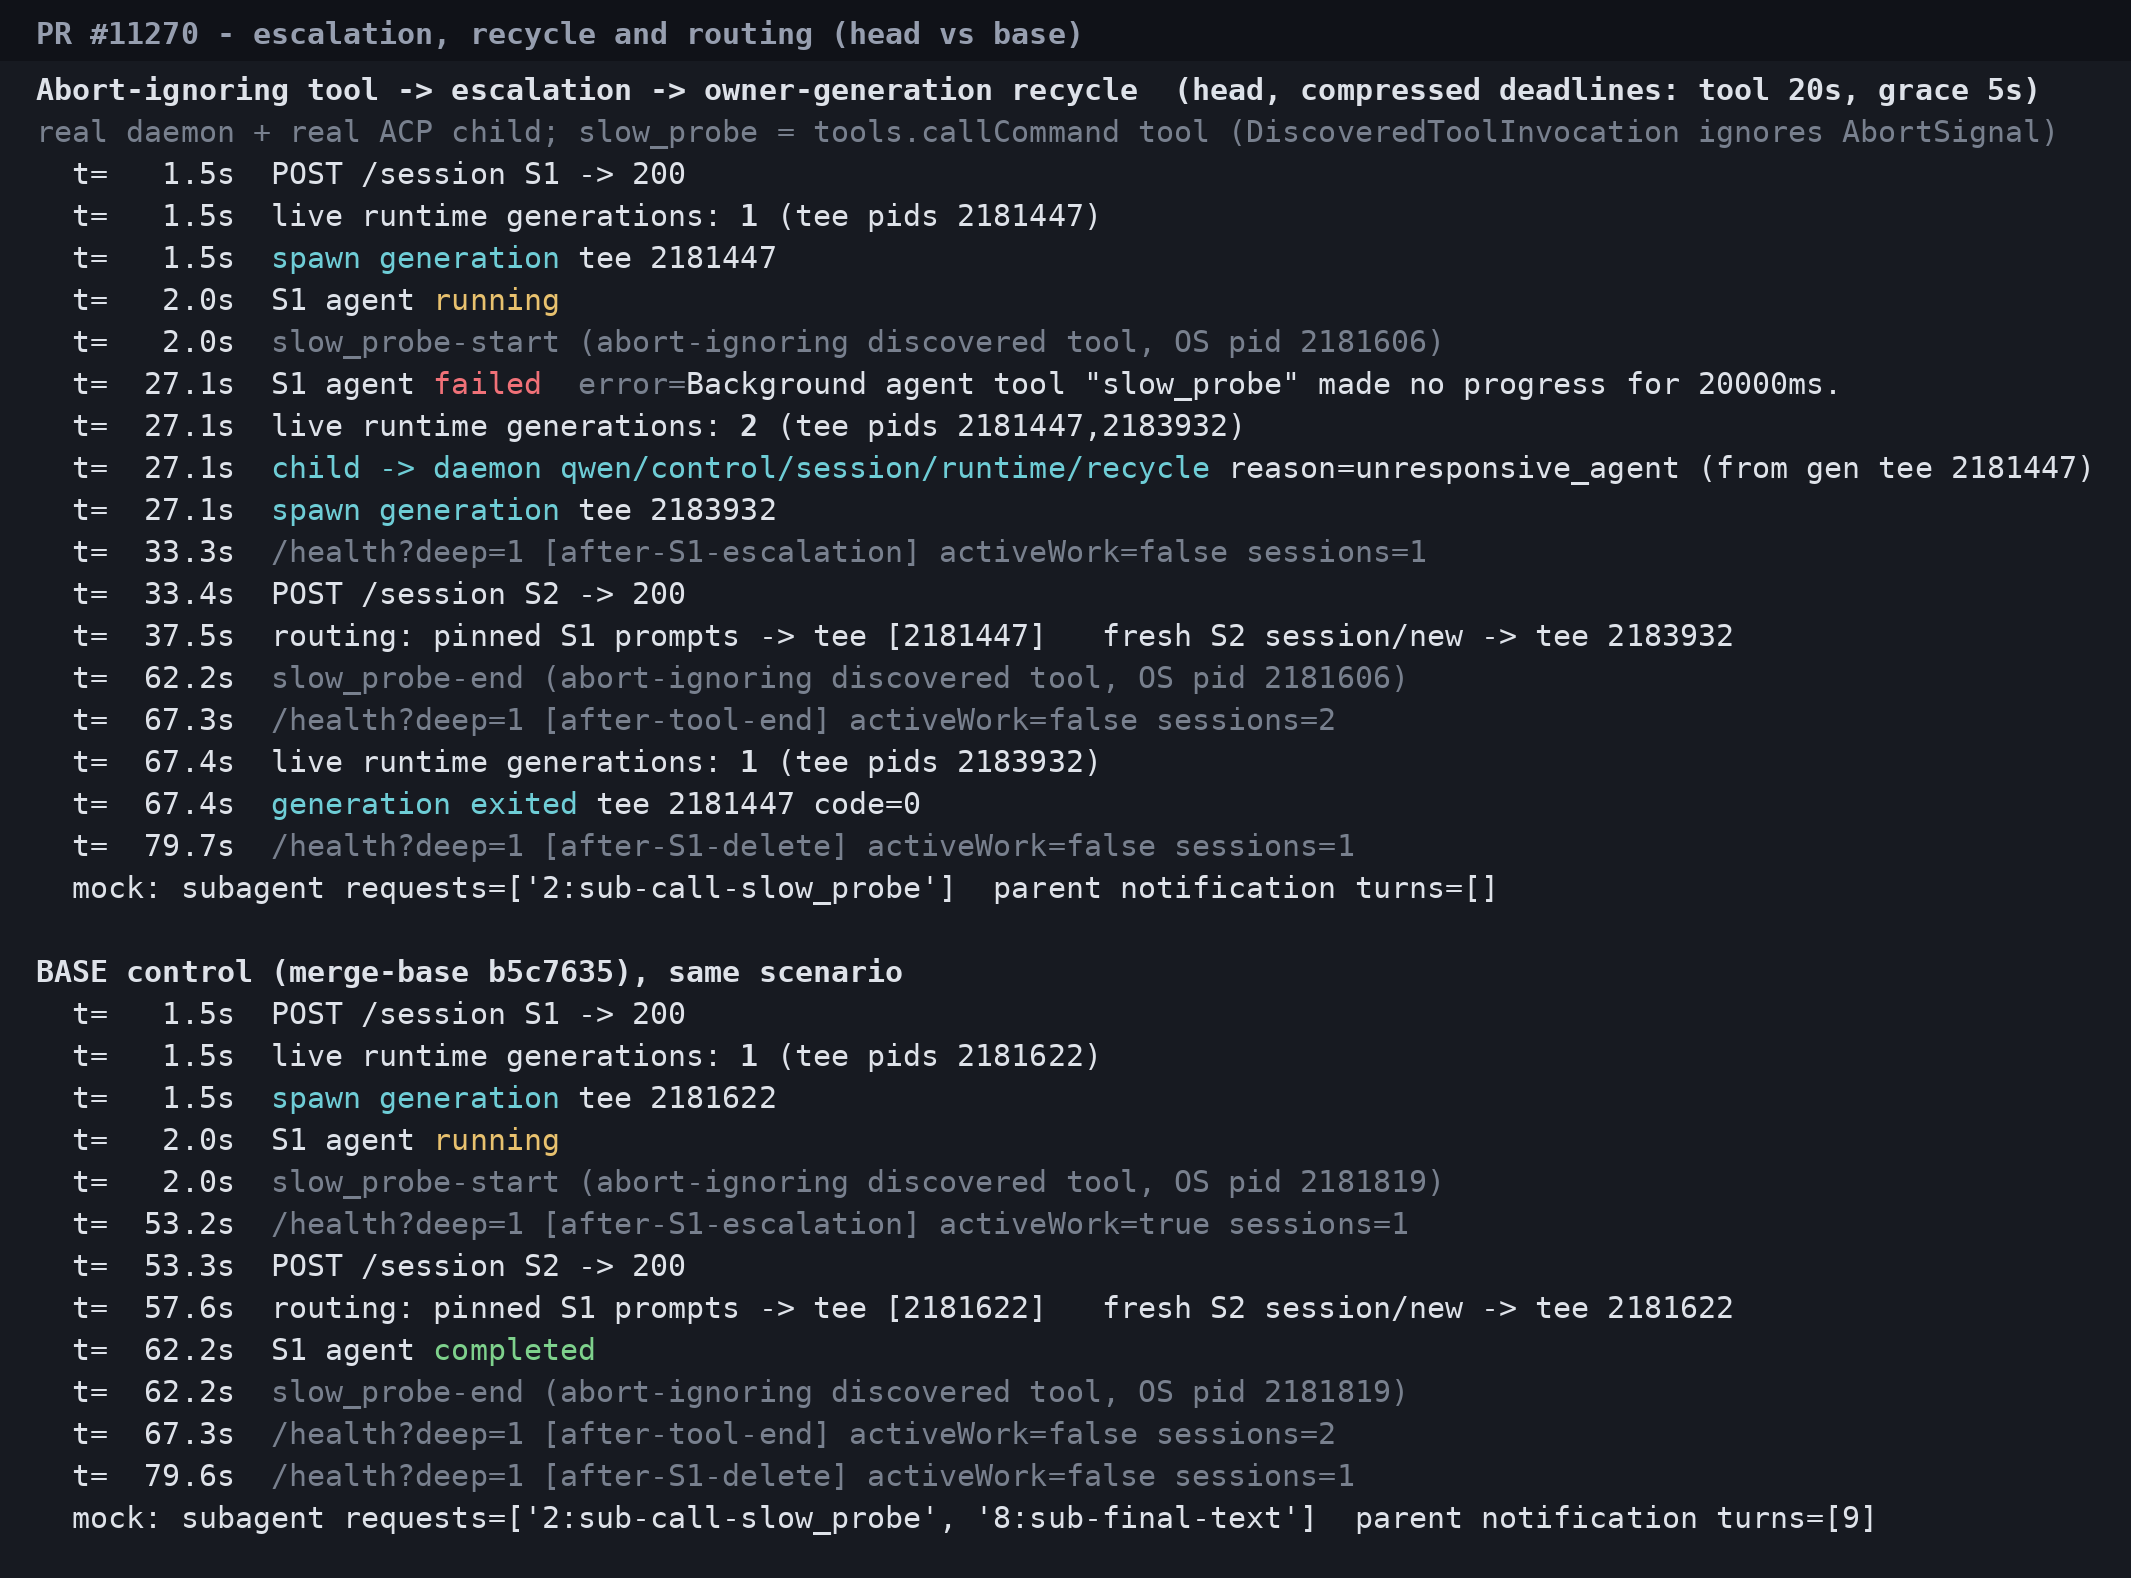
Head, abort-ignoring slow_probe (60 s):
- tool-start +25.2 s (20 s deadline + 5 s grace): entry
failed·Background agent tool "slow_probe" made no progress for 20000ms. - the child sends
qwen/control/session/runtime/recycle {reason: "unresponsive_agent"}; a second generation spawns 36 ms later; the daemon logsruntime recycle requested … deferring channel retirement until 1 active session(s) drain. - routing: prompts on the pinned session S1 keep going to the old generation; a fresh
POST /sessionlands on the replacement. - record-only: no parent notification turn and no further subagent request.
- after the tool ends and S1 is deleted, the old generation exits
code=0; one generation remains.
Base, same scenario: one generation throughout, the Agent stays running for the full 60 s and then completes normally with a parent notification.
The same two paths in the real TUI
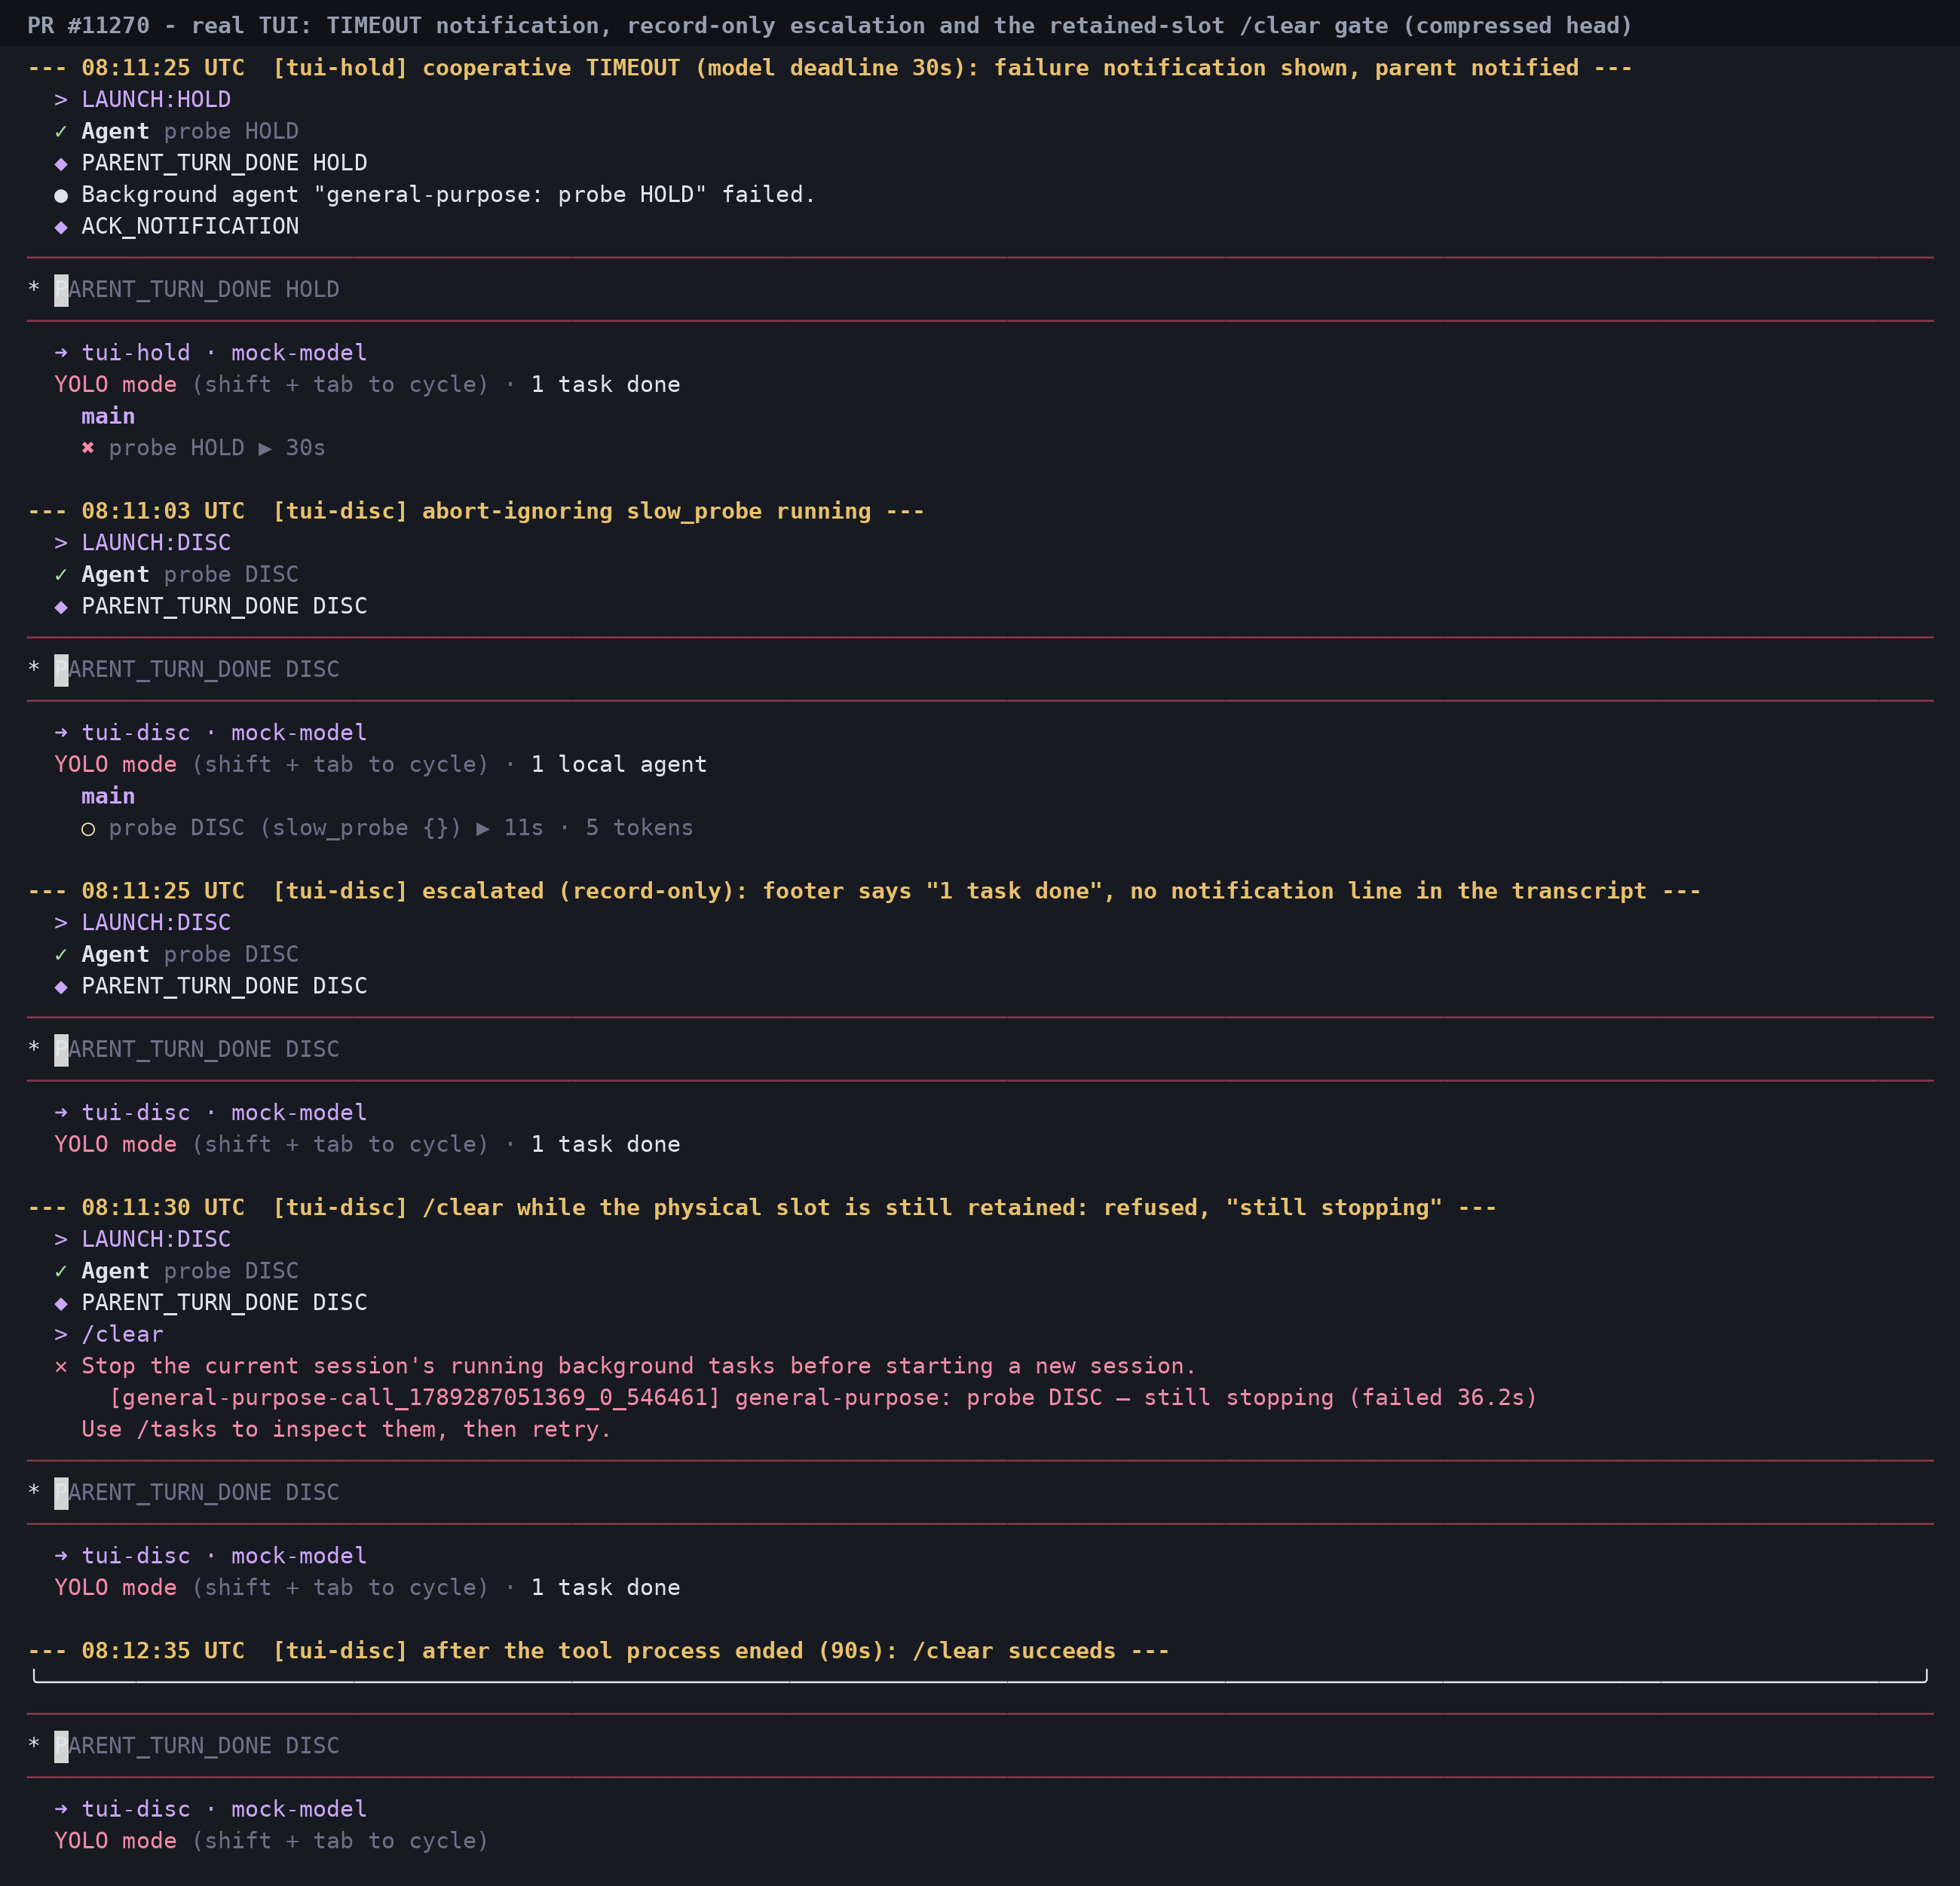
- Cooperative TIMEOUT:
● Background agent "general-purpose: probe HOLD" failed.appears in the transcript, the parent gets its notification turn, and the row shows✖ probe HOLD ▶ 30s. - Escalation (record-only): the footer flips to
1 task done, but no notification line is printed — the interactive TUI dropsrecordOnlynotifications (use-llm-stream.tsreturns early; already tracked as R1-9). The user only learns what happened from/tasksor the gate below. - Retained slot gates
/clear: while the abort-ignoring tool is still alive,/clearis refused with… probe DISC — still stopping (failed 36.2s). Once the tool's OS process ends (90 s),/clearsucceeds. So in the TUI the retained physical slot does protect session reset — contrast with the daemon detach path in §7.
Findings / decision inputs
6. R1-29 reproduced on the live daemon — a successful cancel is silently rewritten. POST /session/:id/tasks/:taskId/cancel at tool-start +22.0 s (inside the 5 s grace after the 20 s deadline) returns 200 {"cancelled":true,"status":"cancelled"}, and the task list shows cancelled. At +25 s the escalation overwrites it to failed (watchdog error), requests the recycle, and the parent model receives no notification turn — neither the cancellation nor the failure.
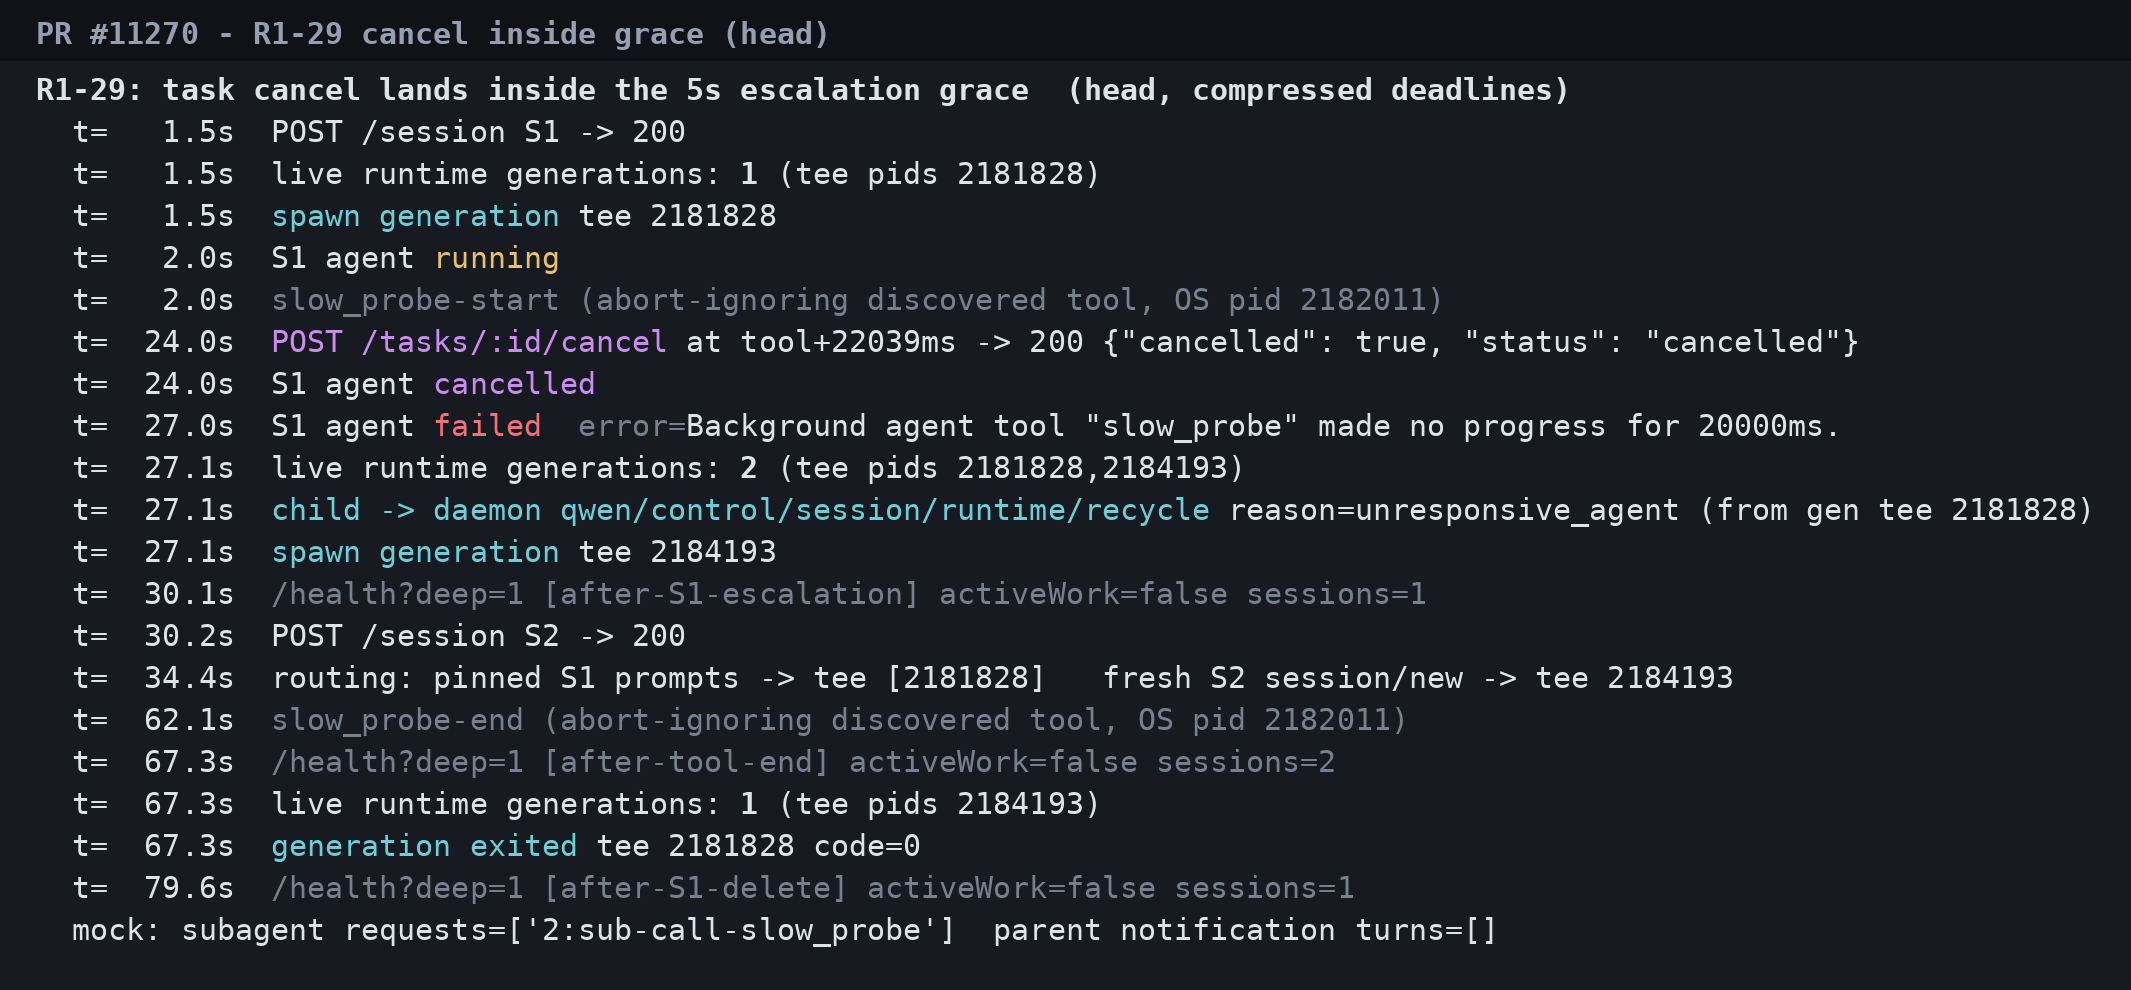
So the API tells the caller one terminal state and the registry/sidecar/model end up with another (or none). Whichever way the R1-29 / R6-5 question is ruled, I'd suggest the rule also cover what the cancel route returns and whether the parent model is told.
7. The retained physical slot does not hold the daemon Session — detach reaps it and kills the still-running tool. After escalation the child's active-work holds come from listUnfinalizedBackgroundAgentIds() (running, or cancelled && !notified), so a failed + notified entry drops out even while retainsPhysicalSlot is set. Measured:
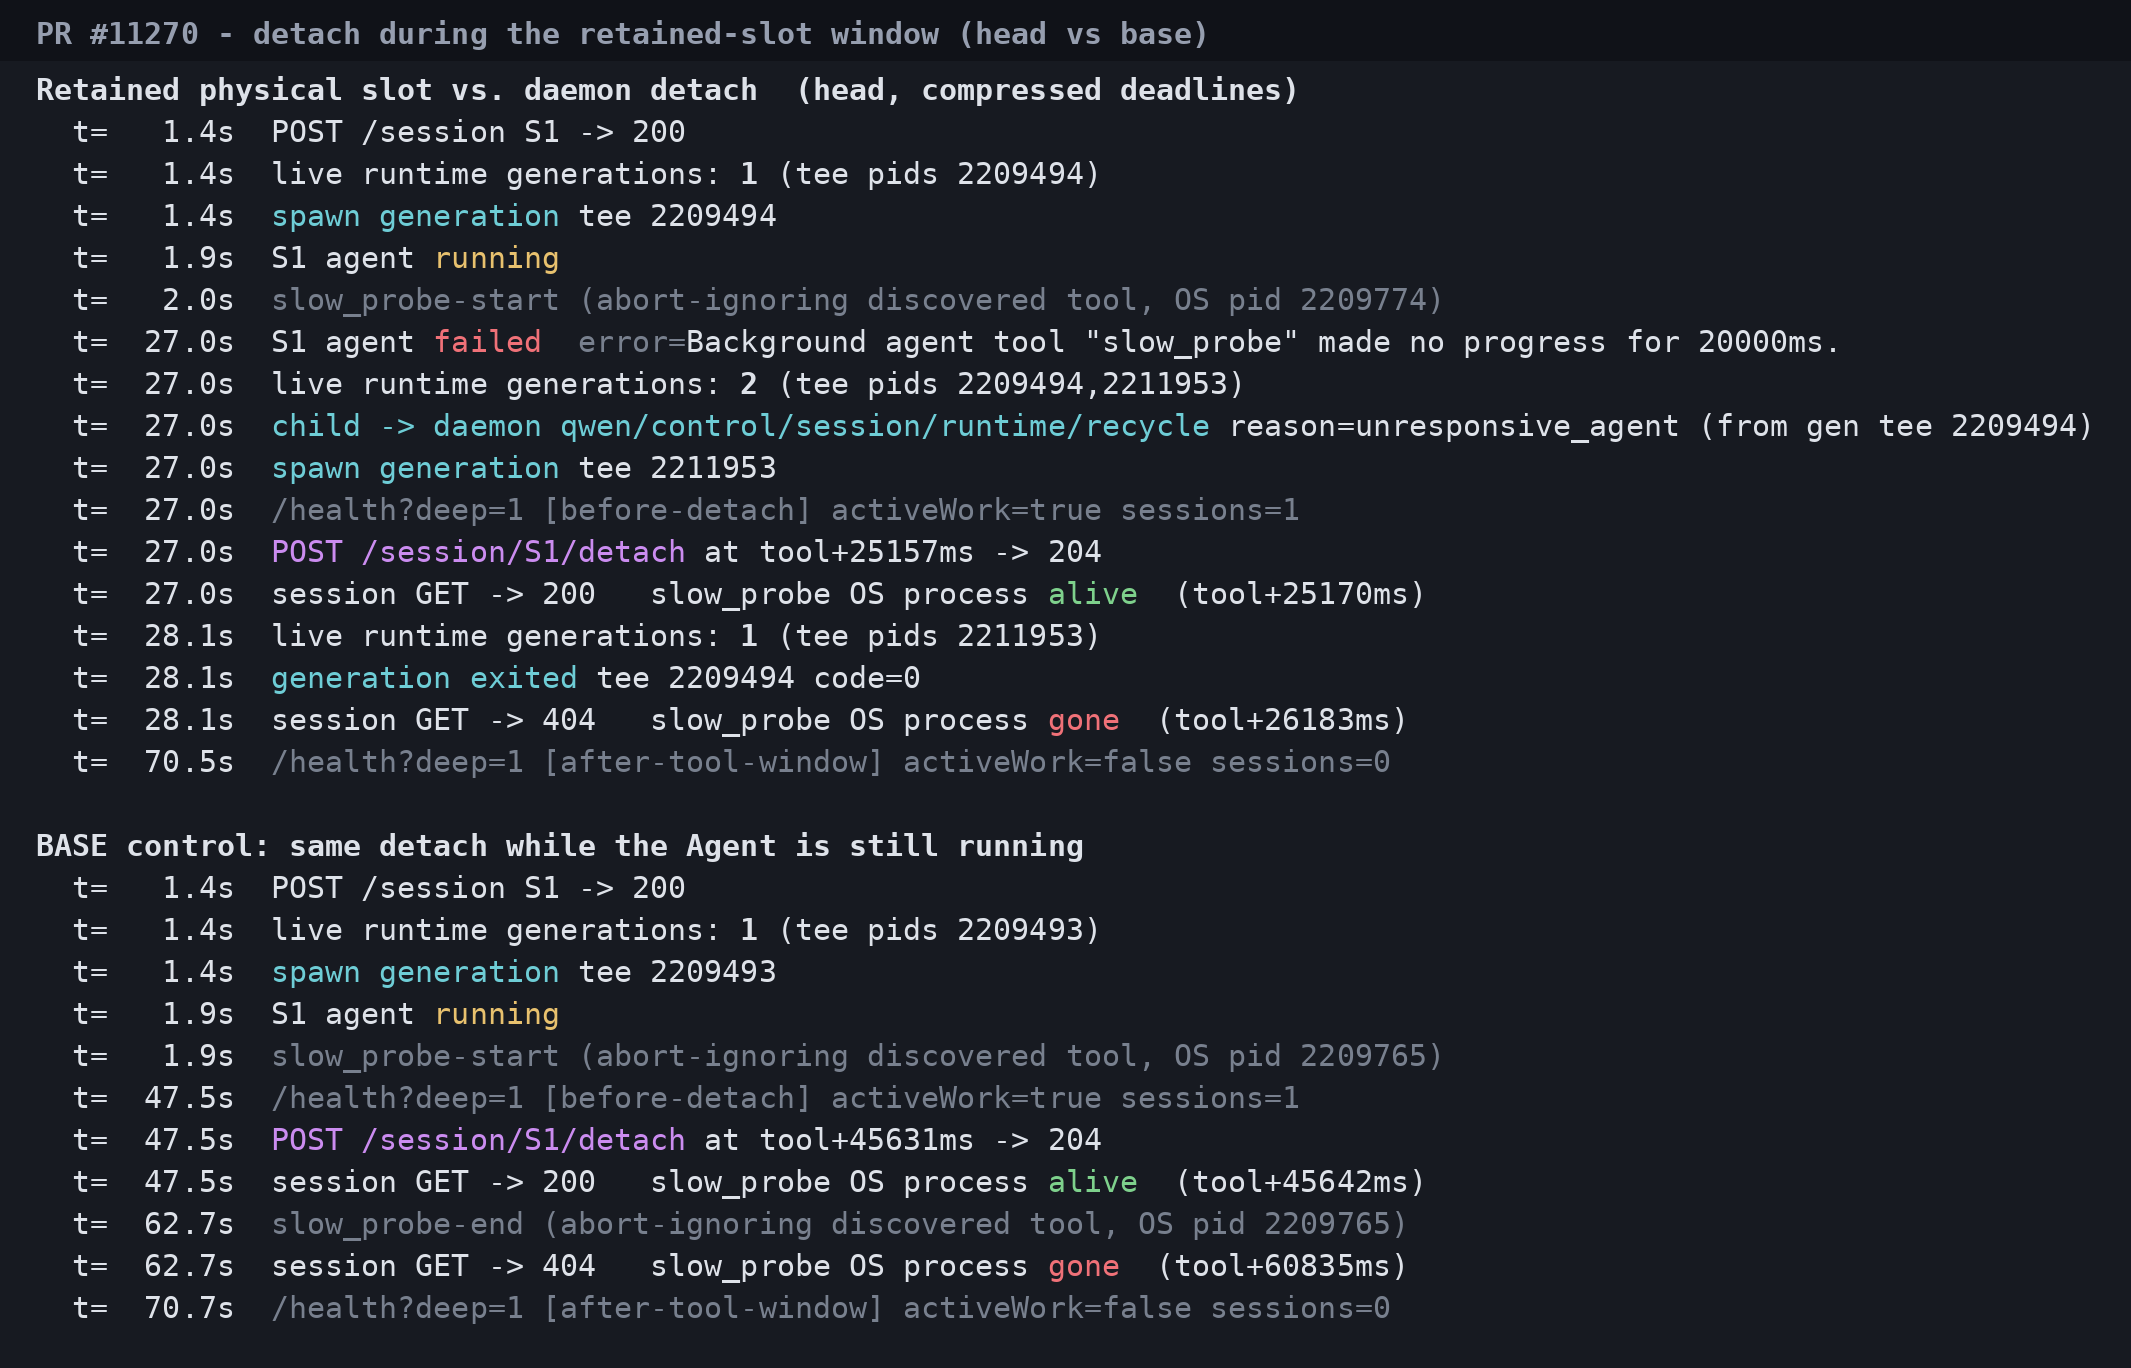
- head:
POST /session/S1/detachright after escalation (tool still running) → about 1 s later, once the notification-acceptance hold releases, the Session is closed (GET→ 404), the draining generation exitscode=0, and theslow_probeOS process is gone before its 60 s (it never logs its end). - base: the same detach while the Agent runs keeps the Session (
activeWork:true) until the tool finishes at 60.8 s, then closes normally.
This matters for R6-6b. At the daemon level the retained slot is already released through detach/close + generation exit, which contradicts the invariant at background-tasks.ts:920-934, and on a slow-but-alive tool it is a destructive difference from base. Either that is the intended remedy, and the invariant comment/design doc should say so, or collectActiveWorkHolds() should count retained slots.
8. Second recycle while the first generation is still draining — the workspace recovers, but the second recycle is dropped. S1's escalation moves the workspace to generation 2; then an Agent in S2 on generation 2 escalates while generation 1 still drains (S1's tool holds 150 s):
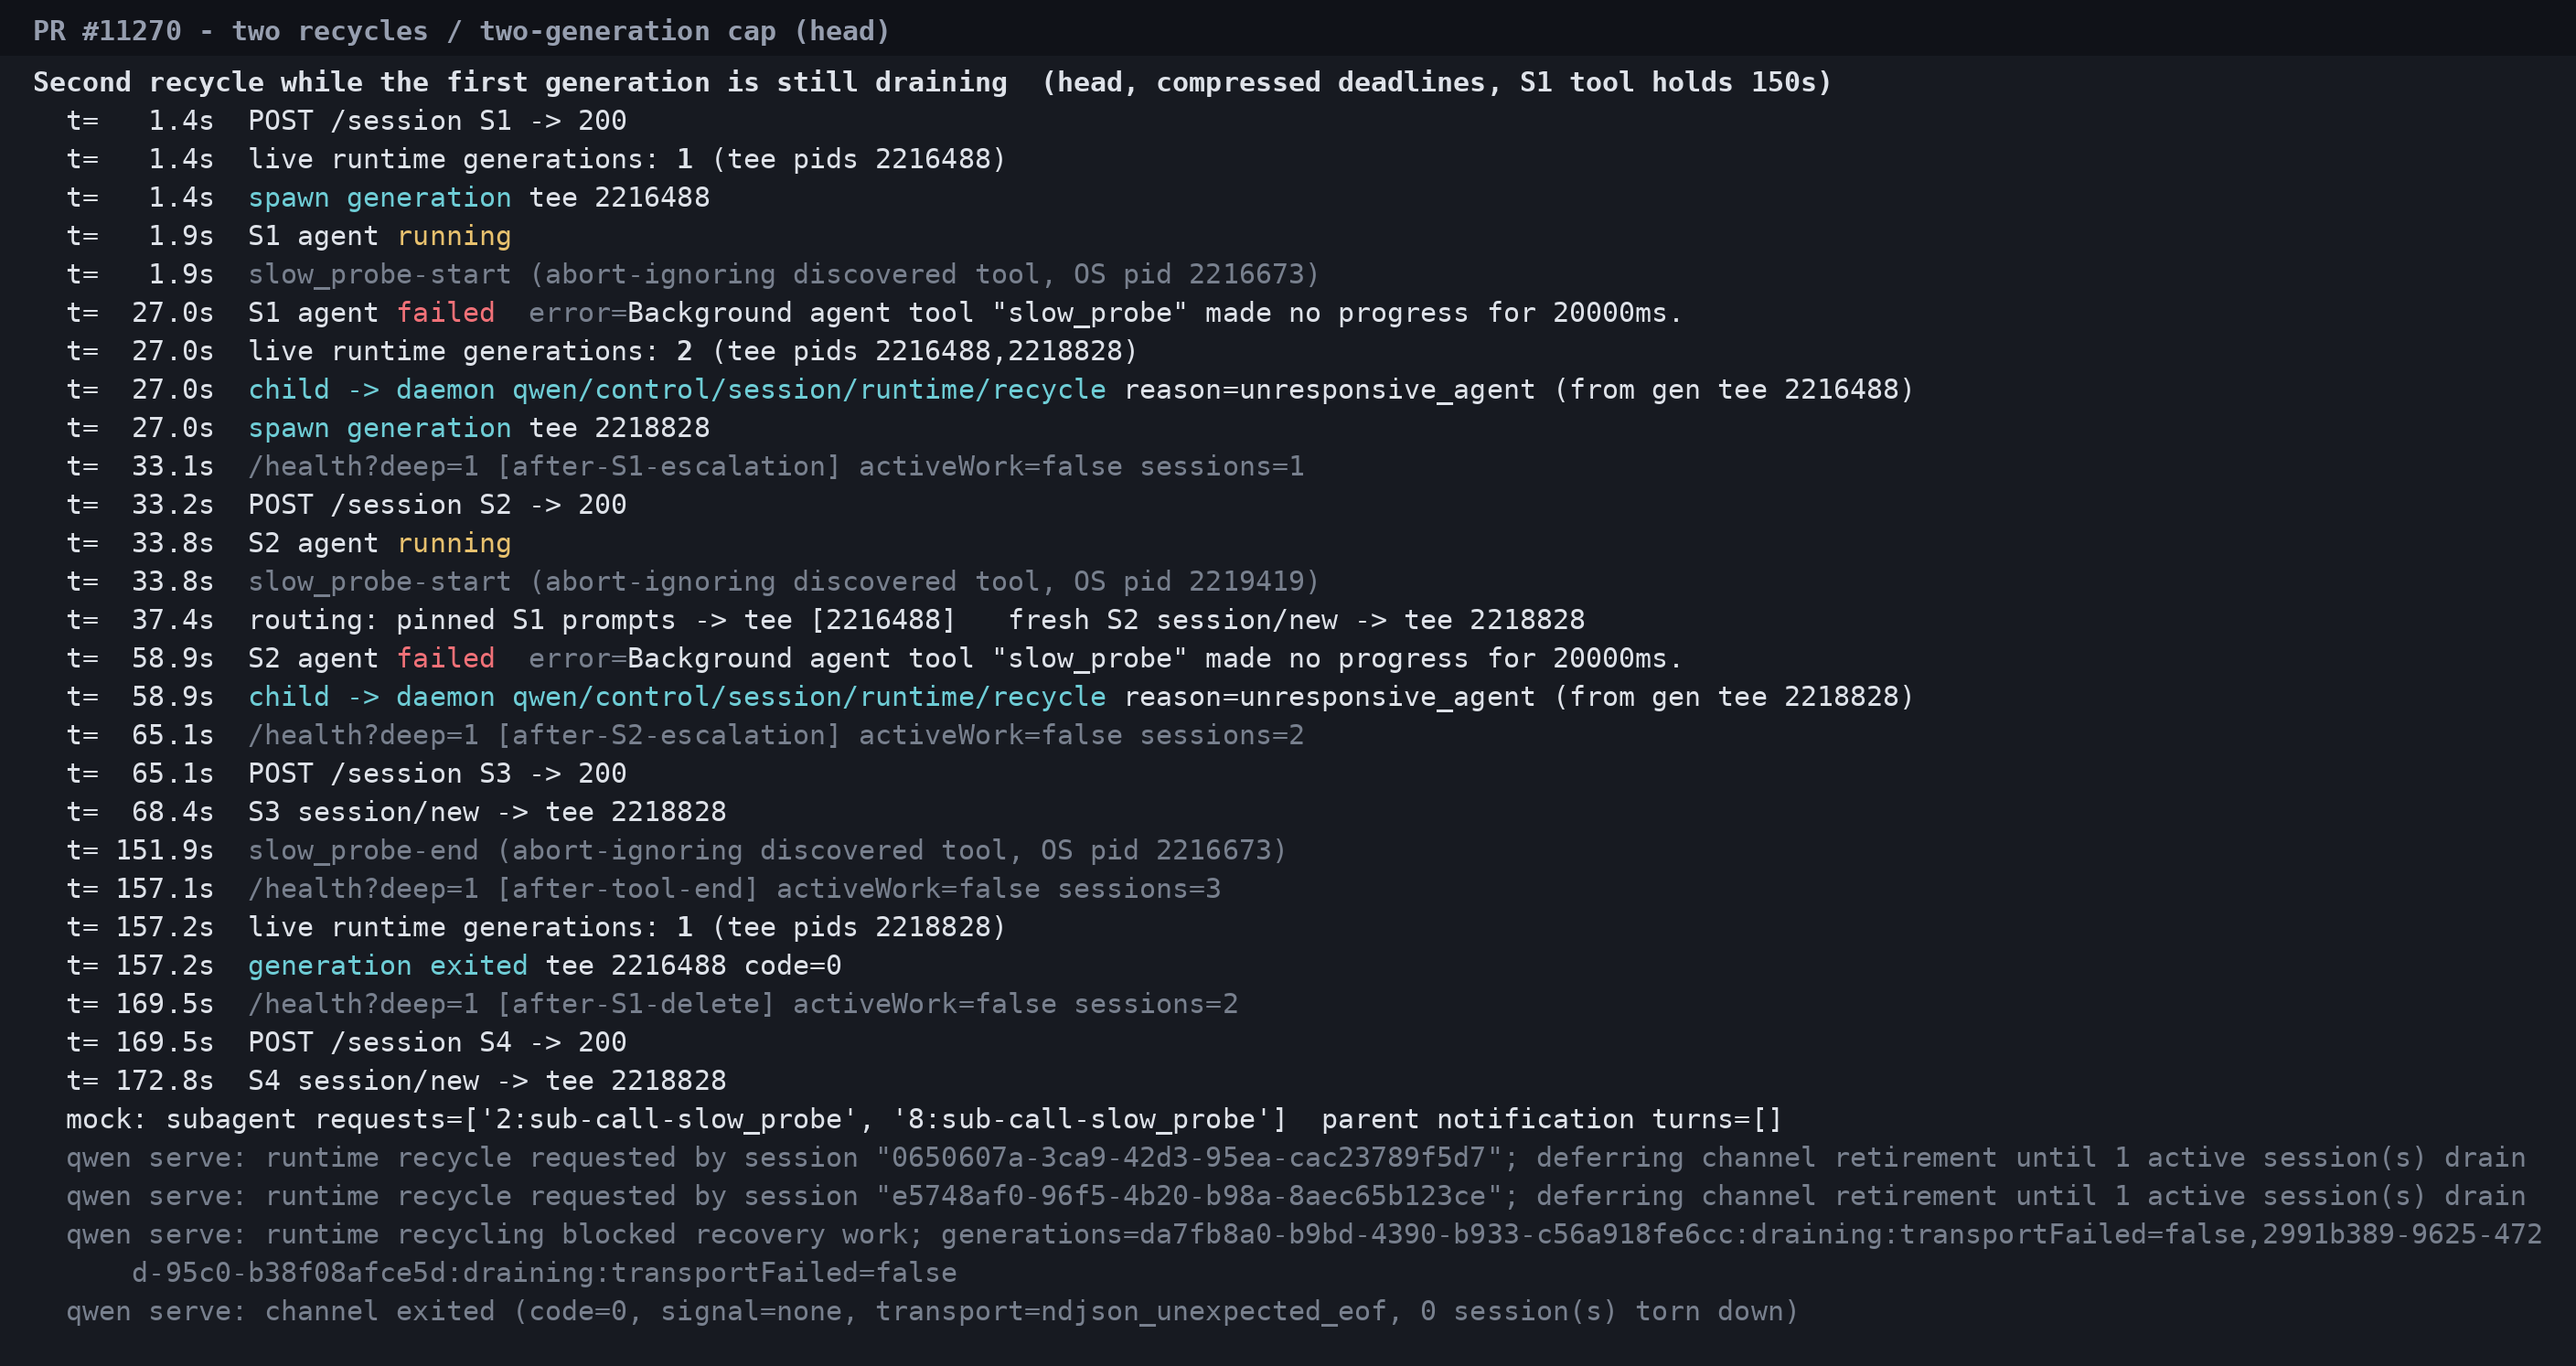
- the daemon logs
runtime recycling blocked recovery work; generations=…:draining…,…:draining…, and the child's recycle request is answered with JSON-RPC-32603 Internal error— not the retryableruntime_recyclingshape. - generation 2 is rolled back to
active: freshPOST /sessionS3 and S4 both return 200 (no 503 stranding) and land on generation 2 — the generation that still hosts S2's unresponsive Agent. - after generation 1 exits, nothing retries the recycle (
Session.#recordUnresponsiveAgentNotificationcalls the ext-method once and only logs a warning), so generation 2 keeps taking fresh work.
This answers the triage question from 6bc80c0 (the workspace does recover), but leaves the second unresponsive Agent's generation un-recycled. Worth a follow-up issue if not in scope here.
9. With default provider settings, a silently hanging provider never trips the model/control deadline. This is the same scenario as §1 with the default generationConfig.timeout (120 s), bottom half of the §1 image. On both arms the request is aborted every ~120 s and re-sent (12 attempts between 07:53:21 and 08:15:35, and the loop had not given up). Head is still running at the last status sample, t=1106 s (18.4 min), exactly like base, and its subagent was still retrying 22 minutes after the first park when I stopped both daemons.
The only difference from §1 is the provider timeout, so the cause is the retry path: each retry emits MODEL_RETRY, and onModelRetry → armModel(retryDelayMs) clears the timer and starts a fresh 15-minute window (plus the delay). The design doc says retry delays extend the deadline, but in practice the deadline becomes "15 min since the last retry", not "15 min without progress". A hung upstream is then bounded only by the retry budget, and that budget did not stop here.
This is probably the most common real-world stall shape, so it seems worth deciding whether a retry should extend the current window by retryDelayMs instead of restarting it. It overlaps R6-3 / R6-6a.
Tests on this head
packages/core:agent-progress-watchdog.test.ts+background-tasks.test.ts— 159 passed.packages/acp-bridge:bridge.test.ts— 941 passed.- CI on
93eef769a7: 23 pass / 27 skipping (macOS/Windows unit shards skipped).
Harness notes
tools.discoveryCommandtools are only registered whenQWEN_CODE_LEGACY_MCP_BLOCKING=1:Config.initialize()passesskipDiscovery: truein the default mode, anddiscoverAllTools()is the only caller of the command discovery. This predates the PR (config.tsis not in the diff); I used that escape hatch for the escalation scenarios.- The compressed arm differs from head only in the two literals above (checked with
grep -n "_MS = "on the patched file).
中文版
本地真实运行环境验证 —— 真实 qwen serve 守护进程 + 真实 TUI,head 与 merge-base 对比
我把两个分支分别从源码构建,在真实守护进程(每个 runtime generation 一个真实 qwen --acp 子进程、真实 REST 路由)和真实交互式 TUI 中端到端驱动本 PR,模型侧由按场景编排的 mock OpenAI 服务器充当观测点。下文没有任何 watchdog 的单测替身:每一次超时、通知、recycle、generation 的启动/退出都由各分支编译出的 dist 真实产生。
两个分支: head 93eef769a7 与 merge-base b5c7635ff9(21 个生产文件全部回退、删除 PR 新增的 watchdog 模块,并确认 base dist 中所有 PR 标记均不存在)。
时间压缩: watchdog 常量是硬编码的,因此大部分场景运行在 head dist 的一个副本上,只改了两个字面量(MODEL_CONTROL_PROGRESS_TIMEOUT_MS 15 分钟 → 30 秒,TOOL_PROGRESS_TIMEOUT_MS 10 分钟 → 20 秒;5 秒升级宽限期和 6 小时重试上限保持不变)。未修改的 15 分钟常量在 §1 单独验证。
观测点: 每秒一次的 GET /session/:id/tasks 状态/错误;mock 记录的每一次模型请求(谁发起、是否被挂起/中止、通知轮次);按 pid 标记的 QWEN_CLI_ENTRY tee,抓取每个 generation 的 ACP stdio(session/new / session/prompt 路由、qwen/control/session/runtime/recycle 帧、generation 启动/退出码);/health?deep=1;忽略中止的工具的真实 OS pid。
忽略中止的工具: 真实的 tools.discoveryCommand / tools.callCommand 工具 —— DiscoveredToolInvocation.execute(_signal, …) 从不观察 abort signal,因此这是生产代码路径,不是故障注入。
结论: watchdog、逐工具期限、审批/Monitor 暂停、恢复与驻留路径、以及升级 → owner generation recycle 均与描述一致,base 则表现出本 PR 要解决的卡死行为。PR 自带测试在本地全部通过。尚待维护者决定的问题是真实存在的,我在真实守护进程上测量了其中三个(§6–§8),便于基于证据而非阅读来裁定。
一、真实的 15 分钟期限(未修改常量),head 与 base 对比
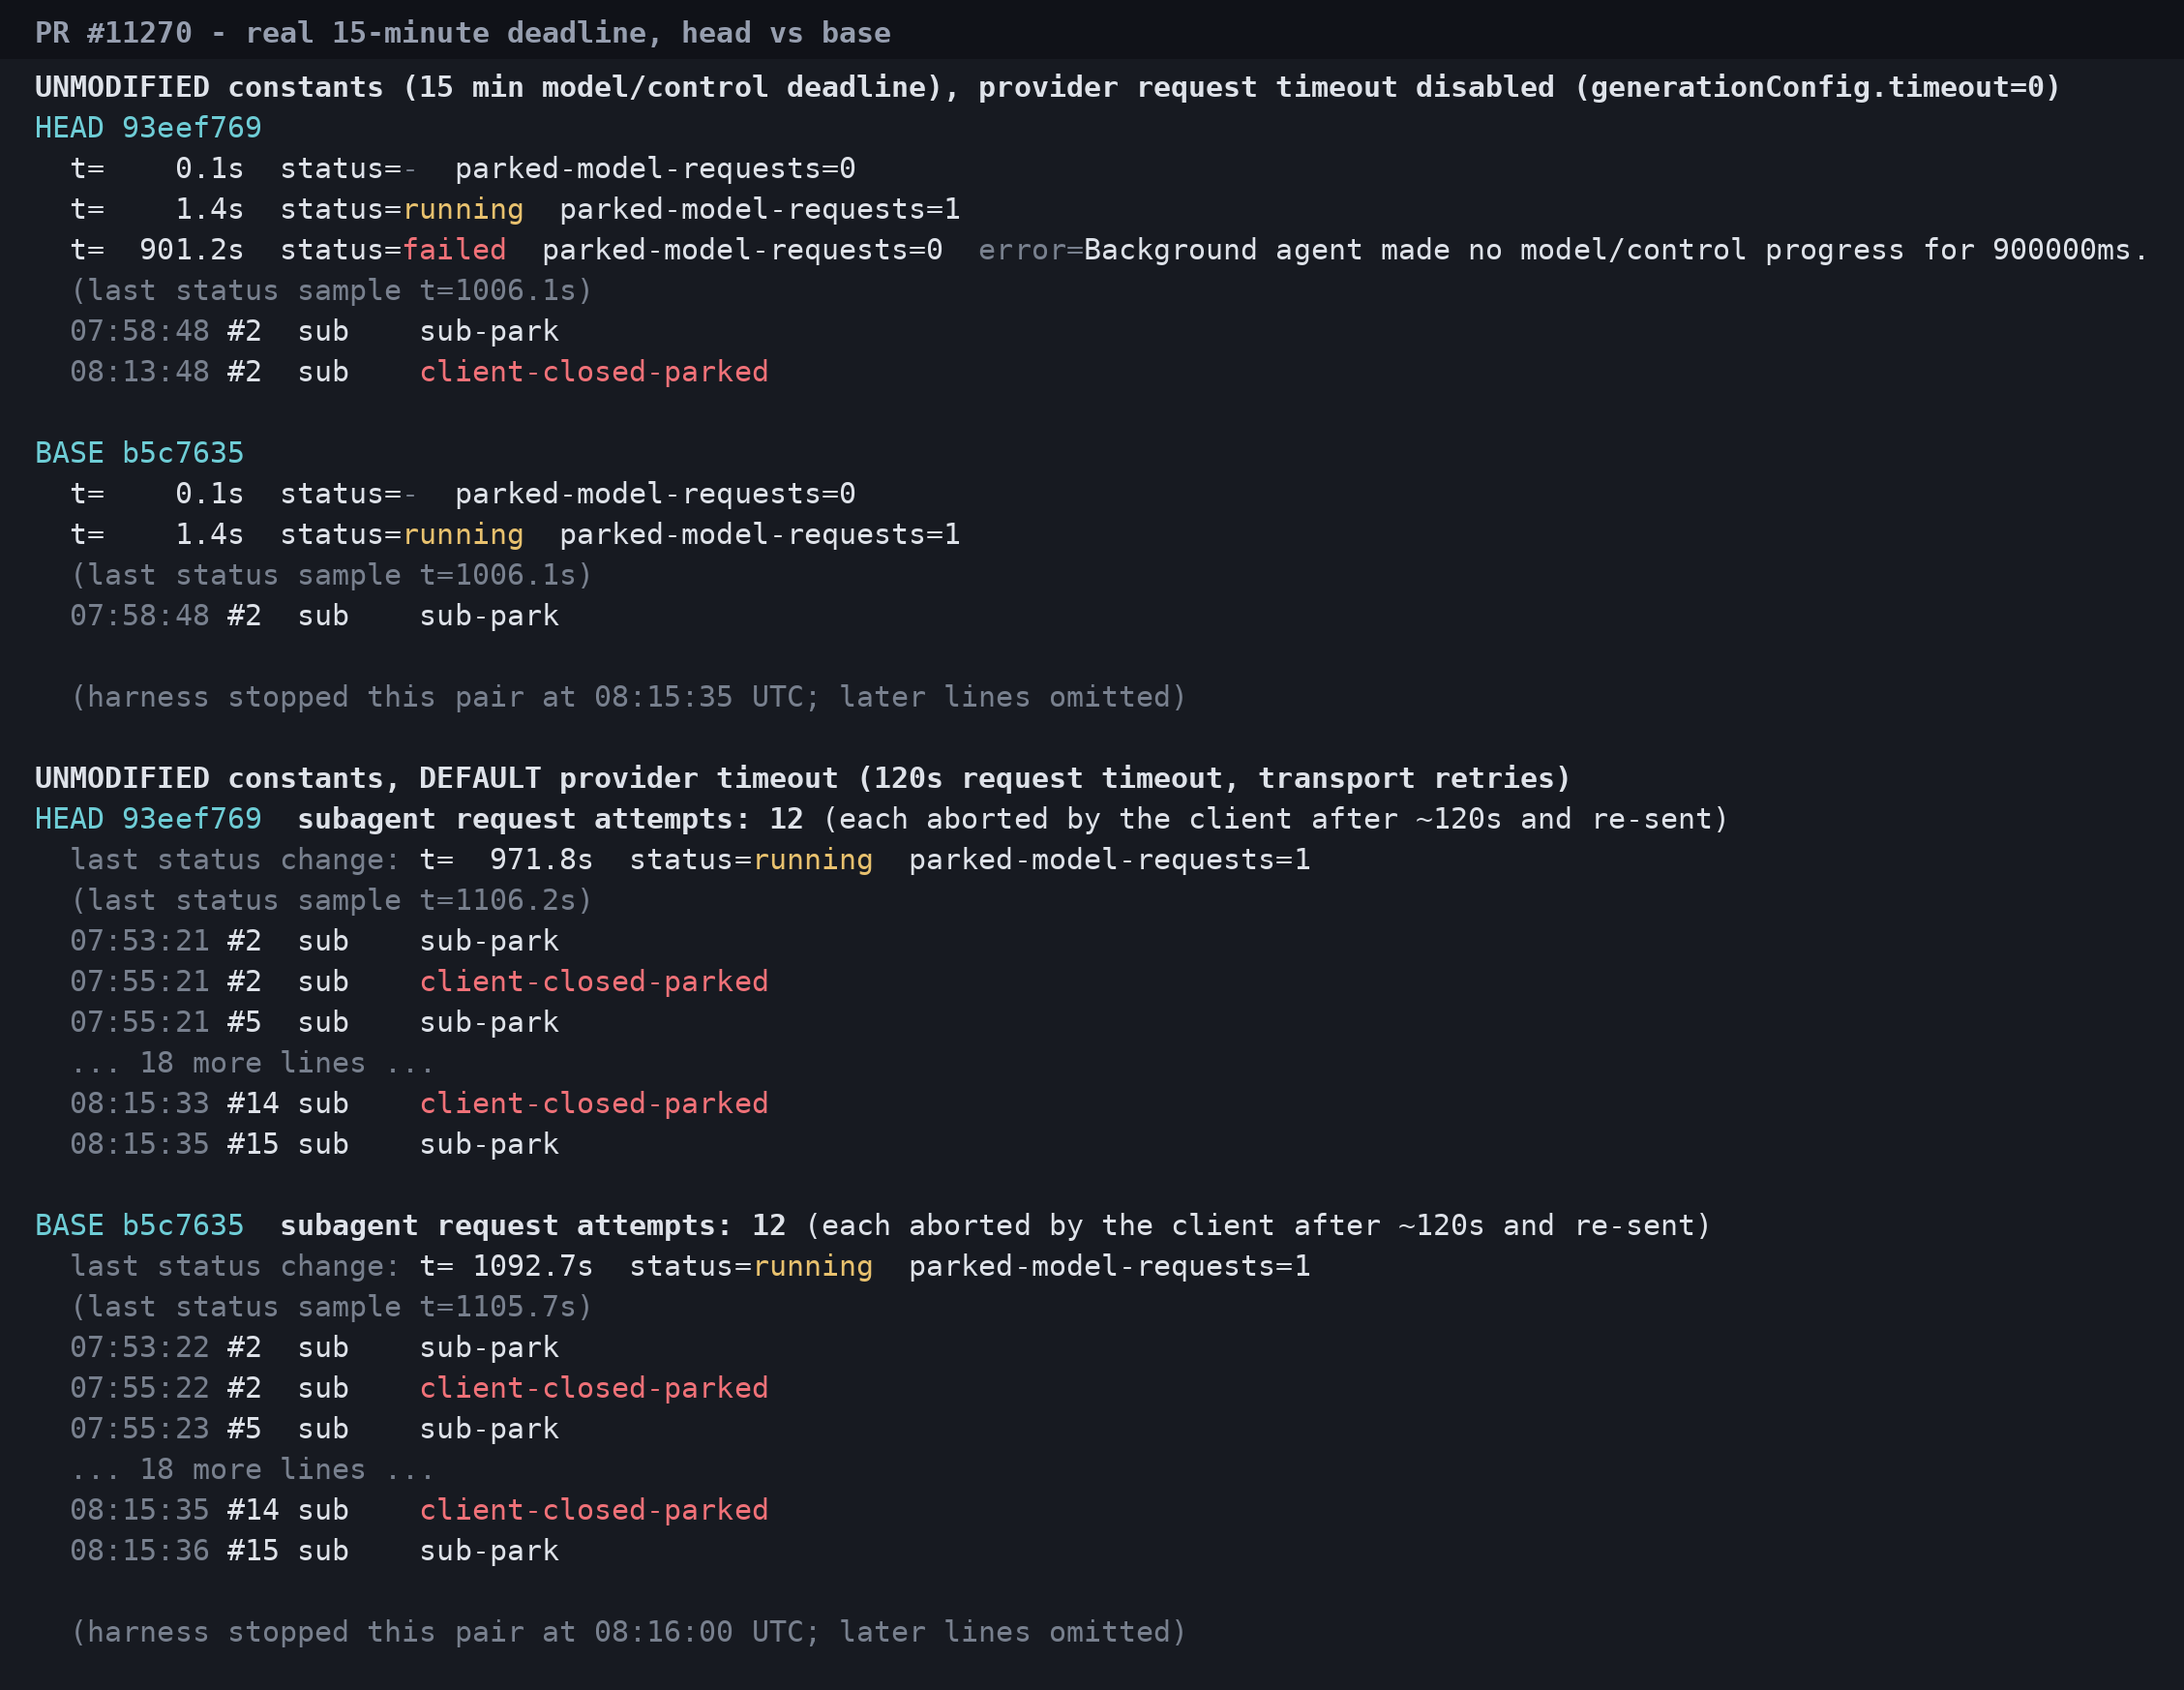
两个分支都使用未修改的 dist;关闭 provider 请求超时(model.generationConfig.timeout: 0),这样被挂起的子 Agent 请求除了 watchdog 之外没有任何其他上界:
head 93eef769 |
base b5c7635 |
|
|---|---|---|
| 子 Agent 模型请求被挂起 | 07:58:48 | 07:58:48 |
| 结果 | 请求在 08:13:48(恰好 15:00 之后) 被中止;t=901.2 秒条目变为 failed · Background agent made no model/control progress for 900000ms.;父会话恰好收到一次通知轮次;没有重试 |
t=942 秒仍为 running,请求仍被挂起 |
(使用默认 provider 超时时情况不同 —— 见 §9。)
二、模型/控制期限与逐工具期限(压缩后的 head)
- 模型/控制停滞: 子 Agent 的模型请求被挂起。t=30.7 秒时条目变为
failed,错误为Background agent made no model/control progress for 30000ms.;被挂起的请求由客户端中止;子 Agent 只发出了一次请求(没有重试);父会话恰好收到一次通知轮次。 - 逐工具、相互独立:
mcp__hang__hang_forever与一个持续输出的 shell 并行执行。t=20.9 秒时 Agent 失败,错误为Background agent tool "mcp__hang__hang_forever" made no progress for 20000ms.,而此时 shell 仍在输出 —— 只有静默工具的期限到期。 - 心跳对照: 一个静默的
sleep 45shell(比 20 秒工具期限更长)在 t=45.8 秒正常完成 —— 10 秒一次的 shell 存活心跳续期了它的期限,与文档一致。
三、审批暂停 —— 真实 TUI 中冒泡的后台审批
自定义 agent 设置 approvalMode: bubble,父会话处于 Ask permissions。后台 write_file 的审批从 08:02:02.9 一直挂起,直到我在 08:06:55.6 批准(4 分 53 秒,运行在 20 秒/30 秒的压缩分支上),期间 Agent 一直是 running,底栏显示 ⚠ needs approval。选择 Yes, allow once 后工具执行(写出 approved.txt),子 Agent 发出最终请求,TUI 显示 Background agent "bubbler: probe APPROVE" completed.,随后父会话收到一次通知轮次。(注:审批冒泡只存在于交互式 TUI —— shouldBubble 要求 config.isInteractive(),守护进程中的后台 Agent 会直接自动拒绝而不是挂起。)
四、恢复运行、驻留续跑、Monitor 外部输入等待
| 场景 | head(30 秒) | base |
|---|---|---|
恢复运行 —— 运行中 SIGKILL 整个守护进程树(sidecar 仍为 running),重启,POST /session/:id/load → paused,父会话 send_message → resumed with your message… → 恢复后的 turn 停滞 |
+30 秒 failed · no model/control progress for 30000ms,父会话收到通知 |
+50 秒仍为 running |
驻留续跑 —— 已完成的驻留 Agent,send_message → continued on its existing runtime… → turn 停滞 |
+30 秒 failed,父会话收到通知 |
+50 秒仍为 running |
Monitor 等待 —— 子 Agent 启动 monitor(45 秒后产生事件),然后结束一个无工具 round |
45 秒等待期间不超时;事件到达后完成 | — |
| Monitor 等待后停滞 —— 同上,但事件之后的模型请求被挂起 | 等待期间不超时;事件到达 30 秒后失败(投递后期限恢复计时) | — |
五、升级 → owner generation recycle(合并进来的另一半)
head,忽略中止的 slow_probe(60 秒):
- 工具开始后 +25.2 秒(20 秒期限 + 5 秒宽限):条目
failed·Background agent tool "slow_probe" made no progress for 20000ms. - 子进程发送
qwen/control/session/runtime/recycle {reason: "unresponsive_agent"};36 毫秒后第二个 generation 启动;守护进程日志runtime recycle requested … deferring channel retirement until 1 active session(s) drain。 - 路由: 固定在旧 generation 上的会话 S1 的 prompt 仍发往旧 generation;新的
POST /session落到替代 generation。 - 仅记录: 父会话没有通知轮次,子 Agent 也没有后续请求。
- 工具结束并删除 S1 后,旧 generation 以
code=0退出,只剩一个 generation。
base 同一场景:始终只有一个 generation,Agent 在整个 60 秒内保持 running,随后正常完成并通知父会话。
真实 TUI 中的同两条路径
- 协作式 TIMEOUT: transcript 中出现
● Background agent "general-purpose: probe HOLD" failed.,父会话收到通知轮次,任务行显示✖ probe HOLD ▶ 30s。 - 升级(仅记录): 底栏变为
1 task done,但没有打印任何通知行 —— 交互式 TUI 会丢弃recordOnly通知(use-llm-stream.ts直接 return;已作为 R1-9 跟踪)。用户只能通过/tasks或下面的拦截得知发生了什么。 - 保留槽位拦截
/clear: 忽略中止的工具仍存活时,/clear被拒绝,提示… probe DISC — still stopping (failed 36.2s);工具的 OS 进程结束(90 秒)后/clear成功。也就是说,在 TUI 中保留的物理槽位确实保护了会话重置 —— 与 §7 守护进程的 detach 路径形成对比。
发现 / 供决策的证据
六、在真实守护进程上复现 R1-29 —— 一次成功的取消被静默改写。 在工具开始后 +22.0 秒(20 秒期限之后的 5 秒宽限期内)调用 POST /session/:id/tasks/:taskId/cancel,返回 200 {"cancelled":true,"status":"cancelled"},任务列表也显示 cancelled。到 +25 秒,升级把它改写为 failed(watchdog 错误)并请求 recycle,而父模型没有收到任何通知轮次 —— 既不知道取消,也不知道失败。
也就是说,API 告诉调用方的是一种终态,而 registry/sidecar/模型最终得到的是另一种(或者什么都没有)。无论 R1-29 / R6-5 最终怎么裁定,建议规则同时覆盖取消接口返回什么、以及父模型是否被告知。
七、保留的物理槽位并不能保住守护进程中的 Session —— detach 会回收它并杀掉仍在运行的工具。 升级后,子进程的 active-work holds 来自 listUnfinalizedBackgroundAgentIds()(running,或 cancelled 且未通知),因此即使设置了 retainsPhysicalSlot,failed + 已通知的条目也会被排除。实测:
- head: 升级后立即
POST /session/S1/detach(工具仍在运行)→ 大约 1 秒后,通知接收 hold 释放,Session 被关闭(日志closing session … (reason: last_client_detached),GET→ 404),draining generation 以code=0退出,slow_probe的 OS 进程在 60 秒前就消失了(没有写出结束记录)。 - base: Agent 运行中做同样的 detach,Session 保持(
activeWork:true),直到工具在 60.8 秒完成后才正常关闭。
这与 R6-6b 直接相关。在守护进程层面,保留的槽位其实已经通过 detach/close + generation 退出被释放了,这与 background-tasks.ts:920-934 的不变量相矛盾,而且对“慢但仍存活”的工具来说,这是相对 base 的破坏性差异。要么这就是预期的补救方式(那么不变量注释和设计文档应当写明),要么 collectActiveWorkHolds() 应当把保留槽位计入。
八、第一个 generation 仍在 draining 时的第二次 recycle —— 工作区能恢复,但第二次 recycle 被丢弃。 S1 升级后工作区迁移到 generation 2;随后 S2 中运行在 generation 2 上的 Agent 也升级,而 generation 1 仍在 draining(S1 的工具保持 150 秒):
- 守护进程日志
runtime recycling blocked recovery work; generations=…:draining…,…:draining…,子进程的 recycle 请求收到 JSON-RPC-32603 Internal error—— 而不是可重试的runtime_recycling形态。 - generation 2 被回滚为
active:新的POST /sessionS3、S4 都返回 200(没有卡在 503),并且都落到 generation 2 —— 也就是仍承载 S2 无响应 Agent 的那个 generation。 - generation 1 退出后,没有任何机制重试 recycle(
Session.#recordUnresponsiveAgentNotification只调用一次 ext-method,失败时只记 warning),因此 generation 2 继续承接新工作。
这回答了 6bc80c0 时 triage 提出的问题(工作区确实能恢复),但第二个无响应 Agent 所在的 generation 没有被 recycle。若不在本 PR 范围内,建议开 follow-up issue。
九、默认 provider 设置下,静默挂起的 provider 永远不会触发模型/控制期限。 与 §1 相同的场景,但使用默认的 generationConfig.timeout(120 秒),见 §1 图的下半部分。两个分支上请求都每约 120 秒被中止并重发(07:53:21 到 08:15:35 之间共 12 次,重试循环仍未放弃)。在最后一次状态采样 t=1106 秒(18.4 分钟)时,head 仍为 running,与 base 完全一样;我停掉两个守护进程时,距首次挂起已 22 分钟,其子 Agent 仍在重试。
与 §1 的唯一区别是 provider 超时,因此原因在重试路径:每次重试都会发出 MODEL_RETRY,onModelRetry → armModel(retryDelayMs) 会清掉定时器并重新开始一个全新的 15 分钟窗口(再加上延迟)。设计文档说重试延迟会延长期限,但实际上期限变成了“距离上一次重试 15 分钟”,而不是“15 分钟没有进展”。这样挂起的上游只受重试预算约束,而这里的重试预算并没有停下来。
这可能是现实中最常见的停滞形态,建议决定重试是否应当只把当前窗口延长 retryDelayMs,而不是重新开始计时。这与 R6-3 / R6-6a 有重叠。
本 head 上的测试
packages/core:agent-progress-watchdog.test.ts+background-tasks.test.ts—— 159 通过。packages/acp-bridge:bridge.test.ts—— 941 通过。93eef769a7上的 CI:23 通过 / 27 跳过(macOS/Windows 单测分片被跳过)。
Harness 说明
tools.discoveryCommand工具只有在QWEN_CODE_LEGACY_MCP_BLOCKING=1时才会注册:默认模式下Config.initialize()传入skipDiscovery: true,而discoverAllTools()是命令式发现的唯一调用方。这是 PR 之前就存在的行为(config.ts不在 diff 中);升级相关场景使用了这个逃生开关。- 压缩分支与 head 的差异只有上述两个字面量(已对修改后的文件执行
grep -n "_MS = "确认)。
|
@wenshao 谢谢这轮真实 daemon 验证。收到并逐项对齐,说明本轮巡检为什么不往这个 PR 里加代码、以及哪几项在等你裁定。 一、先确认这轮的基线变了你的验证跑在
所以本轮以你 08:20Z 这条为准:
即机制层面 head 已经对上,剩下的都是决策而不是实现。 二、§8 已按你的建议开成独立 issue#11767 —— 第二次 recycle 在第一个 generation 仍在 draining 时被丢弃,且没有任何重试。里面写清了两个可分离的半边( 三、§6 / §7 / §9 在等你裁定,本轮不动代码这三项都命中巡检的 human-gate 第①条(改并发原语语义),且这个 PR 已触发评审不收敛熔断——findings 分别在 R1(09-07T13:44Z)、R6(09-09T20:43Z)、R9(09-13T03:46Z)三轮被新 mint,所以本轮起对它停止加代码。你测出来的证据正好让这三个决策可以"凭数据定"而不是"凭读代码定",具体请你给个方向: §6 → 对应 R1-29( §7 → 对应 R6-6b(
§9 → 与 R6-3 / R6-6a 重叠 四、线程状态6 条 unresolved(R1-29、R6-2、R6-3、R6-6、R1-36、R9-1)全部保持 unresolved,不静默 resolve——§6/§7/§9 的裁定会直接决定 R1-29 / R6-2 / R6-3 / R6-6 的收口方向,R9-1 作者侧已在 04:55:59Z 给出"REAL,但在本轮 ≤3 文件、不新增跨层字段/传输、不改并发语义或产品行为的天花板内无解,escalate"的结论,并附了逐链读当前 head 源码的因果链( 本轮:不加代码、不 push、不 resolve 任何线程,只开了 #11767 和这条回复。 |
|
Round R6-1 is confirmed present at head
Head is internally consistent and deliberately unbounded: an approval wait suspends both the tool deadline and the model deadline, with no timeout. What conflicts is older review-guidance / test-plan text describing the approval behaviour as bounded. @wenshao's §3 measured precisely this path on the real TUI ( Reconciling them means deciding whether an approval wait should carry a bound at all, which is a timeout-policy decision. @doudouOUC's review 5177234081 says the same from the reviewer side: "The documented bounded approval behavior conflicts with older review guidance/test-plan text … I am not inventing another timeout policy here." Not picking a side; R6-1 stays unresolved. Queue status at this head, for the record. All 6 unresolved Criticals (R1-29, R6-2, R6-3, R6-6, R1-36, R9-1) plus R6-1 were re-verified against the live tree this round —
Deliberately not pushing code this round. Review 5189445584's "Mechanism health" paragraph states the round withheld its incremental anchor and the round it recovered to had none either, so the next review re-reads the whole diff. A commit here buys a full re-review of a +1456/-118 diff on a PR that minted new findings in R1, R6 and R9, and closes none of the 6: §6/§7/§9 need @wenshao's ruling (requested 09:20:35Z, no reply yet), and R1-36 needs a routing decision for workspace-scoped MCP mutations during a drain that no measurement has covered. §8 was filed as #11767. |

|
@qwen-code /triage |
|
Sandboxed verification: ❌ not passed — findings reported (agent verdict) - workflow run Ran the PR in an isolated, token-free container: A/B against the base build, mock-free harness assertions, targeted gates. Advisory evidence for human reviewers — not a review, an approval, or a CI check. Scripted assertions: 43 passed · 0 failed · 43 total Flakiness gate: ✅ 3 changed test file(s) x 5 identical rounds, no divergence 中文 — 判定:❌ 不通过 · 报告了发现(agent 判定)沙箱验证在隔离、无凭证的容器中执行了该 PR 的代码(与 base 构建 A/B 对照、无 mock harness 断言、定向门禁)。仅作为评审证据,不构成评审、批准或 CI 检查。 脚本断言:43 通过 · 0 失败 · 43 总计 抖动门:✅ 3 changed test file(s) x 5 identical rounds, no divergence Verification reportPR #11270 — deep verification (follow-up round)Verdict: Verified head OID: 中文摘要结论:
Previous-finding statusRe-measured at the new head, not diffed against the old report. The previous head
Scope chosenCentral claim — an ordinary background Agent turn whose model/control path stops producing events now aborts once at a fixed 15-minute deadline and settles as Secondary claims — (S1) each executing tool owns an independent 10-minute deadline; queued tools own none; renewal is per-tool. (S2) a run that ignores the cooperative abort escalates after a 5-second grace to one New probes scoped to the delta: the approval-park behaviour change, the Central claim and A/BBoth arms load the real compiled Cells as they printed:
Timer fidelity: Assertion totals: head 22/22, base 6/6, sibling sweep 6/6 × 2 labels, gate-liveness 3/3 → 43 pass, 0 fail ( Corrections to the PR descriptionCorrections to the description, not requests to change code — except where noted.
FindingsN1 — an approval nobody answers now leaves a background Agent with no deadline at any level, contradicting both design docs (Suggestion — behaviour changed in this delta)
Measured at real wall-clock deadlines ( node tmp/pr11270-verify-20260913-132919/harness-watchdog-ab.mjs \
--tree /__w/qwen-code/qwen-code --arm head --only approval-parkThis is a change in this delta, not a long-standing behaviour. The previous round measured the same cell shape aborting at 15 m with Why it matters. The consequence is the failure mode this PR exists to close: a background Agent that holds a concurrency slot forever with no terminal result. What this is not. I did not demonstrate an end-to-end wedge in a live CLI, and this may be a deliberate tradeoff — approvals are meant to wait for people, and the previous round's correction pushed toward exactly this. The defect I can prove is narrower and not a judgement call: the code contradicts the author's own stated design in both languages. Either the docs should say that approval waits suspend the model deadline as well, or Suggested minimal doc fix (if the behaviour is intended)In with a sentence that names both suspensions, and mirror it in the I did not measure a code fix for this one: the behaviour is pinned by the PR's own test, so changing it means rewriting that test — the author's call, exactly as for F1. N2 — F1's unnamed sibling: the nested
|
| cell | scenario | result |
|---|---|---|
S4a |
top-level external-input wait, isWaitingForExternalInput() → false |
model deadline fires (phase=model/control) — the top-level path does cross-check the Monitor registry |
S4b |
top-level wait, cross-check → true | correctly suspended |
S2 |
nested external-input park, cross-check → false | no deadline at 3× the model deadline (F1) |
S1 |
nested approval park, nothing pending anywhere | no deadline at 3× the model deadline (this finding) |
S3 |
positive control: same park, then one clearing chunk, then silence | tool deadline fires — so S1/S2's silence is a real absence, not a dead harness |
Bound: the flag is not attacker-controlled — it is the child's honest report, and any subsequent task_execution chunk clears it (S3 proves the clear path works). The exposure is a stale flag: a nested child that stops emitting chunks after reporting a park leaves the parent with no deadline at any level, and the parent's watchdog is the only one, since a nested child runs inside the parent's turn.
N3 — parkedOnInput is dead code; the state='approval' beside it is load-bearing but unpinned (Suggestion)
The nested-input park sets two guards: tool.state = 'approval' and tool.parkedOnInput = true. armModel blocks on either. Census: parkedOnInput has exactly one read site (agent-progress-watchdog.ts:108), one write (:195), three deletes, one declaration, and zero references anywhere else in packages/.
| row | mutation | result | classification |
|---|---|---|---|
M6d |
drop the parkedOnInput clause from armModel |
SURVIVED 7/7 | state==='approval' already covers it |
M6e |
the nested park never sets parkedOnInput |
SURVIVED 7/7 | the write has no reader that matters |
M6g |
delete all 6 parkedOnInput sites (decl + write + read clause + 3 deletes) |
SURVIVED 7/7, residualParkedOnInputRefs=0 |
dead code — the field can go entirely |
M6a |
nested park sets parkedOnInput without state='approval' |
SURVIVED 7/7 | the unread clause covers it |
M6f |
M6d + M6a together (both guards gone) |
SURVIVED 7/7 | the stale 'executing' state covers it on the shapes the tests use |
S5 |
the shape no test uses: park is the first progress event, then a sibling TOOL_RESULT calls armModel |
head: no abort · M6f mutant: aborts phase=model/control |
state='approval' is load-bearing and unpinned |
06-dead-field-parkedoninput.png, 03-sweep-nested-parks-have-no-deadline.png. The two rows together are the point: the field is deletable, but the state assignment beside it is not — removing it changes behaviour on a reachable shape (a nested child whose first reported progress is already a park, then any sibling tool finishing) that no fixture exercises. So this is one line to delete and one fixture to write, not "remove the guards".
Note this flips the previous round's M6a, which was KILLED. The likely cause is the delta's addition of tool.state = 'approval' to that branch, which made the separate clause redundant — an inference from the two rounds' measurements, not a diff, because the previous head is unreachable.
N4 — the runtime-generations design doc omits the rollback the delta added (Nit)
docs/design/background-agent-runtime-generations.md:13 states the failure mode as permanent: "If both are draining, admission fails with 503 runtime_recycling until one exits." The code no longer behaves that way on the recycle path — requestRuntimeRecycleForSession catches BridgeRuntimeRecyclingError from its own replacement spawn, restores owner.state = 'active', clears retireWhenSessionsDrain only if this recycle set it (the wasReapPending capture is correct and avoids erasing another condemnor's flag), and rethrows. B2 (dropping that rollback) is KILLED 1/941, so a test pins it.
Two consequences a reviewer is agreeing to that the doc does not state:
- Fresh work concurrently entering during the
await retireChannelAfterSessionsDrain→await ensureChannel('recovery')window sees noactivegeneration and gets a transient503 runtime_recycling(retryable, loud on stderr). Bounded, and an improvement on the previous round's F5. - The recycle is effectively single-shot per workspace once a generation is pinned open:
state='draining'has exactly one writer (bridge.ts:3807) and the pinned generation never drains while its abort-ignoring session is attached, soworkOwningGenerations.length >= 2holds permanently and every later recycle rolls back instead of replacing. The only signal is adebugLogger.warninSession.#recordUnresponsiveAgentNotification'sfinally. This is the residue of F5; it is narrower than what the doc describes, but it is not documented either.
F1 — a nested external-input park suspends every deadline without the Monitor cross-check (Suggestion, stands)
Re-measured, unchanged. NP-1/NP-2 at real timers: with isWaitingForExternalInput() wired to return false, one TOOL_PROGRESS{waitingForExternalInput:true} leaves the entry un-aborted and running at 16 minutes. M10 (gating the nested park on the cross-check) still turns 2 of the PR's own 7 tests red — keeps a nested external-input wait free of any deadline until progress resumes and keeps the model deadline suspended while a nested input wait outlives sibling tools, both AssertionError: expected 'tool' to be undefined. Deliberate and pinned, so reported as a design question, not a defect. See N2 for the sibling and N3 for what is and is not dead in that branch.
F2 — the interactive TUI drops the unresponsive-Agent notification entirely (Suggestion, stands)
packages/cli/src/ui/hooks/use-llm-stream.ts:6313-6314 is the whole handler:
registry.setNotificationCallback((displayText, modelText, meta) => {
  if (meta?.recordOnly) return;
The other two consumers do record it — Session.ts:9975 routes to #recordUnresponsiveAgentNotification (persist, display, end_turn, then the recycle ext-method in finally), and nonInteractiveCli.ts:1535-1536 pushes the item with recordOnly and still emits it to the SDK, filtering it only out of the model batch at :2809. So the interactive TUI remains the one surface where a background Agent killed for being unresponsive produces no proactive signal, while docs/design/background-agent-runtime-generations.md says the notification "is recorded and displayed". Static (code-path) evidence; I did not drive the React hook.
F3 — remaining unpinned guards (Suggestion, narrowed)
The delta closed the two rows the previous round said to act on, plus more. Full matrix at the new head (04-mutation-matrix-core-rows.png, 05-mutation-bridge-rows-all-killed.png):
| row | mutation | prev | now | classification |
|---|---|---|---|---|
M0 |
none (green control) | 6 passed | 7 passed | suite green |
M8 |
positive control: tool deadline 10 m → 5 m | KILLED 1/6 | KILLED 1/7 | the harness can make this file red |
M2 |
drop the host-suspend drift guard | SURVIVED | KILLED 1/7 | now pinned by the new retry-extension test |
M9 |
drift re-arm closure drops the granted extension | new | KILLED 1/7 | the () => armModel(retryDelayMs) comment is pinned |
M10 |
F1 candidate fix | KILLED 2/6 | KILLED 2/7 | F1 deliberate |
V1 |
failUnresponsive drops retainsPhysicalSlot = true |
KILLED 1/150 | KILLED 2/152 | non-vacuous |
V2 |
drop the cancelled-status acceptance |
new | KILLED 2/152 | the delta's cancel-race path is pinned |
V5 |
escalation notification loses recordOnly |
new | KILLED 1/152 | pinned |
G1 |
hasRunningTasks() drops the retained-slot clause |
SURVIVED 150/150 | KILLED 1/152 | fixed — this was the row to act on |
B1 |
recycle never condemns the owner generation | no liveness proof | KILLED 3/941 | bridge gate is live |
B2 |
drop the rollback-to-active | new | KILLED 1/941 | N4's rollback is pinned |
B3 |
post-newSession guard reverts to two-state isDying |
new | KILLED 1/941 | the three-state test is pinned |
B4 |
restore-path guard reverts to two-state isDying |
new | KILLED 1/941 | ditto |
G2 |
describeBlockingBackgroundWork() drops the retained-slot branch |
SURVIVED 26/26 | SURVIVED 26/26 | coverage gap — the — still stopping label is deletable |
M1 |
never arm the 5 s escalation timer | SURVIVED | SURVIVED 7/7 | coverage gap — the behaviour is real on the live path: the escalation had fired by MS-6 (+960 s) and MS-3 confirms exactly one recordOnly notification |
M3 |
drop the 6-hour retry-extension clamp | SURVIVED | SURVIVED 7/7 | coverage gap — the new test uses retryDelayMs = 1 h, under the clamp, so Math.min is never decisive |
M4 |
queued tool starts its deadline at TOOL_CALL |
SURVIVED | SURVIVED 7/7 | coverage gap (behaviour real: QT-1) |
M5 |
remove timer.unref() |
SURVIVED | SURVIVED 7/7 | coverage gap |
M7 |
dispose() no longer clears tool timers |
SURVIVED | SURVIVED 7/7 | coverage gap |
V3 |
getRunningBackgroundCount stops counting retained slots |
new | SURVIVED 152/152 | coverage gap — but MS-5+MS-8 prove the behaviour real |
V4 |
pruneTerminalEntries may evict a retained-slot entry |
new | SURVIVED 152/152 | coverage gap |
M6a/b/c/d/e/f/g |
the parkedOnInput cluster |
mixed | SURVIVED | see N3 |
G2 is the one I would still act on: backgroundWorkUtils.test.ts is proven live (planted violation → 1 failed | 25 passed, restored byte-identical — 07-gate-liveness-backgroundworkutils.png), so its green result is meaningful and the retained-slot branch it added is genuinely unpinned. That branch is what renders — still stopping in every blocking refusal a user sees.
Every mutation was applied to source, verified on disk, run, and restored byte-identically; git status --porcelain is clean and git diff HEAD over all four mutated files is empty.
F4 — isChannelLive()'s doc now describes a function that does not exist (Nit, worsened)
The delta expanded the comment rather than correcting it. bridgeTypes.ts:2530-2536 now claims isChannelLive() reports a channel that is "active and can accept fresh workspace work … while a draining generation still owns existing sessions but cannot accept new work" — describing admissibleChannelInfo()'s semantics. The implementation forwards liveChannelInfo() (bridge.ts:9736-9738 → :6318-6319), which returns any non-dying channel, so a draining generation reports live.
Observable effect, unchanged and wide: channelLive/acpChannelLive feed workspace readiness (workspace-service/index.ts:489-553, including finish({ ready: true, channelLive: true })), health (routes/health.ts:92), daemon status (daemon-status.ts:664-716, :1331), env snapshots and provider status — all of which will report a live, ready channel while ensureChannel refuses fresh work with 503 runtime_recycling. The base comment ("spawned and not dying") matched the behaviour; the PR removed it.
Not covered
- Per-commit attribution. Depth-2 checkout: only the merge commit,
HEAD^1andHEAD^2exist.git rev-list HEAD^1..HEAD^2returns 1 while the snapshot lists 36 commits; the previous head6bc80c0dand basecb94a33fare both unreachable, so the delta could be characterised only by re-measuring, never by diffing the two heads. - Test-plan step 5 (restored Agent, resident continuation). Verified statically only:
attachAgentProgressWatchdoghas exactly two production call sites —agent.ts:3881insiderunBackgroundTurnandbackground-agent-resume.ts:1414— and the residentcontinue(agent.ts:3984) routes throughrunBackgroundTurn, so both claimed paths attach it with the same four arguments and the same.finally()disposal. Not driven at runtime. The foreground/workflow exclusion was verified only by the absence of an attach site. - Test-plan step 6's daemon half. Slot retention, the single
recordOnlynotification and idempotency were measured at the registry level; generation draining, theqwen/control/session/runtime/recycleroute'sownsSession/reasonvalidation, the503mapping indispatch.ts:918/error-response.ts:383, andSession.#recordUnresponsiveAgentNotification's ext-method round trip were not driven — no daemon harness.B1-B4are source mutations againstbridge.test.ts, not a live daemon. - The cancel/escalation race was not driven at real wall-clock.
V2proves the two new tests pin thecancelledacceptance, but I did not race a realCANCEL_GRACE_MStimer against a real drift-guarded escalation timer; the comment's ordering argument is verified by reading and by unit test only. - No end-to-end CLI run. The A/B drove the compiled watchdog plus the real registry against a synthetic event stream. It did not execute
AgentToolInvocation,AgentCore's reasoning loop, or a real model transport. Theabort → AgentTerminateMode.TIMEOUTmapping inagent-core.ts/agent-headless.ts/agent.tsand the "never enters the workflow retry loop" claim are verified by reading. This reproduces the shape of the wedge (an event stream that stops), not a model-side stall that produces one. - The 6-hour retry-extension clamp (
MAX_RETRY_DEADLINE_EXTENSION_MS): no cell drove it andM3survived — the new test's 1-hour delay is under the clamp, soMath.minnever decides anything. - The drift-rearm path never executed at real deadlines. Measured probe lateness (~0.6 s) stayed under the 1 s tolerance, so I have no real-timer evidence about host-suspend behaviour. It is pinned only by the fake-timer test (
M2killed). run1of the head arm is superseded, not counted. ItsMS-5/MS-7probes were mis-ordered (the release fired before the capacity assertions) and itsAP-2encoded the previous head's behaviour; both were my harness defects, not PR outcomes.logs/ab-head.logis retained for traceability;run2is authoritative and is the only head run folded intoassertions.json. The base arm ran once and is unaffected.- typecheck, lint, format, repo-wide test suite — not run. Gates were limited to the affected files.
Targeted gates
| gate | command | result | prev round |
|---|---|---|---|
| core (changed files) | cd packages/core && npx vitest run src/agents/runtime/agent-progress-watchdog.test.ts src/agents/background-tasks.test.ts src/agents/runtime/agent-core.test.ts src/agents/runtime/agent-headless.test.ts src/agents/background-agent-resume.test.ts src/tools/agent/agent.test.ts |
6 files, 647 passed | 605 |
| acp-bridge | cd packages/acp-bridge && npx vitest run src/bridge.test.ts src/bridgeClient.test.ts |
2 files, 1075 passed (bridge.test.ts 941) |
1052 |
| cli (changed files) | cd packages/cli && npx vitest run src/ui/utils/backgroundWorkUtils.test.ts src/nonInteractiveCli.test.ts |
2 files, 192 passed, 1 skipped | 188 + 1 skipped |
Gate liveness, proven per file: agent-progress-watchdog.test.ts (M8 killed 1/7), background-tasks.test.ts (V1/V2/V5/G1 killed), bridge.test.ts (B1-B4 killed — new this round; the previous round had no liveness proof here), backgroundWorkUtils.test.ts (planted label violation → 1 failed | 25 passed, restored byte-identical). agent-core/agent-headless/background-agent-resume/agent/bridgeClient/nonInteractiveCli are cited as executed-and-green only — no planted violation, so no liveness claim.
Methodology
CI merge-ref checkout of refs/pull/11270/merge in node:22-bookworm, 64 cores, load ≈ 31 at start; npm ci and npm run build were already complete at HEAD. The base arm is a scratch worktree at HEAD^1 under tmp/base-tree, with packages/{core,cli,acp-bridge,web-templates,sdk-typescript,vscode-ide-companion}/node_modules and the root node_modules symlinked to the head tree's — a clean control because git diff --name-only HEAD^1..HEAD shows this PR touches no package.json, package-lock.json or pnpm-lock.yaml. Base core was rebuilt in place (npm run build -w packages/core, exit 0). Because node_modules/@qwen-code/qwen-code-core resolves into the head tree (readlink -f → /__w/qwen-code/qwen-code/packages/core), a naive base harness would have loaded head code and passed both cells; each arm therefore imports its compiled modules by absolute path inside its own worktree and asserts arm identity from the loaded code (ARM-IDENTITY-*, both arms). The base build has no agent-progress-watchdog.js at all, which is itself the identity proof.
Four harnesses, all rerunnable as-is from the artifact directory:
harness-watchdog-ab.mjs— the real-timer A/B. Real compiled watchdog, realAgentEventEmitter, realAbortController, realBackgroundTaskRegistry(capacity pinned to 1 so occupancy is observable through the publiccanStartBackgroundAgent()), wired exactly asagent.ts:3881wires it. Six head cells ran concurrently in one process over a 16 m 45 s window, the base control in a second process over 17 m 30 s, each with a ref'd 30 s heartbeat because the watchdog's own timers areunref()'d.--drycompresses the clock 300× and records nothing; both arms were dry-validated before the real runs.build-scaled.mjs+harness-sibling-sweep.mjs— the sibling sweep on a ÷60 copy of the shippeddistwatchdog. The builder asserts that exactly 4 lines changed (3 constants + the import made absolute) and refuses to emit otherwise, so the branch logic under test is byte-identical to production; the scaled build is used only for qualitative "is there any deadline at all" questions, and every numeric deadline claim comes from the real-timer A/B.mutation-matrix.mjs,dead-field-and-combo.mjs— single-point source mutations with an--check-anchorspre-flight (uniqueness asserted per anchor, which caught two bad anchors before any run), on-disk verification, and sha256-checked byte-identical restore.gate-liveness-bwu.mjs— the planted-violation probe for the one gate whose mutation survived.
Raw per-cell logs, per-run JSON, and the assertion breakdown are in logs/; finalize.mjs recomputes assertions.json from them. Image evidence was captured with scripts/verify-capture.mjs as each run printed.
Flakiness gate log
rounds=5 files=3 skipped=0
file packages/acp-bridge/src/bridge.test.ts: (cd packages/acp-bridge) npx --no-install vitest run ./src/bridge.test.ts
file packages/core/src/agents/background-tasks.test.ts: (cd packages/core) npx --no-install vitest run ./src/agents/background-tasks.test.ts
file packages/core/src/agents/runtime/agent-progress-watchdog.test.ts: (cd packages/core) npx --no-install vitest run ./src/agents/runtime/agent-progress-watchdog.test.ts


per-file results (P=pass F=fail I=infra-exit, one letter per run):
  packages/acp-bridge/src/bridge.test.ts: PPPPP
  packages/core/src/agents/background-tasks.test.ts: PPPPP
  packages/core/src/agents/runtime/agent-progress-watchdog.test.ts: PPPPP

verdict: pass
summary: 3 changed test file(s) x 5 identical rounds, no divergence

--- per-invocation detail (full copy in the artifact) ---
round 1 · packages/acp-bridge/src/bridge.test.ts: P (exit 0)
round 1 · packages/core/src/agents/background-tasks.test.ts: P (exit 0)
round 1 · packages/core/src/agents/runtime/agent-progress-watchdog.test.ts: P (exit 0)
round 2 · packages/acp-bridge/src/bridge.test.ts: P (exit 0)
round 2 · packages/core/src/agents/background-tasks.test.ts: P (exit 0)
round 2 · packages/core/src/agents/runtime/agent-progress-watchdog.test.ts: P (exit 0)
round 3 · packages/acp-bridge/src/bridge.test.ts: P (exit 0)
round 3 · packages/core/src/agents/background-tasks.test.ts: P (exit 0)
round 3 · packages/core/src/agents/runtime/agent-progress-watchdog.test.ts: P (exit 0)
round 4 · packages/acp-bridge/src/bridge.test.ts: P (exit 0)
round 4 · packages/core/src/agents/background-tasks.test.ts: P (exit 0)
round 4 · packages/core/src/agents/runtime/agent-progress-watchdog.test.ts: P (exit 0)
round 5 · packages/acp-bridge/src/bridge.test.ts: P (exit 0)
round 5 · packages/core/src/agents/background-tasks.test.ts: P (exit 0)
round 5 · packages/core/src/agents/runtime/agent-progress-watchdog.test.ts: P (exit 0)
Evidence images
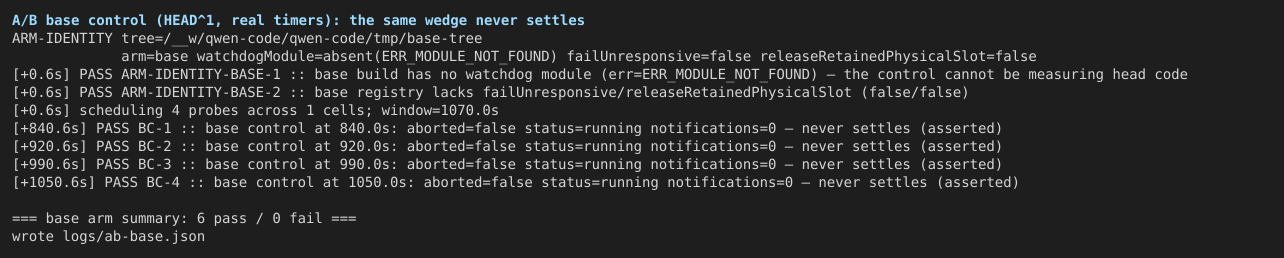
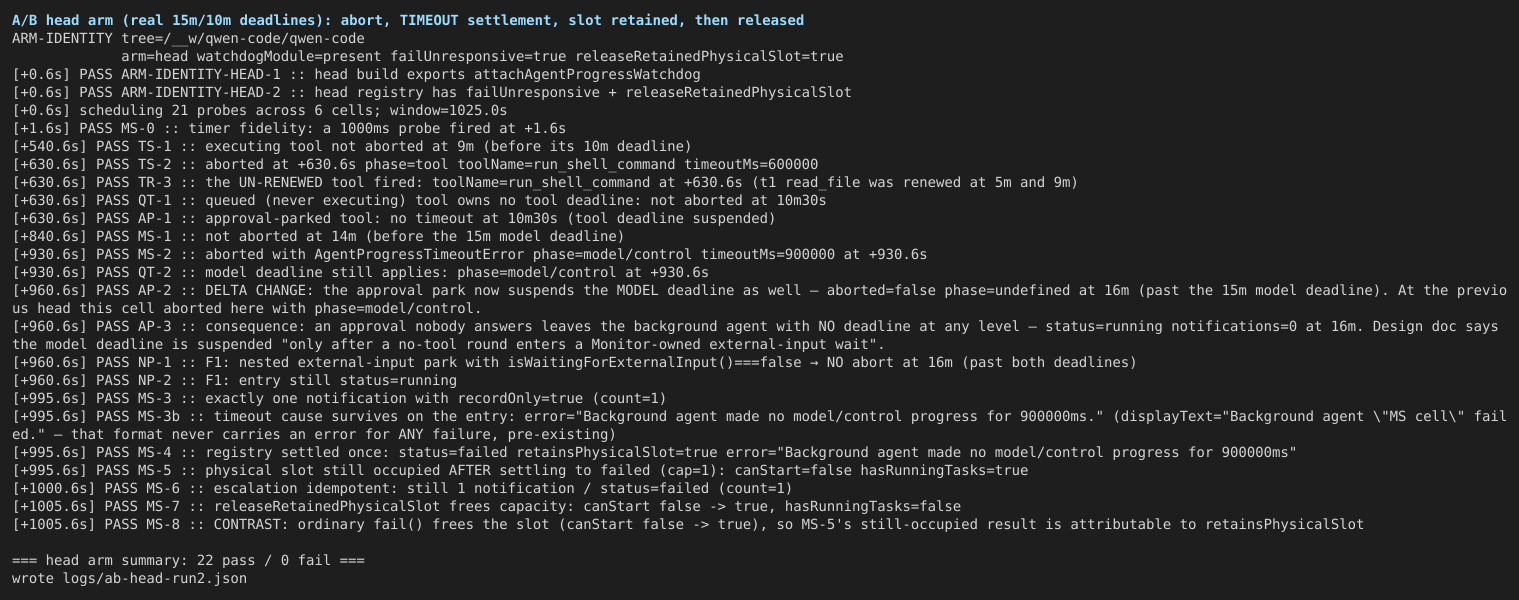
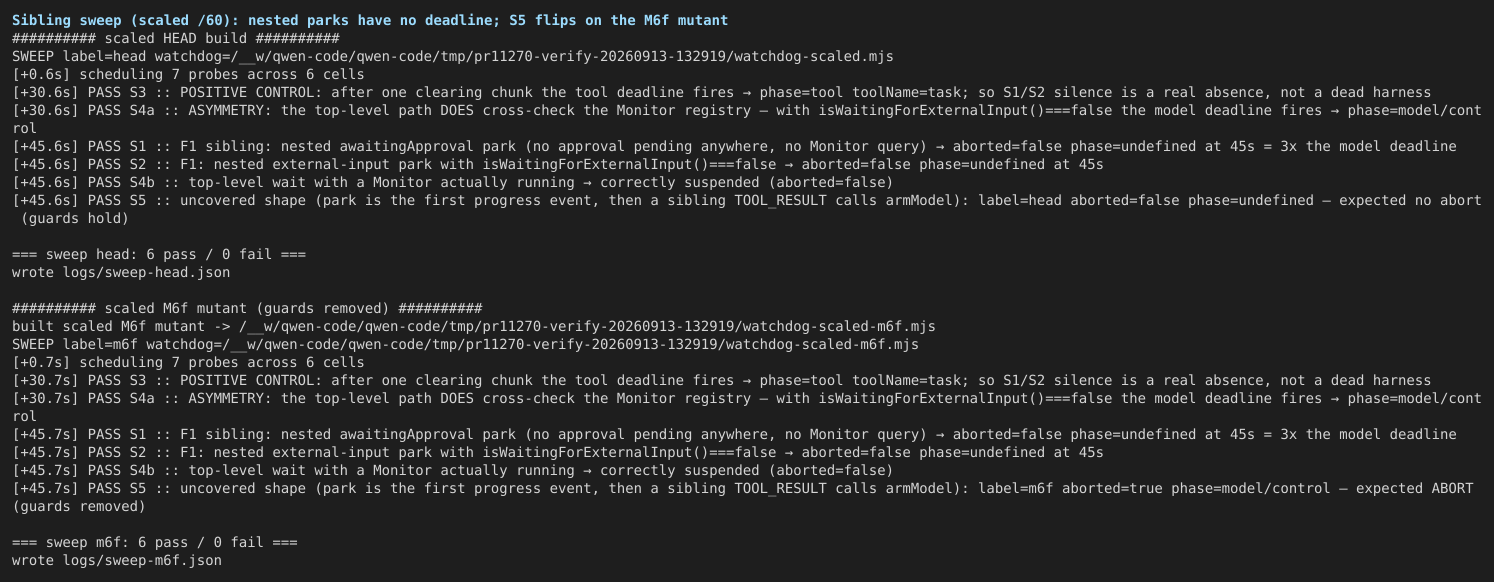
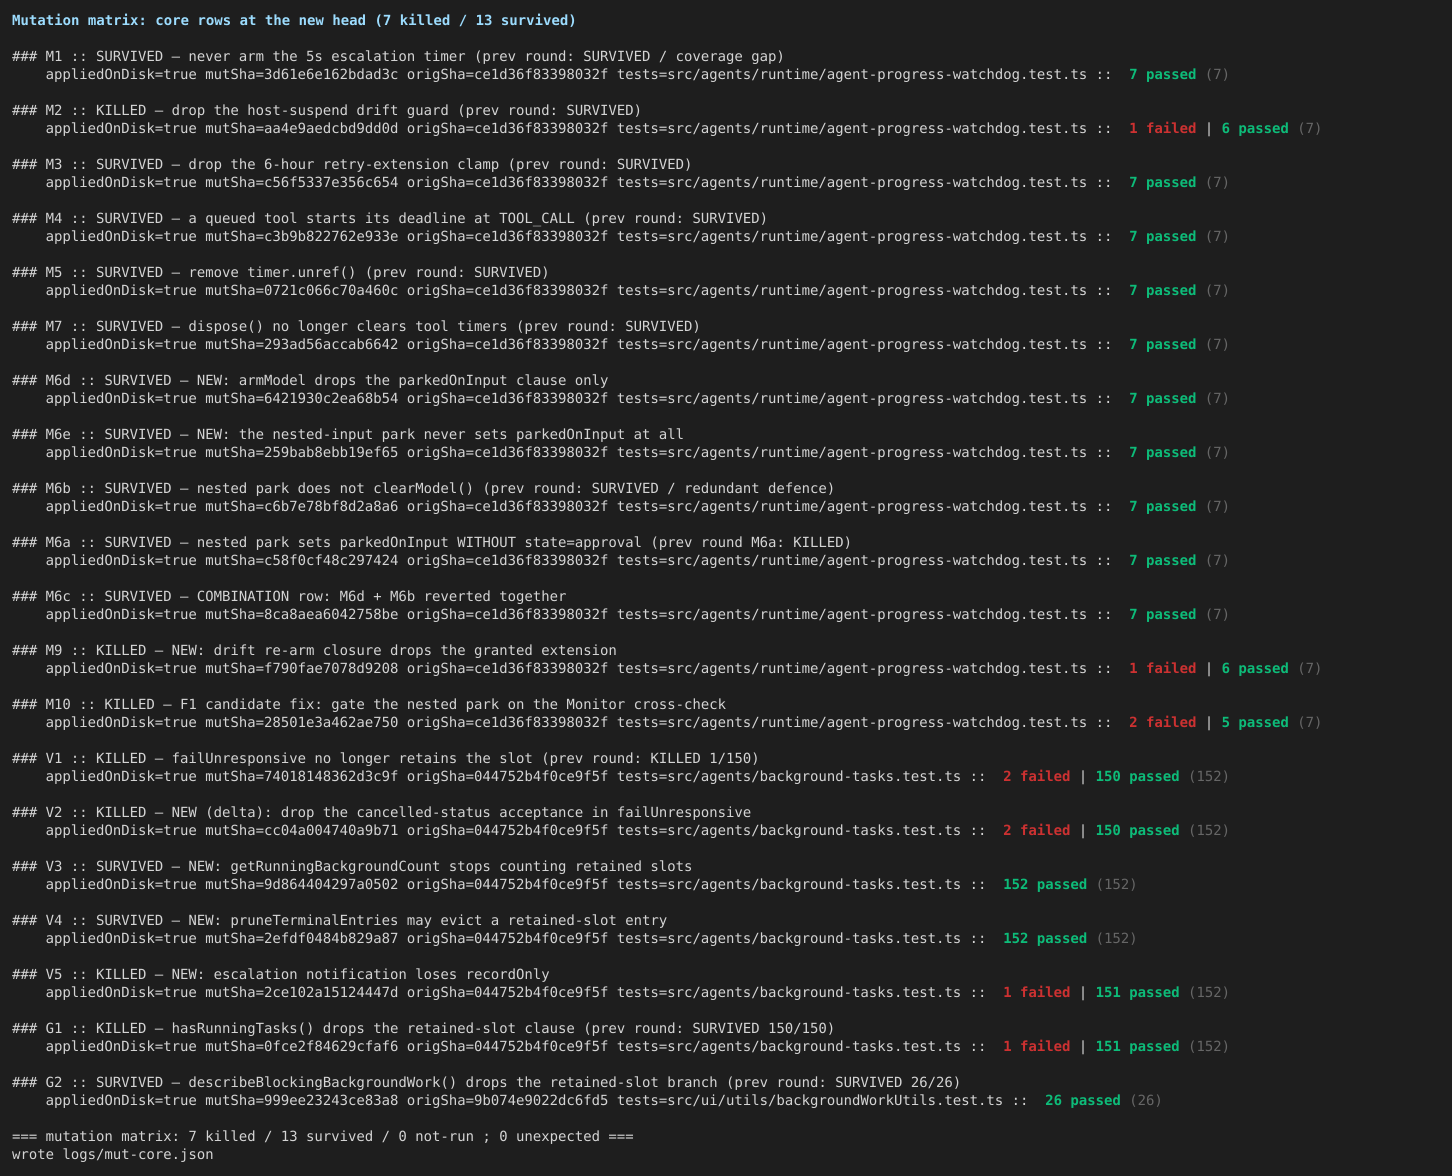
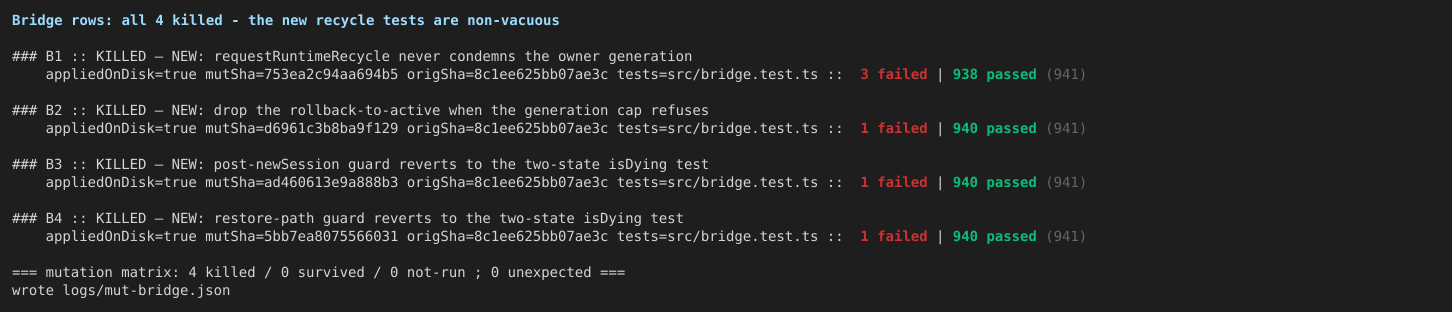
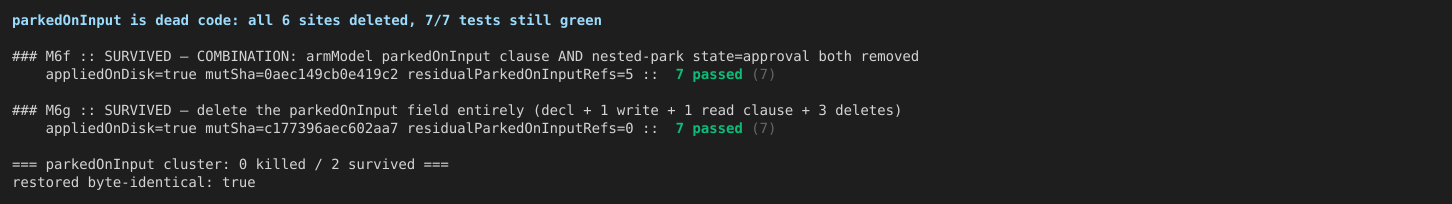

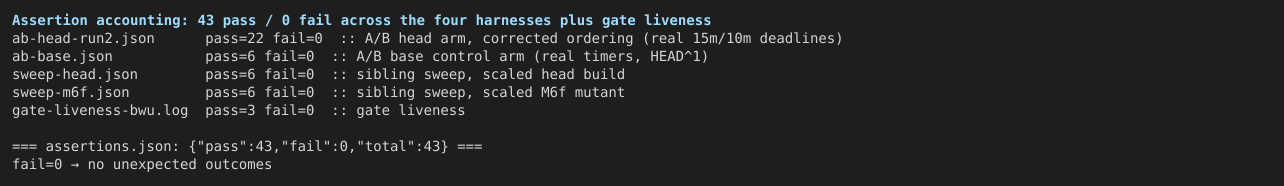
Harness scripts and raw logs are in the workflow run artifacts (7-day retention).
— Qwen Code · sandboxed verification
|
Triage re-run completed without a new review. The bot already has a review of its own on 机器人在 The stage comments above were updated with the latest result. View workflow run. 上方各阶段评论已更新为最新结果。查看工作流运行。 |
巡检轮
|
Conflicts resolved by keeping both sides:
- bridge.ts / bridgeClient.ts: main's background-turn-start callback and
  this PR's owner-scoped runtime recycle callback are two distinct trailing
  BridgeClient constructor params/extMethod branches; keep both.
- cli Session.ts: union of recordOnly and turn/admissionRetries fields.

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>
Patrol-Run: qwen-pr-conflict/jmu1w4eyl5c
Merging origin/main into this branch took main's two-argument
#emitBackgroundNotificationEndTurn signature, but the record-only call site
this PR adds still passed only the reason. `tsc --build` therefore failed with
TS2554 in Session.ts, aborting every job that builds the CLI.

A record-only notification displays a terminal notification without running a
model turn, so there is no background turn to close. Leaving turnId unset
keeps the payload the bridge settles as a bare
`background_notification_turn_complete` instead of naming a turn that never
started.

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>
Patrol-Run: qwen-pr-conflict/jmu1y9kob5g
|
Round The head moved from All six unresolved
Verdicts therefore do not move: all six findings remain REAL and all six remain decisions this PR cannot settle by itself. The decisions owed are unchanged — (a) who owns the terminal record when One new administrative fact: @wenshao's APPROVED review at No code change this round. |
Resolves the CONFLICTING merge state so the PR can be evaluated against current main.

packages/cli/src/acp-integration/session/Session.ts: comment-only conflict in
#emitBackgroundNotificationEndTurn's parameter list. Main independently made
`turnId` optional and switched the payload to `...(turnId ? { turnId } : {})`;
this branch added the explanatory comment for the same record-only path. Kept
main's body and this branch's comment - no behavioural change on either side.

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>
Patrol-Run: qwen-pr-closeout/jmu2ep50u63
|
Resolution-integrity audit at head Counting resolved threads misleads here: the bot re-posts the same finding id every round ("Still stands at
I re-verified one of the 15 against this head rather than assume, and it is substantively addressed. Corroborating signal, stated as inference and not as proof: the bot re-files every finding it still considers open — the 6 parked ones were re-posted on 09-07, 09-09, 09-11 and 09-13. All 15 of these stopped being re-reported after the 09-09 round, once heads moved past Not re-opening any of them, on that evidence. What is missing is the audit trail, not the fix — but it is worth knowing before a merge decision that 11 of the 15 sit in Separately: head moved |
Picks up #11933, which aligned packages/cli/src/serve/workspace-skills-status.test.ts with the qualified Skill identities the provider emits. This branch never touched that file, so the 13 Test-lane failures were the stale expectations from its older base, not a regression here.

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>

Patrol-Run: qwen-pr-conflict/jmu2luc9n6d
qwen-code-ci-bot
left a comment
qwen-code-ci-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed.
19 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- isChannelLive() doc/impl mismatch at packages/acp-bridge/src/bridgeTypes.ts:2590 — already reported (round-3 deferral record, re-listed in review 5189445584)
- recordOnly dropped in the interactive TUI at packages/cli/src/ui/hooks/use-llm-stream.ts:6314 — already reported as R1-9
- requestRuntimeRecycle? has no production caller at packages/acp-bridge/src/bridgeTypes.ts:2609 — already reported as R1-11
- sessionRuntimeRecycle ext-method route untested at packages/acp-bridge/src/bridgeClient.ts:1455 — already reported as R1-11
- wasReapPending rollback branch untested at packages/acp-bridge/src/bridge.test.ts:33089 — already reported (round-8 deferral record)
- isDying write-only-true shim at packages/acp-bridge/src/bridge.ts:1105 — already reported (round-8 deferral record)
- orphan child-side session on both widened post-await re-checks at packages/acp-bridge/src/bridge.ts:5790 and :8934 — already reported (round-9 deferral, bridge.ts:5711)
- onRetry -> MODEL_RETRY chain and the six-hour clamp untested at packages/core/src/agents/runtime/agent-core.ts:1095 — already reported (missing-test aggregate, round-3 review 5142185428; round-9 deferral watchdog.ts:114)
- resume-path retainsPhysicalSlot guards untested at packages/core/src/agents/background-agent-resume.ts:1300 — already reported (missing-test aggregate, round-3 review 5142185428)
- settled:true TOOL_PROGRESS re-emitted per chunk at packages/core/src/agents/runtime/agent-core.ts:2188 — already reported (round-8 deferral record)
- agent-core producer-side watchdog emissions untested at packages/core/src/agents/runtime/agent-core.ts:2095 — already reported (missing-test aggregate, round-3 review 5142185428)
- escalation onUnresponsive asserted nowhere at packages/core/src/agents/runtime/agent-progress-watchdog.test.ts:65 — already reported (missing-test aggregate, round-3 review 5142185428)
- settled branch of the watchdog untested at packages/core/src/agents/runtime/agent-progress-watchdog.test.ts:44 — already reported (missing-test aggregate, round-3 review 5142185428)
- model-activity renewal untested at packages/core/src/agents/runtime/agent-progress-watchdog.test.ts:74 — already reported (missing-test aggregate, round-3 review 5142185428)
- recordOnly consumers untested at packages/cli/src/acp-integration/session/Session.ts:10807 — already reported (missing-test aggregate, round-3 review 5142185428)
- runtime_recycling 503 mappings untested at packages/cli/src/serve/acp-http/dispatch.ts:936 — already reported (missing-test aggregate, round-3 review 5142185428)
- retained-slot lifecycle untested at packages/core/src/agents/background-tasks.ts:968 — already reported (missing-test aggregate, round-3 review 5142185428)
- AgentProgressTimeoutError -> TIMEOUT mapping untested at every layer at packages/core/src/agents/runtime/agent-core.ts:1047 — already reported (missing-test aggregate, round-3 review 5142185428)
- watchdog suite leaves nine further behaviours unpinned at packages/core/src/agents/runtime/agent-progress-watchdog.test.ts:31 — already reported (missing-test aggregate, round-3 review 5142185428)
Not reviewed: build-and-test — Integration Tests (CLI, No Sandbox) was skipped in CI and its suite did not run locally.
Not explored to full depth (tool budget reached): "agent reverse-audit (round 1)": I did not establish that channelInfo === undefined with two non-dying draining generations is reachable outside the interleaving I constructed from bridge.ts:…; "agent reverse-audit (round 1)": I did not walk the ensureChannel('recovery') spawn body (bridge.ts:4715-5360) beyond the cap check and the channelInfo = info assignment, so side effects of…; "agent reverse-audit (round 1)": I did not verify that recordNotificationStrict is safe to call from #recordUnresponsiveAgentNotification outside runExclusiveAutomaticHistoryMutation (Ses…; chunk 4: did not execute the two new background-tasks.test.ts tests — packages/core/dist is absent in this worktree, the vitest globalSetup guard refuses to run wi…; "agent reverse-audit (round 1)": did not establish *why* the guardrail test's fake factory needed the exited change at all — that needs the test run with the change reverted against the pre-P…, and 1 more.
Not reviewed: reverse audit — stopped before round 4 by the review time budget.
Deferred under the convergence posture (round 10, not a blocker) — recorded, not requested in this round; 4 Critical(s) among them are deferred by their axes — fails-closed on new surface, where no wrong result is certified and the merge base had neither the surface nor the defect — and remain follow-up work recorded in the findings artifact:
packages/core/src/agents/background-tasks.ts:1522 — [review] Critical [fails-closed] [new-surface] a retained physical slot has no user-reachable release outside the ACP daemon, so in a plain CLI session one wedged tool blocks /clear, /new,…packages/acp-bridge/src/bridge.ts:5797 — [review] Critical [fails-closed] [new-surface] the widened state !== 'active' re-checks reject a racing fresh spawn/restore with an error class no dispatcher maps, so a self-healing drain window reac…packages/core/src/tools/agent/agent.ts:1704 — [review] Critical [fails-closed] [new-surface] the awaitingApproval park flag is never cleared when the approval is answered through the dialog's raw respond route, so a nested call that then ha…packages/cli/src/acp-integration/session/Session.ts:10526 — [review] Critical [fails-closed] [new-surface] the recycle request is an unbounded await placed before the release of the activeNotificationAcceptances hold, so a request that neve…docs/design/background-agent-runtime-generations.md:13 — [review] neither language version documents the recycle rollback decision (a cap-refused recycle rejects and restores its target to active)packages/core/src/agents/runtime/agent-progress-watchdog.ts:117 — [review] the model-phase timeout error reports the base 15-minute constant after a backoff extension, so the operator-visible text understates the waitpackages/acp-bridge/src/bridge.ts:3873 — [review] the recycle rollback is scoped to the cap error only, so any other recovery-spawn failure leaves the owner condemned with no replacementpackages/acp-bridge/src/bridge.ts:9859 — [review] per-bridge resource accounting still describes one child although two live children are now a designed steady state, so runtime.memory under-reports during a drainpackages/cli/src/ui/utils/backgroundWorkUtils.ts:108 — [review] the '— still stopping' marker is concatenated inside the label field and then width-capped at 80 cells, so for wide labels the marker is what gets clippedpackages/core/src/agents/background-tasks.ts:955 — [review] failUnresponsive's sidecar write is the only terminal writer that ignores entry.persistedCancellationStatus, overwriting a deliberately persisted 'running' recovery marker with 'fa…packages/core/src/agents/background-tasks.ts:956 — [review] failUnresponsive patches the sidecar without the terminal summary every sibling write includes, and being terminal-by-design it can never be written afterwardspackages/core/src/agents/runtime/agent-headless.ts:404 — [review] the new progress-timeout arm returns before debugLogger.error and the ERROR emit, so an exception racing a watchdog abort is discarded with no trace at any layerpackages/acp-bridge/src/bridge.test.ts:29427 — [review] the new fake-channel comment states the generation cap's accounting backwards (a generation pending reap does not occupy a cap slot)packages/acp-bridge/src/bridge.ts:3096 (+3 locations) — [review] three comments in code this diff changed still describe the isDying predicate it replaceddocs/design/background-agent-runtime-generations.md:11 — [review] neither language version documents the in-flight rejection decision (fresh work already inside newSession/session/load is rejected, not migrated)packages/cli/src/acp-integration/session/Session.ts:10807 — [review] the record-only branch is drained behind assertCanStartTurn(), so a session that cannot start a model turn also loses the record-only displaypackages/core/src/agents/background-tasks.ts:1784 — [review] the retained-slot term was added to two slot predicates but not to the remaining/all-terminal counters a terminal notification carriespackages/core/src/agents/background-agent-resume.ts:1300 — [review] the new late-settlement guards compute stats and then discard them, and failUnresponsive takes no stats argument, so entry.stats is undefined permanentlypackages/core/src/tools/agent/agent.ts:3629 — [review] the success path forces TIMEOUT and flips signalAborted but never reads progressTimeout.message, so the terminal branch publishes the agent's own text beside a timeout statuspackages/acp-bridge/src/bridge.ts:4867 — [review] the re-scoped client-MCP-discovery predicate is covered only by a single-generation test that cannot distinguish the old predicate from the new- …and 1 more (see the run report)
Convergence: round 10 posted 11 inline comment(s), 7 of them reported for the first time; the previous round posted 4 (1 new). Findings keep coming back to the same files: packages/acp-bridge/src/bridge.ts (findings in round 1; 2 more now); packages/core/src/agents/background-tasks.ts (findings in round 9; 2 more now); packages/core/src/agents/runtime/agent-progress-watchdog.ts (findings in round 6; 2 more now), and 1 more file(s). The rate of new findings is not falling. A cluster that keeps producing siblings usually means the fixes are treating instances of a shared root cause — triaging that cause before the next round, or splitting an independent cluster into its own pull request, tends to end the loop faster than fixing them one at a time. Batching the remaining fixes and verifying them before the next push keeps the loop from re-deriving the same set; this PR's reviews already resolve to a critical posting floor. (Observation only — nothing was withheld from this review because of this observation.)
Residual risk: this loop is persistently critical — Criticals stood in the previous round's work-list and stand again this round (11 Critical(s)), the rate of first-time findings is not falling (this round 7, previous 1), and the standing Critical backlog is not shrinking. The severity floor will not converge it. Recommendation: land-with-residual-risk — the exit is a maintainer risk-acceptance decision (merge, carrying the residual risk), not another review round. Residual-risk inventory for that decision (maintainer to complete):
| standing Critical | attack surface | attacker-dependency | blast radius |
|---|---|---|---|
| (each standing Critical) | … | … | … |
Advisory only — it does not block this review.
中文说明
仅完成部分审查,审查缺口已披露。
本轮确认的 19 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未审查(原文为英文):build-and-test — Integration Tests (CLI, No Sandbox) was skipped in CI and its suite did not run locally.
未探索到全部深度(达到工具调用预算):"agent reverse-audit (round 1)":I did not establish that channelInfo === undefined with two non-dying draining generations is reachable outside the interleaving I constructed from bridge.ts:…;"agent reverse-audit (round 1)":I did not walk the ensureChannel('recovery') spawn body (bridge.ts:4715-5360) beyond the cap check and the channelInfo = info assignment, so side effects of…;"agent reverse-audit (round 1)":I did not verify that recordNotificationStrict is safe to call from #recordUnresponsiveAgentNotification outside runExclusiveAutomaticHistoryMutation (Ses…;chunk 4:did not execute the two new background-tasks.test.ts tests — packages/core/dist is absent in this worktree, the vitest globalSetup guard refuses to run wi…;"agent reverse-audit (round 1)":did not establish *why* the guardrail test's fake factory needed the exited change at all — that needs the test run with the change reverted against the pre-P…,另有 1 条。
未审查:反向审计——评审时间预算不足,未能开始第 4 轮。
收敛姿态下延后(第 10 轮,非阻断)——已记录,本轮不要求修改;其中 4 条 Critical 按其失败方向与对照基线延后——fails-closed 且 new-surface:未认证任何错误结果,且 merge base 既无该功能面也无该缺陷——作为后续工作记录在 findings 工件中:共 21 条(原文未翻译,列表见上方英文部分)。
收敛情况:第 10 轮发布了 11 条行内评论,其中 7 条是首次提出;上一轮发布了 4 条(其中 1 条首次提出)。发现反复回到同一批文件:packages/acp-bridge/src/bridge.ts(第 1 轮已出过发现,本轮又有 2 条);packages/core/src/agents/background-tasks.ts(第 9 轮已出过发现,本轮又有 2 条);packages/core/src/agents/runtime/agent-progress-watchdog.ts(第 6 轮已出过发现,本轮又有 2 条),另有 1 个文件。新发现的产出速度没有下降。一个不断再生兄弟发现的簇,通常意味着逐条修复只在处理同一根因的实例——先定位并处理该根因,或把独立的簇拆成单独的 PR,通常比逐条修复更快结束循环。把剩余修复攒成一批、验证后再推送,可以避免循环反复推导同一组发现;本 PR 的评审已解析为 critical 发布下限。(仅为观察——本轮评审未因此扣留任何内容。)
残余风险:本循环处于 persistently-critical 形态——上一轮工作清单中的 Critical 本轮依然存在(本轮 11 条 Critical),首次发现的速率没有下降(本轮 7,上一轮 1),且未决 Critical 积压没有减少。severity floor 无法使其收敛。建议:land-with-residual-risk——出口是 maintainer 的风险接受决定(合入并承担残余风险),而非再开一轮评审。供该决定使用的残余风险清单(maintainer 填写):按每条未决 Critical 列出「攻击面 · 攻击者依赖性 · 影响范围」三栏。仅为建议——不阻断本次评审。
— qwen3.8-max via Qwen Code /review (v0.23.3)
| armModel(); | ||
| }; | ||
|
|
||
| emitter.on(AgentEventType.START, onActivity); |
There was a problem hiding this comment.
[Critical] R10-1: [certifies-falsely] [new-surface] The watchdog is attached unconditionally in runBackgroundTurn, including for background Agents served by an external executor — and those executors emit almost none of the eleven events it renews on, so a healthy external run is charged to the 15-minute model deadline and killed.
The background turn has a documented two-executor split: executor === undefined for the in-process runtime, a SubagentExecutor for anything external (agent.ts:3059, :3073, :3414, :3477 all branch on it — for stats, never for the watchdog). attachAgentProgressWatchdog at agent.ts:3881 has no such guard, and it subscribes to exactly eleven AgentEventTypes.
For the Codex executor the intersection is one of four. It emits ERROR (gated on rawListeners(ERROR).length, and nothing on bgEmitter registers one), START, then ROUND_TEXT and FINISH in the finally after await runCodex(...) returns. ROUND_TEXT and FINISH are not in the watchdog's set, so from START onward no event ever reaches onActivity / onRoundStart / onToolHeartbeat. The emitter identity is guaranteed — bgEmitter = bgSubagent.getCore().getEventEmitter() (agent.ts:3401) and CodexSubagentExecutor.getCore() returns { getEventEmitter: () => this.emitter } with eventEmitter: options?.eventEmitter threaded through createAgentHeadless (subagent-manager.ts:1036) — so this is the emitter the executor emits on. And max_time_minutes === undefined means Codex arms no execution timer at all (codex-subagent-executor.ts:252-259), leaving the watchdog as the only clock. At exactly 900s abort() kills the Codex child through its signal listener, terminateMode is forced to TIMEOUT, and registry.fail settles the entry as failed with 'made no model/control progress for 900000ms' — a run that was streaming work the whole time, reported to the parent model as a stalled failure, with no retry.
The ACP external executor has the same shape one level finer: it emits TOOL_CALL once per tool and never TOOL_PROGRESS, so onToolCall leaves the peer's tool in state queued, which armModel()'s suppression test (executing || approval || parkedOnInput) does not count — a peer spending more than fifteen minutes inside one external tool call is charged to the model deadline, contradicting the design doc's 'a silent tool is not charged to the model deadline'.
This is not the issue's stated goal. Issue 8586 asks for detection of 'an Agent that remains alive while its asynchronous model/tool logic makes no progress'; an external executor's progress is simply invisible to this event vocabulary. Neither design doc nor the PR description mentions external executors anywhere, so the doc's 'Each fresh, restored, and resident-continuation background turn has two fixed internal deadlines' reads as coverage that does not exist.
Witness:
N2 arm A (codex event set: START only):            aborted@15min=model/control   (at 14:59 => undefined)
N2 arm B (same run + one STREAM_TEXT per 50s):     aborted=undefined after 1000s
Real attachAgentProgressWatchdog under a virtual clock. Arm A replays the Codex executor's exact event set and is killed at precisely 15:00 with phase model/control; arm B is the same run with the one event the in-process AgentHeadless does emit, and survives. The differential isolates the missing renewal to the event set, not to the duration. Population sweep, using the executors' own source as the authority: the watchdog subscribes to 11 event types; the Codex executor has 4 emit sites and intersects that set at 1.
Suggested direction: gate both attach sites on the discriminator the background path already uses — subagentConfig.executor === undefined — so the watchdog is only armed for a runtime that speaks its event vocabulary, and state the exclusion in both language versions of docs/design/background-agent-progress-watchdog.md. If covering external Agents is genuinely intended, the fix is the other way round: have CodexSubagentExecutor / AcpSubagentExecutor emit TOOL_PROGRESS (and re-emit on tool_call_update) so onToolHeartbeat can move the call to executing.
Constraint the fix must not violate: agent.ts:3414 subagentConfig.executor !== undefined is the existing background-path carve-out (repeated at :3477), so a new gate must reuse that predicate rather than introduce a second notion of 'external'. And codex-subagent-executor.ts:252-259 minutes === undefined ? undefined : setTimeout(...) means an unset max_time_minutes leaves the Codex run with no time bound at all — a fix that merely 'lets the definition's limit apply' restores an unbounded run and must say so in the doc.
Acceptance criterion: in agent.test.ts, a background launch whose subagentConfig.executor is set, with a fake executor whose getCore().getEventEmitter() returns the background emitter and which emits only START then never settles; under fake timers, advancing 15 minutes must leave registry.get(agentId).status === 'running' and turnAbortController.signal.aborted === false. Remove the executor gate and it reds with status === 'failed' and reason 'made no model/control progress for 900000ms.'
中文说明
后台 turn 有明确的双执行器划分:executor === undefined 表示进程内运行时,SubagentExecutor 表示任何外部执行器(agent.ts:3059、:3073、:3414、:3477 都据此分支——用于统计,却从不用于 watchdog)。agent.ts:3881 的 attachAgentProgressWatchdog 没有这层判断,而它恰好订阅了十一种 AgentEventType。
对 Codex 执行器而言,交集只有四分之一个。它发出 ERROR(受 rawListeners(ERROR).length 限制,而 bgEmitter 上没有任何监听器注册它)、START,然后在 await runCodex(...) 返回后的 finally 中发出 ROUND_TEXT 与 FINISH。ROUND_TEXT 和 FINISH 都不在 watchdog 的集合里,因此从 START 之后再没有任何事件能到达 onActivity / onRoundStart / onToolHeartbeat。emitter 的身份是有保证的——bgEmitter = bgSubagent.getCore().getEventEmitter()(agent.ts:3401),而 CodexSubagentExecutor.getCore() 返回 { getEventEmitter: () => this.emitter },eventEmitter: options?.eventEmitter 经 createAgentHeadless(subagent-manager.ts:1036)传入——所以这正是该执行器发出事件的 emitter。并且 max_time_minutes === undefined 意味着 Codex 根本不会启动执行计时器(codex-subagent-executor.ts:252-259),watchdog 成了唯一的时钟。在恰好 900 秒时 abort() 通过其 signal 监听器杀掉 Codex 子进程,terminateMode 被强制为 TIMEOUT,registry.fail 把条目结算为 failed,理由是 'made no model/control progress for 900000ms'——一个全程都在输出工作的运行,被作为停滞失败上报给父模型,且不重试。
ACP 外部执行器是同一形状的更细一层:它每个工具只发一次 TOOL_CALL,从不发 TOOL_PROGRESS,因此 onToolCall 会把对端工具留在 queued 状态,而 armModel() 的抑制判断(executing || approval || parkedOnInput)不计入它——对端在单个外部工具调用内停留超过十五分钟就会被计入模型截止时间,这与设计文档的「静默工具不计入模型截止时间」相矛盾。
这也不是 issue 的目标。issue 8586 要求检测「Agent 仍存活但其异步模型/工具逻辑没有推进」的情形;外部执行器的推进在这套事件词汇里根本不可见。两份设计文档与 PR 描述都完全没有提到外部执行器,因此文档中「每个新的、恢复的、常驻续跑的后台 turn 都有两个固定内部截止时间」读起来像是一种并不存在的覆盖。
建议方向:在两个 attach 点都用后台路径已有的判别条件——subagentConfig.executor === undefined——把 watchdog 只武装给使用其事件词汇的运行时,并在 docs/design/background-agent-progress-watchdog.md 的两个语言版本中写明这一排除。如果确实希望覆盖外部 Agent,修复方向应相反:让 CodexSubagentExecutor / AcpSubagentExecutor 发出 TOOL_PROGRESS(并在 tool_call_update 时重发),使 onToolHeartbeat 能把调用置为 executing。
约束:agent.ts:3414 的 subagentConfig.executor !== undefined 是后台路径已有的豁免判断(:3477 重复),新的判断必须复用该谓词,而不是另造一套「外部」概念。另外 codex-subagent-executor.ts:252-259 表明未设置 max_time_minutes 时 Codex 运行完全没有时间上限——仅「让定义里的限制生效」的修复会恢复无界运行,必须在文档中写明。
验收标准:在 agent.test.ts 中,构造一个设置了 subagentConfig.executor 的后台启动,其伪执行器的 getCore().getEventEmitter() 返回后台 emitter,且只发出 START 之后永不结算;在 fake timers 下推进 15 分钟,registry.get(agentId).status 必须仍为 running,turnAbortController.signal.aborted 必须为 false。移除执行器判断后应变红,status 为 failed、原因为 'made no model/control progress for 900000ms.'。
— qwen3.8-max via Qwen Code /review (v0.23.3)
| ): void { | ||
| let pendingConfirmationCallId: string | undefined; | ||
| const preserveProtocolPayloads = !this.config.isInteractive(); | ||
| const waitingForApproval = () => |
There was a problem hiding this comment.
[Critical] R10-2: [certifies-falsely] [new-surface] waitingForApproval()'s !some(executing) suppression term makes the propagated awaitingApproval flag false whenever the parked call has any batch sibling — even one that never started — so the parent's watchdog kills a background agent that is parked on a nested user approval.
The predicate requires that no call in the batch display as executing. But currentToolCalls is populated by the TOOL_CALL listener, which stamps every call in the batch status: 'executing' (agent.ts:1509-1515), and agent-core.ts:2392 emits TOOL_CALL for all prepared calls up front, inside authorizedCalls.map before scheduling. The TOOL_WAITING_APPROVAL handler flips only the parked call (agent.ts:1629-1633). And the scheduler guarantees the sibling produces no TOOL_RESULT while the approval is parked — attemptExecutionOfScheduledCalls returns as soon as hasExecutingOrAwaitingApprovalCall() (coreToolScheduler.ts:4612-4634) — leaving the sibling at scheduled while its display row still reads executing. So the predicate evaluates true && !true → false, the chunk carries no flag, the parent's outputUpdateHandler re-emits it as a plain heartbeat, and onToolHeartbeat arms TOOL_PROGRESS_TIMEOUT_MS for the ancestor's call.
A background agent BG running a foreground nested subagent NS therefore gets a ten-minute deadline over a wait that every other layer exempts — onApproval clears the timer outright. If the user takes more than ten minutes to answer, BG is aborted with AgentProgressTimeoutError('tool', ..., 'agent'), the escalation's rejectPendingApprovals rejects the approval the user was being asked for, and BG is settled as failed with 'made no progress for 600000ms'. A top-level agent in the identical approval wait is never killed; only the nested case is — exactly where this PR's new flag-propagation chain was built to prevent it. The design doc in this diff says the opposite twice: 'The relevant tool deadline is suspended while user approval is pending' and 'approval waits ... must not cause false watchdog failures'.
Witness:
N3 arm A (no flag, approval parked 10min): aborted=tool  reason=Background agent tool "agent" made no progress for 600000ms.
N3 arm B (awaitingApproval:true):          aborted@10min=undefined  @70min=undefined
Real watchdog under a virtual clock; the flag is the only thing standing between a parked nested approval and a ten-minute kill. The agent.ts half is the quoted trace — agent.test.ts has zero occurrences of awaitingApproval / waitingForExternalInput, so no existing harness covers it.
const waitingForApproval = () =>
  this.currentToolCalls!.some((call) => call.status === 'awaiting_approval');
Dropping the suppression term makes the flag reflect the parked call itself. Alternatively derive it from the nested scheduler's real state rather than from display statuses, since TOOL_CALL marks queued calls executing.
Constraint the fix must not violate: the consumer parks the outer watchdog unconditionally — agent-progress-watchdog.ts:181-188 if (event.awaitingApproval) { tool.state = 'approval'; ... clearTimeout(tool.timer); } — and armModel() early-returns while any tool is in approval (:100-108). So making the flag sticky also removes the outer ten-minute deadline for a sibling that is genuinely executing but silent; the fix must accept that the nested run's own watchdog (attached per turn at agent.ts:3881-3890) is the remaining deadline authority for that sibling.
Acceptance criterion: in agent.test.ts, drive the display listeners — emit TOOL_CALL A, TOOL_CALL B, then TOOL_WAITING_APPROVAL A — and assert the updateOutput chunk carries awaitingApproval: true. Red on current code (the flag is suppressed by B's executing display status), green after the fix.
中文说明
该谓词要求批次中没有任何调用显示为 executing。但 currentToolCalls 是由 TOOL_CALL 监听器填充的,它会把批次中每一个调用都标记为 status: 'executing'(agent.ts:1509-1515),而 agent-core.ts:2392 会在调度之前、在 authorizedCalls.map 内部一次性为所有已准备的调用发出 TOOL_CALL。TOOL_WAITING_APPROVAL 处理只翻转被 park 的那一个调用(agent.ts:1629-1633)。而调度器保证在审批 park 期间兄弟调用不会产生 TOOL_RESULT——attemptExecutionOfScheduledCalls 一旦 hasExecutingOrAwaitingApprovalCall() 为真就返回(coreToolScheduler.ts:4612-4634)——于是兄弟调用停在 scheduled,其 display 行却仍显示 executing。因此谓词求值为 true && !true → false,chunk 不带标志,父级 outputUpdateHandler 把它作为普通心跳重新发出,onToolHeartbeat 便为祖先的调用启动 TOOL_PROGRESS_TIMEOUT_MS。
于是运行前台嵌套子代理 NS 的后台代理 BG,会在一个其他所有层都豁免的等待上得到十分钟截止时间——onApproval 会直接清除计时器。如果用户超过十分钟才回答,BG 会以 AgentProgressTimeoutError('tool', ..., 'agent') 被 abort,升级流程的 rejectPendingApprovals 会拒绝用户正在被询问的审批,BG 被结算为 failed,理由是 'made no progress for 600000ms'。处于完全相同审批等待的顶层代理永远不会被杀;只有嵌套场景会——而这恰恰是本 PR 新增标志传播链要防止的地方。本 diff 的设计文档两次表达了相反的语义:「用户审批待处理期间,相关工具截止时间被挂起」以及「审批等待……不得导致误报的 watchdog 失败」。
去掉抑制项即可让标志反映被 park 的调用本身;或者从嵌套调度器的真实状态派生,而不是从 display 状态派生,因为 TOOL_CALL 会把排队中的调用标为 executing。
约束:消费方是无条件 park 外层 watchdog 的——agent-progress-watchdog.ts:181-188 if (event.awaitingApproval) { tool.state = 'approval'; ... clearTimeout(tool.timer); }——且只要有工具处于 approval,armModel() 就会提前返回(:100-108)。因此让标志变得粘滞,同时也会移除某个确实在执行但静默的兄弟调用的外层十分钟截止时间;修复必须接受:对该兄弟调用而言,剩余的唯一截止时间权威是嵌套运行自己的 watchdog(在 agent.ts:3881-3890 按 turn 挂载)。
验收标准:在 agent.test.ts 中驱动 display 监听器——依次发出 TOOL_CALL A、TOOL_CALL B,再发出 TOOL_WAITING_APPROVAL A——断言 updateOutput 的 chunk 携带 awaitingApproval: true。当前代码下应为红(标志被 B 的 executing 显示状态抑制),修复后为绿。
— qwen3.8-max via Qwen Code /review (v0.23.3)
| * reap). Draining generations retain their Session owners but cannot accept | ||
| * fresh work; dying generations are unavailable while the OS reaps them. | ||
| */ | ||
| state: 'active' | 'draining' | 'dying'; |
There was a problem hiding this comment.
[Critical] R10-3: [certifies-falsely] [new-surface] The new draining state is honored by ensureChannel / doSpawn / loadSession, but not by the single-scope defaultEntry attach fast-path — and the recycle never clears defaultEntry — so after a recycle the daemon keeps handing brand-new clients the session on the condemned generation.
The daemon's primary bridge is created without sessionScope (serve/server.ts:1188 passes none), so defaultSessionScope = opts.sessionScope ?? 'single' (bridge.ts:2800). A client's POST /session creates session S on gen1 and if (effectiveScope === 'single' && !defaultEntry) defaultEntry = entry; (bridge.ts:5967) makes S the workspace default. When a recycle condemns gen1 and spawns gen2, the next POST /session (no id, no scope) takes the single-scope branch at bridge.ts:10032, and assertAttachableSessionEntry (bridge.ts:6437-6443) passes because it still tests only owner.isDying — gen1 is draining, not dying. The caller gets S back with attached: true, and its next prompt runs on the child the daemon just judged unsafe. That is what the design doc in this same diff forbids ('must not ... route new work back to the draining generation') and what your own comment at bridge.ts:5789-5793 names as the harm.
The stranding compounds: each attach bumps attachCount, so sessionIds.size on gen1 never reaches 0, reapPendingEmptyChannel never fires, and workOwningGenerations (bridge.ts:4699-4711) stays at two non-dying generations. From then on every ensureChannel — all thread-scope work (live-task-service.ts:1067, scheduled-task-keepalive.ts:164, create-sub-session.ts:905 all pass sessionScope: 'thread') and any second recycle — throws BridgeRuntimeRecyclingError: a permanent 503 runtime_recycling for the workspace while gen2 sits idle.
None of the three new tests can catch this: all three construct the bridge with sessionScope: 'thread', which by design never touches defaultEntry.
Witness:
not run — nearest capability was a bridge.test.ts case omitting sessionScope; `review scratch-tree`
returned available: false on this host, so no test could be added without writing into the shared
review worktree. The attach fast-path and defaultEntry assignment were settled by reading
bridge.ts:2800, :5967, :6437-6443 and :10032 at the reviewed commit; the round-2 recycle probe
shows the two-generation state this path runs in:
[after requestRuntimeRecycle] gen1.killed=false gen2.killed=false sessionCount=1 isChannelLive=true
Suggested direction: gate the single-scope attach on the owner's generation state and let the created session take over the default — in spawnOrAttach's single-scope branch, treat defaultEntry as absent when channelInfoForEntry(defaultEntry)?.state !== 'active', and assign the newly created entry to defaultEntry on that path. Do not widen assertAttachableSessionEntry itself: it also guards the restore racedEntry re-attach (bridge.ts:8941) and ordinary re-attach of existing sessions, which must keep working during a drain.
Constraint the fix must not violate: bridge.ts:5967 if (effectiveScope === 'single' && !defaultEntry) defaultEntry = entry; — a fix that only skips the attach without letting the new entry become the default makes every subsequent single-scope POST /session create yet another session, losing the coalescing single scope exists for. Also bridge.ts:3877 owner.state = 'active'; in the cap-refused rollback: clearing defaultEntry at condemn time without restoring it on rollback leaves a rolled-back generation with no default session.
Acceptance criterion: a case in the new describe('requestRuntimeRecycle — draining generation admission') block that omits sessionScope: spawnOrAttach → S on gen1; requestRuntimeRecycle(S); a second spawnOrAttach({workspaceCwd: WS_A}) must return a different sessionId owned by gen2 with attached falsy, and closing S must then make gen1.killed true. Remove the state gate and the second call returns S again — red.
中文说明
守护进程的主 bridge 创建时不带 sessionScope(serve/server.ts:1188 未传),因此 defaultSessionScope = opts.sessionScope ?? 'single'(bridge.ts:2800)。客户端的 POST /session 在 gen1 上创建会话 S,并由 bridge.ts:5967 的 if (effectiveScope === 'single' && !defaultEntry) defaultEntry = entry; 把 S 设为工作区默认。当 recycle 判定 gen1 不可信并生成 gen2 后,下一次 POST /session(无 id、无 scope)会走 bridge.ts:10032 的 single 分支,而 assertAttachableSessionEntry(bridge.ts:6437-6443)仍然只检查 owner.isDying——gen1 是 draining 而非 dying——于是通过。调用方拿回 S 且 attached: true,它的下一次 prompt 就运行在守护进程刚刚判定为不安全的子进程上。这正是同一 diff 中设计文档所禁止的(「不得……把新工作路由回 draining 的那一代」),也是你自己在 bridge.ts:5789-5793 的注释中所指出的危害。
滞留会叠加:每次 attach 都会增加 attachCount,因此 gen1 上的 sessionIds.size 永远不会归零,reapPendingEmptyChannel 永不触发,workOwningGenerations(bridge.ts:4699-4711)停留在两个非 dying 代。此后每一次 ensureChannel——所有 thread 作用域的工作(live-task-service.ts:1067、scheduled-task-keepalive.ts:164、create-sub-session.ts:905 都传 sessionScope: 'thread')以及任何第二次 recycle——都会抛出 BridgeRuntimeRecyclingError:该工作区永久返回 503 runtime_recycling,而 gen2 闲置。
三个新测试都无法发现这一点:它们都以 sessionScope: 'thread' 构造 bridge,而按设计这条路径根本不碰 defaultEntry。
建议方向:让 single 作用域的 attach 依据所属代的状态进行判断,并让新创建的会话接管默认值——在 spawnOrAttach 的 single 分支中,当 channelInfoForEntry(defaultEntry)?.state !== 'active' 时把 defaultEntry 视为不存在,并在该路径上把新建条目赋给 defaultEntry。不要直接放宽 assertAttachableSessionEntry:它同时还保护 restore 的 racedEntry 重挂载(bridge.ts:8941)以及既有会话的普通重挂载,这些在 drain 期间必须继续可用。
约束:bridge.ts:5967 的赋值意味着——只跳过 attach 而不让新条目成为默认,会使后续每次 single 作用域的 POST /session 都再创建一个会话,失去 single 作用域本应提供的合并能力。另外 bridge.ts:3877 的 owner.state = 'active';(容量拒绝时的回滚)意味着:若在判定不可信时清除 defaultEntry 却不在回滚时恢复,会让回滚后的那一代没有默认会话。
验收标准:在新增的 describe('requestRuntimeRecycle — draining generation admission') 中增加一个不传 sessionScope 的用例:spawnOrAttach → gen1 上的 S;requestRuntimeRecycle(S);第二次 spawnOrAttach({workspaceCwd: WS_A}) 必须返回由 gen2 拥有的不同 sessionId 且 attached 为假,随后关闭 S 应使 gen1.killed 为 true。移除状态判断后第二次调用会再次返回 S——测试变红。
— qwen3.8-max via Qwen Code /review (v0.23.3)
| * A watchdog-terminal run still counts while its underlying execution holds | ||
| * a physical slot, so session reset cannot erase the only remaining owner. |
There was a problem hiding this comment.
[Critical] R10-4: [certifies-falsely] [new-surface] The retained-slot state was added to hasRunningTasks() and getRunningBackgroundCount() but not to the sibling predicate listUnfinalizedBackgroundAgentIds() — which is the sole source of the ACP child's agent active-work holds, so in the daemon a session with a provably still-executing background agent reports zero holds and grades idle.
listUnfinalizedBackgroundAgentIds() yields ids only for status === 'running' || (status === 'cancelled' && !entry.notified). After an escalation the entry is failed and notified, so the id drops out and Session.collectActiveWorkHolds() (Session.ts:4178-4184) pushes no {category:'agent'} hold. On the daemon side childReportsHeldWork() reads only entry.childHolds (bridge.ts:3187-3193), so entryActiveWorkState() returns 'idle' (bridge.ts:3226-3244), and entryIsAutoCloseCandidate() — which consults entryHasLocalWork(), subscriber count and restore state but never hasRunningBackgroundTasks — admits the session to automatic teardown once the reaper TTL elapses with no subscribers, which a fifteen-minute-plus wedged run makes likely. The conditional-close round trip is answered by the child from the same empty hold set, so the session is closed and disposed around an execution that is still alive and still writing its transcript and sidecar.
That also disables this PR's own containment: once the entry leaves byId, the sessionRuntimeRecycle route can no longer resolveEntry / ownsSession the id, so the generation the daemon judged unsafe is never condemned. And the same snapshot publishes the contradiction to clients — hasRunningBackgroundTasks: true (active-work-reporter.ts:130-131, rendered by WebShellSidebar.tsx:4407 as a live task session) beside activeWorkState: 'idle'. This is the outcome your own new comment on these very lines says must not happen: 'so session reset cannot erase the only remaining owner'.
Witness:
not run — nearest capability was a background-tasks.test.ts extension of the existing <all-terminal>
block plus a Session-level hold probe; `review scratch-tree` returned available: false on this host.
The structural half was run: the R9-1 probe shows `retainsPhysicalSlot=true hasRunningTasks=true`
persisting after the terminal transition, from unmodified code. The predicate asymmetry is quoted
from background-tasks.ts:1358, :1491 and :1522 at the reviewed commit.
Suggested direction: give the retained state a hold without widening the headless predicate — add || entry.retainsPhysicalSlot === true to the push condition in listUnfinalizedBackgroundAgentIds(), leaving hasUnfinalizedTasks() untouched; or emit a separate {category:'agent', id} hold in collectActiveWorkHolds() for entries the registry reports as slot-retaining.
Constraint the fix must not violate: hasUnfinalizedTasks() must NOT gain the term — background-tasks.ts:1516 states 'Headless holdback loops must keep using hasUnfinalizedTasks() so every task_started still pairs with a task_notification', and its read sites nonInteractiveCli.ts:1683 and :3122 gate the headless holdback loop on it, so a retained (never-settling) entry added there would pin the loop until holdbackDeadline on every wedge. The doc at background-tasks.ts:1486-1489 also records that the id list 'Deliberately shares hasUnfinalizedTasks()'s predicate (and not hasRunningTasks()'s)' — that deliberate sharing is what this change breaks, so the fix must state the new divergence where the old one is documented.
Acceptance criterion: extend background-tasks.test.ts's 'retains the physical slot when the watchdog escalates a cancelled agent' with expect(registry.listUnfinalizedBackgroundAgentIds()).toEqual(['test-1']) after failUnresponsive — removing the added term must red it — and pair it with a Session.test.ts case asserting collectActiveWorkHolds() yields an agent hold for a retained entry, since that is the contract the daemon grades on.
中文说明
listUnfinalizedBackgroundAgentIds() 只会为 status === 'running' || (status === 'cancelled' && !entry.notified) 的条目产出 id。升级之后条目既是 failed 又已 notified,因此该 id 落选,Session.collectActiveWorkHolds()(Session.ts:4178-4184)不会推入任何 {category:'agent'} hold。守护进程侧的 childReportsHeldWork() 只读取 entry.childHolds(bridge.ts:3187-3193),于是 entryActiveWorkState() 返回 'idle'(bridge.ts:3226-3244),而 entryIsAutoCloseCandidate()——它只查 entryHasLocalWork()、订阅者数量与 restore 状态,从不查 hasRunningBackgroundTasks——会在无订阅者且 reaper TTL 到期后允许该会话被自动拆除;一个卡住十五分钟以上的运行很容易造成这种情形。条件关闭的往返请求由子进程用同一份空 hold 集合应答,于是会话在一个仍然存活、仍在写 transcript 与 sidecar 的执行周围被关闭并释放。
这同时使本 PR 自己的隔离能力失效:条目一旦离开 byId,sessionRuntimeRecycle 路由就无法再对该 id 执行 resolveEntry / ownsSession,被守护进程判定为不安全的那一代永远不会被标记不可信。同一份快照还把矛盾暴露给客户端——hasRunningBackgroundTasks: true(active-work-reporter.ts:130-131,被 WebShellSidebar.tsx:4407 渲染为活跃任务会话)与 activeWorkState: 'idle' 并列。这正是你在这几行新增注释中声明不得发生的结果:「因此会话重置不能抹掉唯一剩下的持有者」。
建议方向:在不放宽 headless 谓词的前提下为保留态增加一个 hold——在 listUnfinalizedBackgroundAgentIds() 的推入条件中加上 || entry.retainsPhysicalSlot === true,保持 hasUnfinalizedTasks() 不变;或在 collectActiveWorkHolds() 中为注册表报告为保留槽位的条目单独发出一个 {category:'agent', id} hold。
约束:hasUnfinalizedTasks() 绝不能加上该项——background-tasks.ts:1516 写明「Headless 的滞留循环必须继续使用 hasUnfinalizedTasks(),以保证每个 task_started 都能与一个 task_notification 配对」,其读取点 nonInteractiveCli.ts:1683 与 :3122 据此控制 headless 滞留循环,因此把一个保留态(永不结算)条目加进去会让该循环在每次卡死时都被钉住直到 holdbackDeadline。background-tasks.ts:1486-1489 的注释也记录了该 id 列表「有意共享 hasUnfinalizedTasks() 的谓词(而非 hasRunningTasks() 的)」——这一有意的共享正是本次改动所打破的,因此修复必须在记录旧约定的地方写明新的分歧。
验收标准:在 background-tasks.test.ts 的 'retains the physical slot when the watchdog escalates a cancelled agent' 中,于 failUnresponsive 之后补充 expect(registry.listUnfinalizedBackgroundAgentIds()).toEqual(['test-1'])——移除新增项应使其变红——并配一个 Session.test.ts 用例,断言 collectActiveWorkHolds() 会为保留态条目产出 agent hold,因为这才是守护进程据以评级的契约。
— qwen3.8-max via Qwen Code /review (v0.23.3)
| ); | ||
| if (!owner.isDying) { | ||
| try { | ||
| await ensureChannel('recovery'); |
There was a problem hiding this comment.
[Critical] R10-5: [certifies-falsely] [new-surface] The recycle's replacement generation is spawned bare — no runtimeOperationReservations hold and no keep-alive — so under the daemon's default channelIdleTimeoutMs = 0 policy the first workspace-control/status operation that completes reaps the generation the recycle just installed.
requestRuntimeRecycleForSession marks the owner draining, defers its retirement while its sessions are attached, and calls ensureChannel('recovery') to spawn the replacement. The replacement is published as channelInfo with nothing protecting it: only bridge.ts:15530+ sets keepAliveUntil / pendingKeepAliveDeadlines, and addRuntimeMcpServer establishes none itself. withWorkspaceControl's finally (bridge.ts:4157-4161) then calls startIdleTimer for the generation it just resolved, and resolvedChannelIdleTimeoutMs() is 0 by production default — run-qwen-serve.ts:2330-2335 maps undefined to 0, documented as '0 = immediate kill'. So the replacement is killed outright, leaving isChannelLive() false and every admissibleChannelInfo()-gated route throwing acp_channel_unavailable while the draining owner is alive and serving.
The recycle's own purpose — leave the workspace with one serving generation — is defeated by the replacement being reaped immediately after installation, and the workspace ends up with no admissible generation at all.
Witness:
[after requestRuntimeRecycle] gen1.killed=false gen2.killed=false sessionCount=1 isChannelLive=true
addRuntimeMcpServer resolved -> {}
[after workspace MCP add]     gen1.killed=false gen2.killed=true  sessionCount=1 isChannelLive=false
removeRuntimeMcpServer THREW: No live ACP channel for runtime MCP remove: srv {"errorKind":"acp_channel_unavailable"}
Observed inside this round's R1-36 differential, against the real createAcpSessionBridge with production-default channelIdleTimeoutMs: the generation that had just received the registration was killed by the idle path, and the follow-up route then failed. Declared limit: no keep-alive was active in the harness, and a keep-alive left over from a recent ensure would postpone that kill.
Suggested direction: install the replacement with the same protection the primary gets — take a runtimeOperationReservations hold (or set keepAliveUntil) across the recycle's replacement spawn and release it once the owner has drained — or exempt a freshly installed recovery generation from the 0 ms immediate-kill policy until its first session attaches.
Constraint the fix must not violate: run-qwen-serve.ts:2330-2335 maps an unset channelIdleTimeoutMs to 0 and documents '0 = immediate kill', so the fix cannot rely on a nonzero default; and bridge.ts:3877 owner.state = 'active'; in the cap-refused rollback must still leave exactly one serving generation, so a hold added here has to be released on the rollback path too.
Acceptance criterion: in bridge.test.ts, recycle gen1 with a session attached, run one workspace-control round trip (e.g. refreshChildResource()), and assert gen2 is still alive and isChannelLive() is true; removing the hold must red it.
中文说明
requestRuntimeRecycleForSession 会把原持有代标记为 draining、在其会话仍挂载期间推迟退役,并调用 ensureChannel('recovery') 生成替代代。替代代被发布为 channelInfo 时没有任何保护:只有 bridge.ts:15530+ 会设置 keepAliveUntil / pendingKeepAliveDeadlines,而 addRuntimeMcpServer 自身并不建立。随后 withWorkspaceControl 的 finally(bridge.ts:4157-4161)会为它刚解析出的那一代调用 startIdleTimer,而生产默认下 resolvedChannelIdleTimeoutMs() 为 0——run-qwen-serve.ts:2330-2335 把 undefined 映射为 0,文档写明「0 = 立即 kill」。于是替代代被直接杀掉,isChannelLive() 变为 false,所有受 admissibleChannelInfo() 约束的路由抛出 acp_channel_unavailable,而 drain 中的旧代却仍然存活并在服务。
recycle 自身的目的——让工作区留下一个可服务的代——被「替代代安装后立即被回收」所破坏,最终工作区没有任何可接纳的代。
建议方向:让替代代获得与主代相同的保护——在 recycle 的替代代生成期间取得一个 runtimeOperationReservations 持有(或设置 keepAliveUntil),并在旧代 drain 完成后释放;或让刚安装的 recovery 代在其第一个会话挂载前豁免于 0 ms 立即 kill 策略。
约束:run-qwen-serve.ts:2330-2335 把未设置的 channelIdleTimeoutMs 映射为 0 并注明「0 = 立即 kill」,因此修复不能依赖非零默认值;而 bridge.ts:3877 容量拒绝回滚中的 owner.state = 'active'; 仍须保证恰好留下一个可服务的代,所以这里新增的持有也必须在回滚路径上释放。
验收标准:在 bridge.test.ts 中,对带有会话的 gen1 执行 recycle,跑一次工作区控制往返(例如 refreshChildResource()),断言 gen2 仍存活且 isChannelLive() 为 true;移除该持有应使测试变红。
— qwen3.8-max via Qwen Code /review (v0.23.3)
| const tools = new Map<string, ToolDeadline>(); | ||
|
|
||
| const abort = (error: AgentProgressTimeoutError) => { | ||
| if (disposed || controller.signal.aborted) return; |
There was a problem hiding this comment.
[Critical] R10-6: [new-surface] abort()'s controller.signal.aborted guard makes the escalation — and therefore retainsPhysicalSlot, the record-only notification and the daemon's runtime recycle — unreachable in the cancel-first ordering, so a run that ignores a user cancel is never marked unresponsive.
abort() returns early when controller.signal.aborted is already true. In the cancel-first ordering the user's task_stop aborts the same turn controller, so a watchdog deadline that fires afterwards never reaches armEscalation: onUnresponsive is never invoked, registry.failUnresponsive never runs, retainsPhysicalSlot never latches, the sidecar is never patched, and no record-only notification is emitted. A run that ignores the user's cancel therefore keeps executing while the registry reports it cancelled and hasRunningTasks() no longer counts it — which drives /clear, /resume, /branch and session switches over live work.
Recording this without a direction, deliberately: the verifier could not settle which of two readings is worse, and no run distinguished them. The retention half makes hasRunningTasks() return false over live work (certifies-falsely); the missing escalation means a wedged run is never contained (fails-closed). Both are live at the reviewed commit, so per the posting rule a blocker whose axes cannot be classified is reported rather than deferred.
Witness:
not run — nearest capability was an agent-progress-watchdog.test.ts probe (the file this diff adds at
:1-192 is directly copyable scaffolding: attach(), controller.abort() externally, toolProgress('t1'),
advance past the deadline, assert onUnresponsive never fires); `review scratch-tree` returned
available: false on this host, so no test could be added without writing into the shared review
worktree. The guard and its reachability were settled by reading agent-progress-watchdog.ts:60-77
and the two attach/detach sites at agent.ts:3881-3917 and background-agent-resume.ts:1414-1438.
Suggested direction: separate 'this watchdog already fired' from 'someone else aborted the controller' — guard the escalation on the watchdog's own fired/disposed state rather than on controller.signal.aborted, so a deadline that expires after an external abort still escalates. If it must not, record why, and make hasRunningTasks() reflect the still-live run so the session gates stop reporting a false all-clear.
Constraint the fix must not violate: abort()'s early return also provides single-fire idempotency — a second timer firing after an abort must stay a no-op — and dispose() clears modelTimer, escalationTimer and every tool.timer, so a narrower guard must not introduce a second escalation for the same deadline. background-tasks.ts:1763 if (entry.notified) return; remains the re-entrancy fence on the notification side.
Acceptance criterion: in agent-progress-watchdog.test.ts, attach, abort the controller externally, emit a toolProgress, advance past the tool deadline plus the grace, and assert onUnresponsive was called once; the change that removes it must red that test.
中文说明
当 controller.signal.aborted 已为 true 时,abort() 会提前返回。在「取消在先」的顺序中,用户的 task_stop 已经 abort 了同一个 turn controller,因此之后触发的 watchdog 截止时间永远到不了 armEscalation:onUnresponsive 不会被调用,registry.failUnresponsive 不会执行,retainsPhysicalSlot 不会锁存,sidecar 不会被改写,也不会发出 record-only 通知。于是一个无视用户取消的运行会继续执行,而注册表把它报告为已取消、hasRunningTasks() 也不再计入它——这会让 /clear、/resume、/branch 和会话切换在仍有活跃工作的情况下被放行。
这里有意不标注 direction:验证者无法判定两种解读中哪一种更糟,也没有任何运行能区分它们。保留态那一半会让 hasRunningTasks() 在仍有活跃工作时返回 false(certifies-falsely);缺失的升级意味着卡死的运行永远不会被隔离(fails-closed)。两者在被审查的提交上都成立,因此按发布规则,轴向无法归类的阻塞项应当上报而非延后。
建议方向:把「本 watchdog 已经触发过」与「别人 abort 了这个 controller」区分开——用 watchdog 自身的 fired/disposed 状态而非 controller.signal.aborted 来约束升级,使得在外部 abort 之后到期的截止时间仍能升级。如果确实不应升级,请写明原因,并让 hasRunningTasks() 反映仍然存活的运行,使会话闸门不再报告虚假的「全部结束」。
约束:abort() 的提前返回同时提供了单次触发的幂等性——abort 之后第二个定时器触发必须仍是空操作——且 dispose() 会清除 modelTimer、escalationTimer 以及每个 tool.timer,因此收窄后的判断不得为同一截止时间引入第二次升级。background-tasks.ts:1763 的 if (entry.notified) return; 仍是通知侧的重入栅栏。
验收标准:在 agent-progress-watchdog.test.ts 中,attach 之后从外部 abort controller,发出一个 toolProgress,推进到超过工具截止时间加宽限期,断言 onUnresponsive 被调用恰好一次;移除该修改应使测试变红。
— qwen3.8-max via Qwen Code /review (v0.23.3)
5 participants


What this PR does
Adds fixed progress watchdogs to ordinary background Agent turns, including fresh launches, restored runs, and resident continuations. Model/control work times out after 15 minutes without observable progress; each executing tool has its own 10-minute progress deadline. Tool output and silent-shell liveness updates renew only that tool's deadline.
A watchdog expiry cooperatively aborts the turn and is reported as
TIMEOUT, then persisted and notified once asfailed. It never enters the workflow retry loop. If the turn ignores that abort, the registry retains its physical slot while the daemon drains and replaces the owning Session runtime generation; existing Sessions stay pinned to their owner generation and fresh work uses the active replacement.Why it's needed
A background Agent can remain registered as running while its model, control flow, or a tool has stopped making progress. The existing workflow watchdog cannot be reused because it retries and deliberately suspends timing for every running tool. This leaves ordinary background Agents able to wedge indefinitely and keep their Session active without a terminal result.
Approval waits pause the affected tool deadline. A no-tool round waiting for Monitor-owned external input pauses the model deadline until input arrives. Queued tools do not start their deadline before execution, and a timer delayed by host suspend or a local event-loop gap is rearmed instead of being charged to the Agent.
Reviewer Test Plan
How to verify
TIMEOUTfinish, persistsfailed, and is not retried.Evidence (Before & After)
Before: an ordinary background Agent has no logical progress deadline; the workflow watchdog is retrying and treats all running tools as unbounded.
After: ordinary background turns have independent model/control and per-tool deadlines and settle cooperative stalls once as
TIMEOUT/failed.Tested on
Environment (optional)
Static diff review and formatting only. No local test, build, typecheck, or CI command was run.
Risk & Scope
Linked Issues
Part of #8586.
Depends on #11265.
中文说明
本 PR 做了什么
为普通后台 Agent 的每个 turn 增加固定进度 watchdog,覆盖首次启动、恢复运行和驻留 Agent 的后续继续。模型/控制流程连续 15 分钟没有可观察进度时超时;每个正在执行的工具各自拥有 10 分钟进度期限。工具输出和静默 shell 存活更新只续期对应工具的期限。
watchdog 到期后会协作式中止该 turn,并上报为
TIMEOUT,随后只持久化和通知一次failed。它不会进入 workflow 的重试循环。如果该 turn 忽略中止,registry 会保留其物理槽位,同时 daemon 排空并替换该 Session 所属的 runtime generation;已有 Session 继续固定在原 owner generation,新任务使用 active replacement。为什么需要
后台 Agent 的模型、控制流程或某个工具停止推进时,registry 仍可能一直把它记录为 running。现有 workflow watchdog 不能直接复用,因为它会重试,而且会对所有运行中的工具暂停计时。结果是普通后台 Agent 可能无限卡住,并持续占用 Session,且永远没有终态结果。
审批等待会暂停对应工具的期限。无工具 round 在等待 Monitor 所属外部输入时,会暂停模型期限,直到输入到达。排队中的工具不会在真正执行前开始计时;由主机休眠或本地事件循环卡顿导致的延迟定时器会重新计时,而不是归咎于 Agent。
Reviewer Test Plan
如何验证
TIMEOUTfinish,持久化为failed,并且不重试。证据(Before & After)
Before:普通后台 Agent 没有逻辑进度期限;workflow watchdog 会重试,并把所有运行工具视为无界等待。
After:普通后台 turn 拥有独立的模型/控制和逐工具期限,协作式停滞只会结算一次为
TIMEOUT/failed。已测试平台
环境(可选)
只做了静态 diff 复核和格式化。未运行本地测试、build、typecheck 或 CI 命令。
风险与范围
关联 Issue
属于 #8586 的一部分。
依赖 #11265。